



[ad_1]
Graph Neural Networks (GNNs) are highly effective instruments for leveraging graph-structured knowledge in machine studying. Graphs are versatile knowledge buildings that may mannequin many various sorts of relationships and have been utilized in various purposes like site visitors prediction, rumor and faux information detection, modeling illness unfold, and understanding why molecules odor.
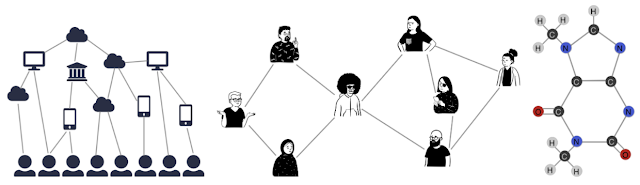 |
| Graphs can mannequin the relationships between many various kinds of knowledge, together with internet pages (left), social connections (heart), or molecules (proper). |
As is customary in machine studying (ML), GNNs assume that coaching samples are chosen uniformly at random (i.e., are an unbiased and identically distributed or “IID” pattern). That is simple to do with customary educational datasets, that are particularly created for analysis evaluation and subsequently have each node already labeled. Nevertheless, in lots of actual world eventualities, knowledge comes with out labels, and labeling knowledge may be an onerous course of involving expert human raters, which makes it troublesome to label all nodes. As well as, biased coaching knowledge is a standard difficulty as a result of the act of choosing nodes for labeling is normally not IID. For instance, typically mounted heuristics are used to pick a subset of information (which shares some traits) for labeling, and different instances, human analysts individually select knowledge objects for labeling utilizing complicated area data.
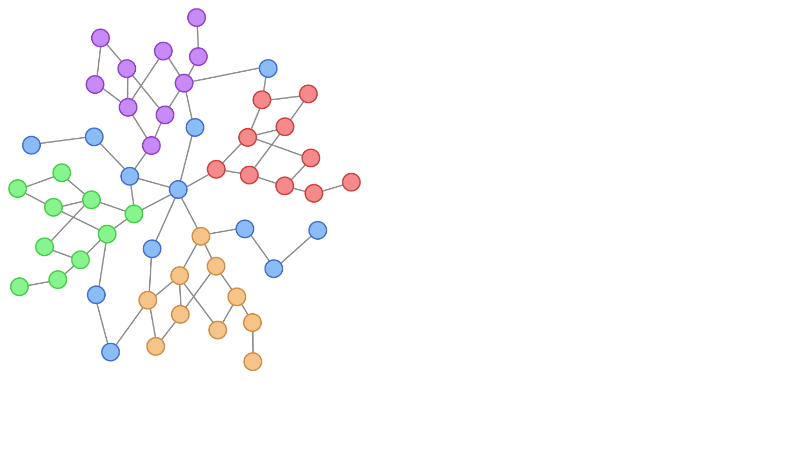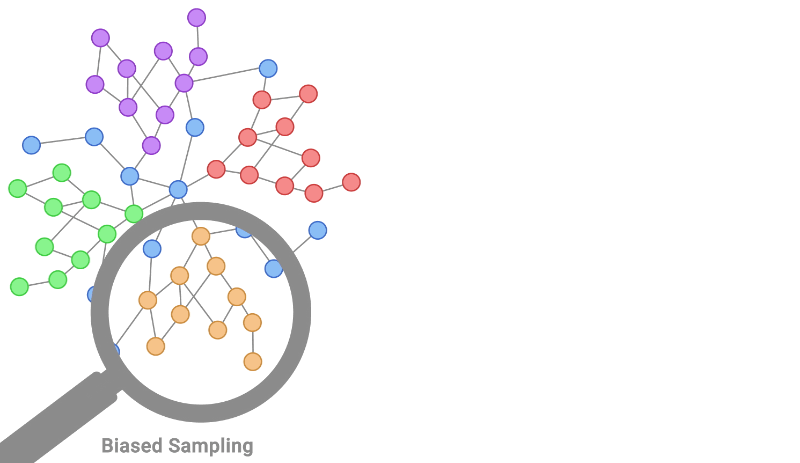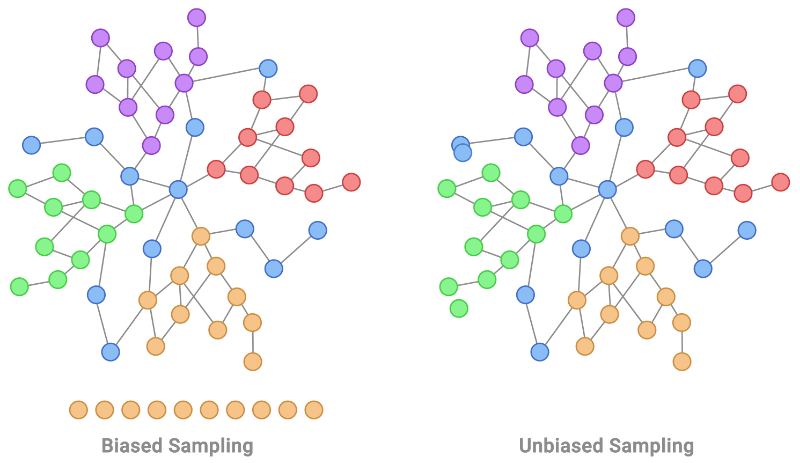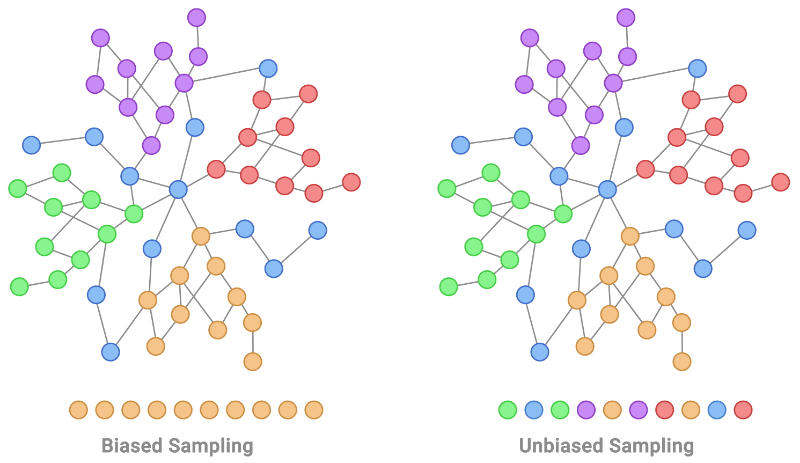 |
| Localized coaching knowledge is a typical non-IID bias exhibited in graph-structured knowledge. That is proven on the left determine by taking an orange node and increasing to these round it. As an alternative, an IID coaching pattern of nodes for labeling could be uniformly distributed, as illustrated by the sampling course of on the proper. |
To quantify the quantity of bias current in a coaching set, one can use strategies that measure how giant the shift is between two totally different likelihood distributions, the place the scale of the shift may be considered the quantity of bias. Because the shift grows in dimension, machine studying fashions have extra problem generalizing from the biased coaching set. This example can meaningfully harm generalizability — on educational datasets, we’ve noticed area shifts inflicting a efficiency drop of 15-20% (as measured by the F1 rating).
In “Shift-Strong GNNs: Overcoming the Limitations of Localized Graph Coaching Knowledge”, offered at NeurIPS 2021, we introduce an answer for utilizing GNNs on biased knowledge. Referred to as Shift-Strong GNN (SR-GNN), this method is designed to account for distributional variations between biased coaching knowledge and a graph’s true inference distribution. SR-GNN adapts GNN fashions to the presence of distributional shift between the nodes labeled for coaching and the remainder of the dataset. We illustrate the effectiveness of SR-GNN in a wide range of experiments with biased coaching datasets on widespread GNN benchmark datasets for semi-supervised studying and present that SR-GNN outperforms different GNN baselines in accuracy, lowering the unfavorable results of biased coaching knowledge by 30–40%.
The Impression of Distribution Shifts on Efficiency
To display how distribution shift impacts GNN efficiency, we first generate numerous biased coaching units for recognized educational datasets. Then so as to perceive the impact, we plot the generalization (take a look at accuracy) versus a measure of distribution shift (the Central Second Discrepancy1, CMD). For instance, think about the well-known PubMed quotation dataset, which may be considered a graph the place the nodes are medical analysis papers and the sides characterize citations between them. Once we generate biased coaching knowledge for PubMed, the plot appears like this:
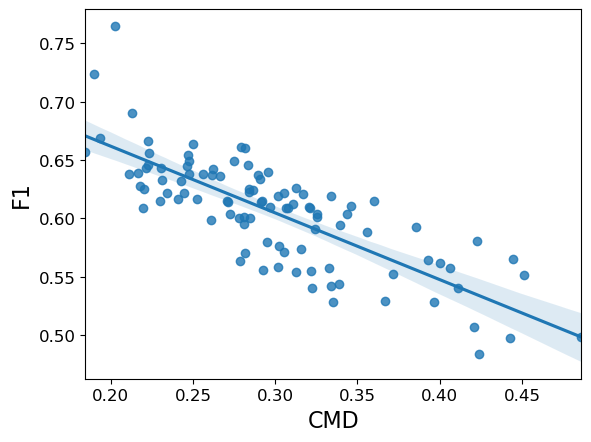 |
| The impact of distribution shift on the PubMed dataset. Efficiency (F1) is proven on the y-axis vs. the distribution shift, Central Second Discrepancy (CMD), on the x-axis, for 100 biased coaching set samples. Because the distribution shift will increase, the mannequin’s accuracy falls. |
Right here one can observe a robust unfavorable correlation between the distribution shift within the dataset and the classification accuracy: as CMD will increase, the efficiency (F1) decreases. That’s, GNNs can have problem generalizing as their coaching knowledge appears much less just like the take a look at dataset.
To deal with this, we suggest a shift-robust regularizer (related in thought to domain-invariant studying) to reduce the distribution shift between coaching knowledge and an IID pattern from unlabeled knowledge. To do that, we measure the area shift (e.g., through CMD) in actual time because the mannequin is coaching and apply a direct penalty primarily based on this that forces the mannequin to disregard as a lot of the coaching bias as potential. This forces the characteristic encoders that the mannequin learns for the coaching knowledge to additionally work successfully for any unlabeled knowledge, which could come from a unique distribution.
The determine beneath exhibits what this appears like when in comparison with a standard GNN mannequin. We nonetheless have the identical inputs (the node options X, and the Adjacency Matrix A), and the identical variety of layers. Nevertheless on the remaining embedding Zokay from layer (okay) of the GNN is in contrast towards embeddings from unlabeled knowledge factors to confirm that the mannequin is accurately encoding them.
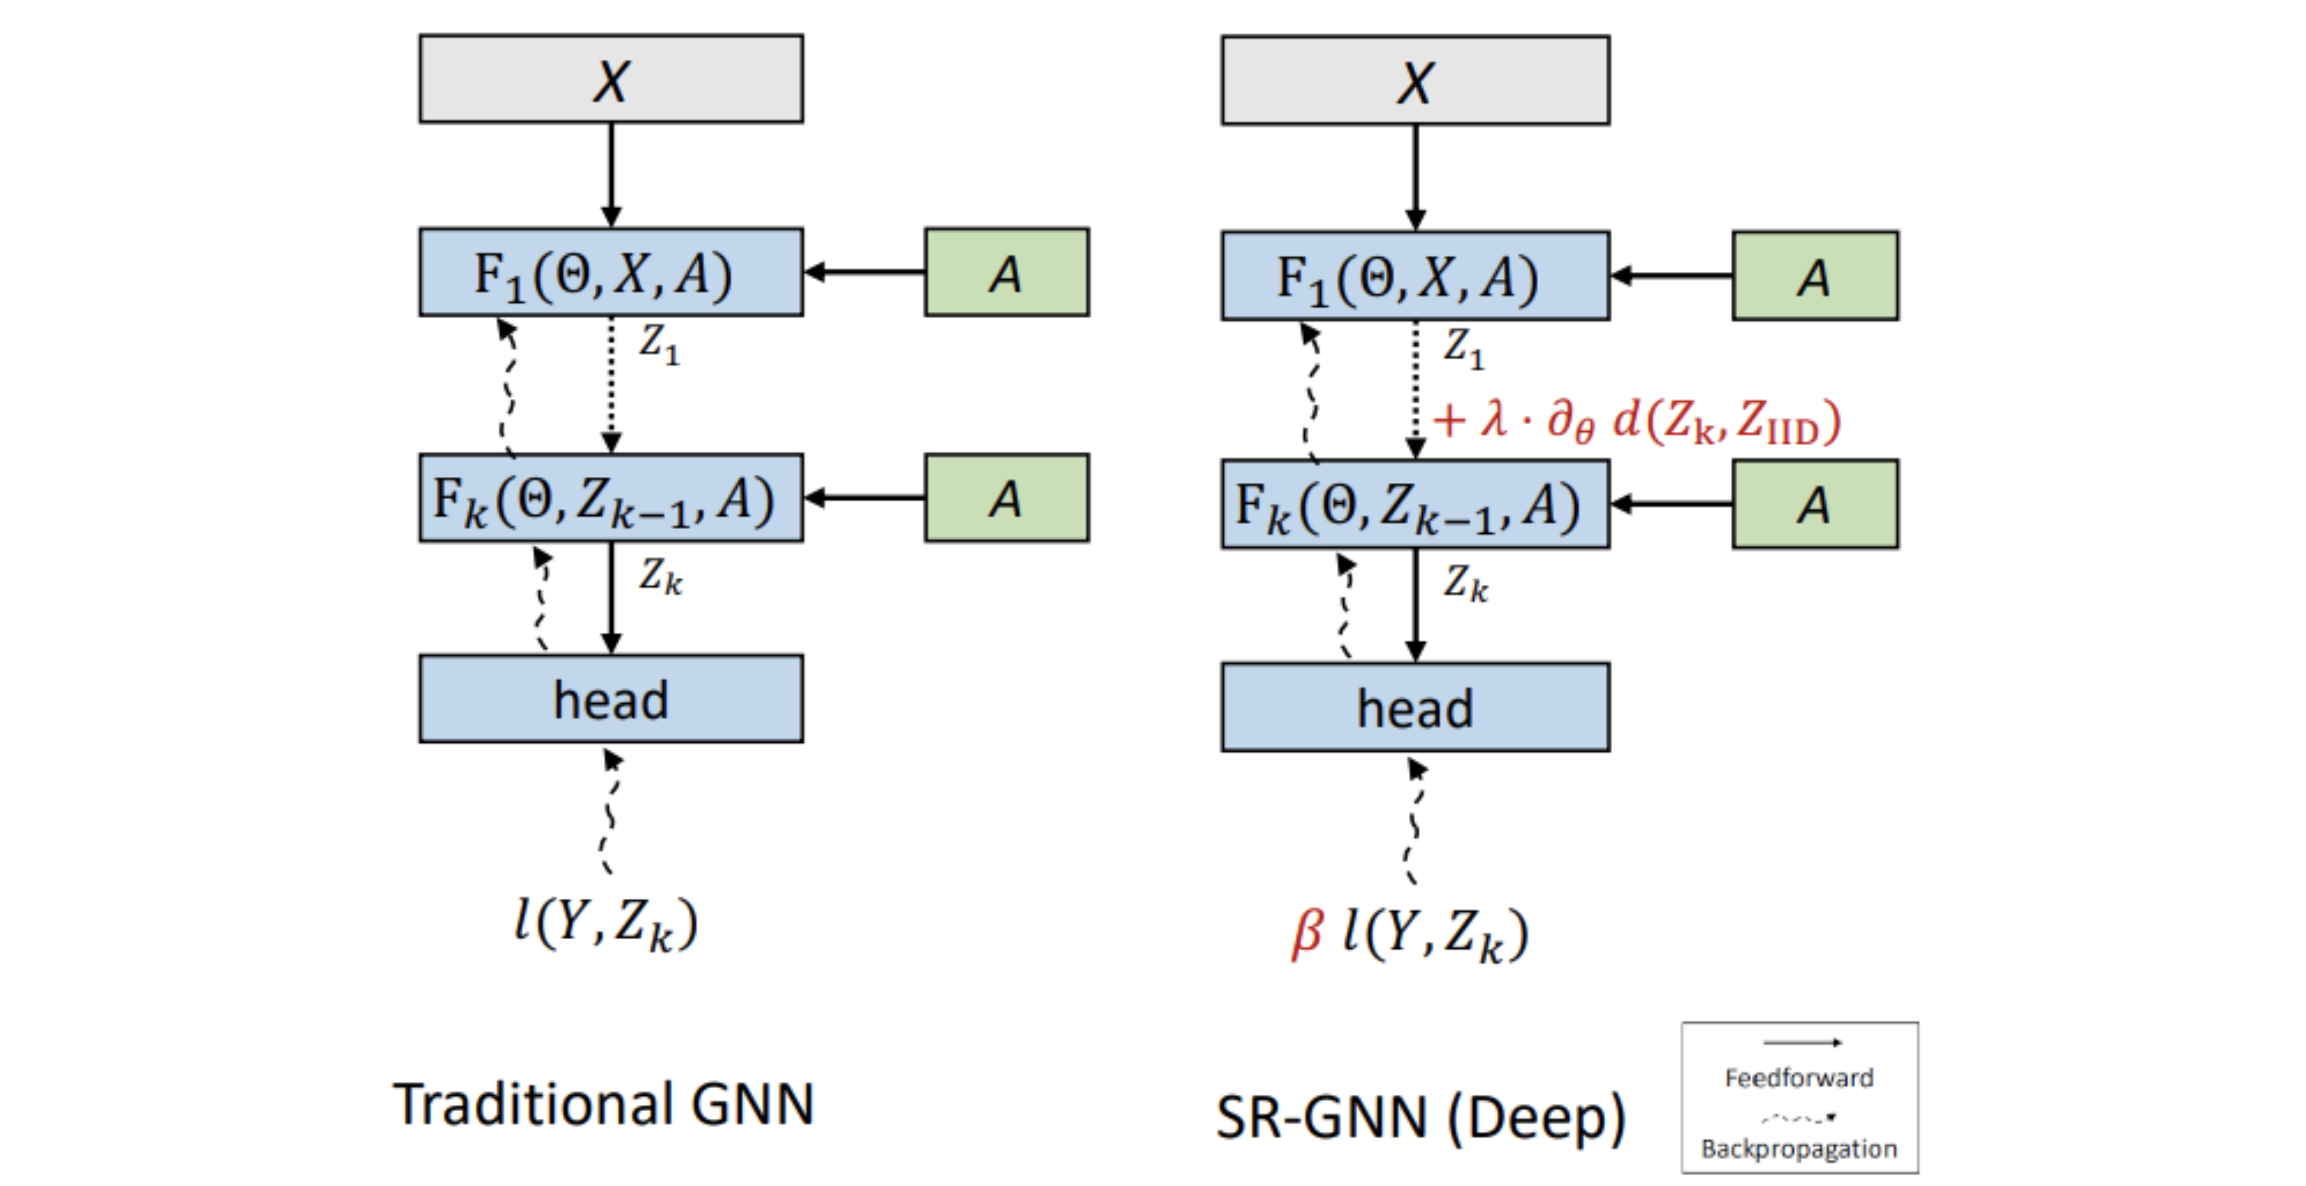 |
| SR-GNN provides two sorts of regularizations to deep GNN fashions. First, a website shift regularization (λ time period) minimizes the space between hidden representations of the labeled (Zokay) and unlabeled (ZIID) knowledge. Second, the occasion weight (β) of the examples may be modified to additional approximate the true distribution. |
We write this regularization as an extra time period within the formulation for the mannequin’s loss primarily based on the space between the coaching knowledge’s representations and the true knowledge’s distribution (full formulation out there within the paper).
In our experiments, we evaluate our technique and numerous customary graph neural community fashions, to measure their efficiency on node classification duties. We display that including the SR-GNN regularization offers a 30–40% p.c enchancment on classification duties with biased coaching knowledge labels.
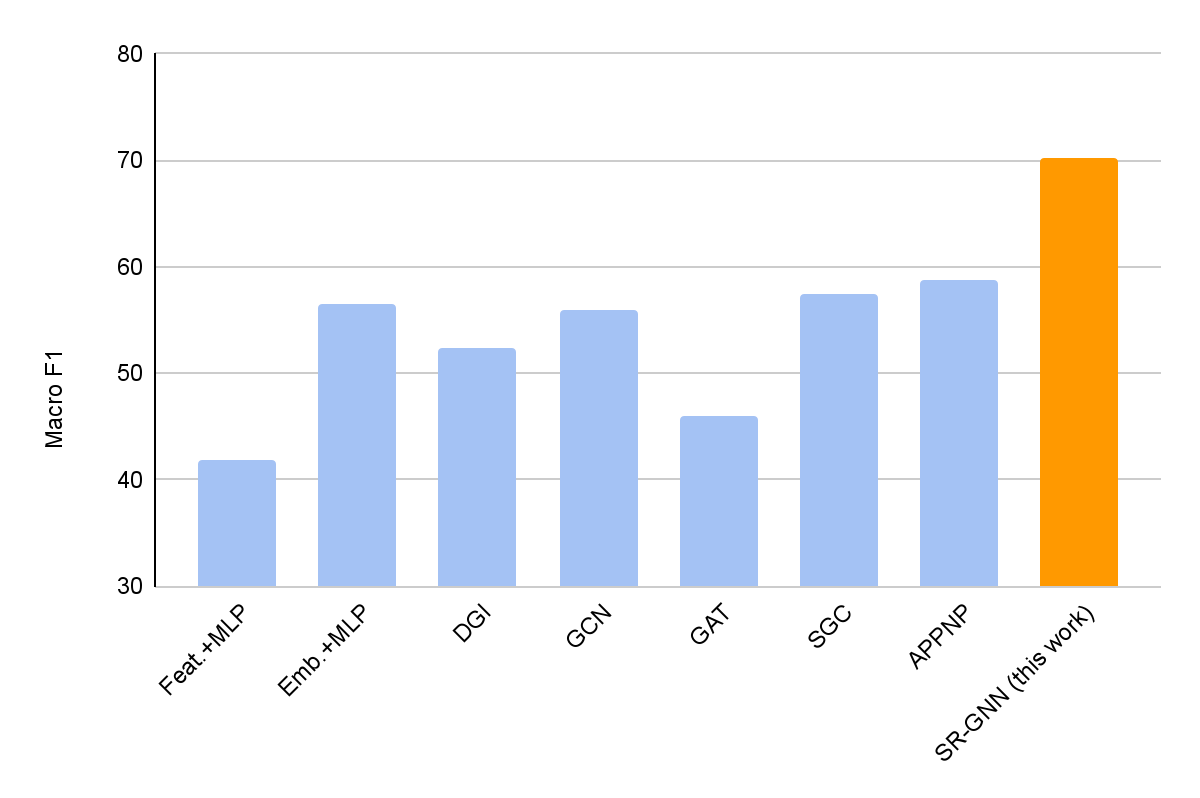 |
| A comparability of SR-GNN utilizing node classification with biased coaching knowledge on the PubMed dataset. SR-GNN outperforms seven baselines, together with DGI, GCN, GAT, SGC and APPNP. |
Shift-Strong Regularization for Linear GNNs through Occasion Re-weighting
Furthermore, it’s price noting that there’s one other class of GNN fashions (e.g., APPNP, SimpleGCN, and so forth) which are primarily based on linear operations to hurry up their graph convolutions. We additionally examined tips on how to make these fashions extra dependable within the presence of biased coaching knowledge. Whereas the identical regularization mechanism can’t be immediately utilized attributable to their totally different structure, we will “right” the coaching bias by re-weighting the coaching cases in response to their distance from an approximated true distribution. This permits correcting the distribution of the biased coaching knowledge with out passing gradients by the mannequin.
Lastly, the 2 regularizations — for each deep and linear GNNs — may be mixed right into a generalized regularization for the loss, which mixes each area regularization and occasion reweighting (particulars, together with the loss formulation, out there within the paper).
Conclusion
Biased coaching knowledge is widespread in actual world eventualities and may come up attributable to a wide range of causes, together with difficulties of labeling a considerable amount of knowledge, the varied heuristics or inconsistent strategies which are used to decide on nodes for labeling, delayed label project, and others. We offered a basic framework (SR-GNN) that may scale back the affect of biased coaching knowledge and may be utilized to varied sorts of GNNs, together with each deeper GNNs and more moderen linearized (shallow) variations of those fashions.
Acknowledgements
Qi Zhu is a PhD Scholar at UIUC. Because of our collaborators Natalia Ponomareva (Google Analysis) and Jiawei Han (UIUC). Because of Tom Small and Anton Tsitsulin for visualizations.
1We be aware that many measures of distribution shift have been proposed within the literature. Right here we use CMD (as it’s fast to calculate and customarily exhibits good efficiency within the area adaptation literature), however the idea generalizes to any measure of distribution distances/area shift. ↩
[ad_2]

