



[ad_1]
In 2017, Google launched federated studying (FL), an method that permits cellular units to collaboratively prepare machine studying (ML) fashions whereas maintaining the uncooked coaching information on every person’s system, decoupling the flexibility to do ML from the necessity to retailer the information within the cloud. Since its introduction, Google has continued to actively have interaction in FL analysis and deployed FL to energy many options in Gboard, together with subsequent phrase prediction, emoji suggestion and out-of-vocabulary phrase discovery. Federated studying is enhancing the “Hey Google” detection fashions in Assistant, suggesting replies in Google Messages, predicting textual content alternatives, and extra.
Whereas FL permits ML with out uncooked information assortment, differential privateness (DP) gives a quantifiable measure of information anonymization, and when utilized to ML can handle considerations about fashions memorizing delicate person information. This too has been a prime analysis precedence, and has yielded one of many first manufacturing makes use of of DP for analytics with RAPPOR in 2014, our open-source DP library, Pipeline DP, and TensorFlow Privateness.
By means of a multi-year, multi-team effort spanning elementary analysis and product integration, as we speak we’re excited to announce that we’ve got deployed a manufacturing ML mannequin utilizing federated studying with a rigorous differential privateness assure. For this proof-of-concept deployment, we utilized the DP-FTRL algorithm to coach a recurrent neural community to energy next-word-prediction for Spanish-language Gboard customers. To our information, that is the primary manufacturing neural community educated immediately on person information introduced with a proper DP assure (technically ρ=0.81 zero-Concentrated-Differential-Privateness, zCDP, mentioned intimately beneath). Additional, the federated method provides complimentary information minimization benefits, and the DP assure protects the entire information on every system, not simply particular person coaching examples.
Knowledge Minimization and Anonymization in Federated Studying
Together with fundamentals like transparency and consent, the privateness ideas of information minimization and anonymization are essential in ML functions that contain delicate information.
Federated studying methods structurally incorporate the precept of information minimization. FL solely transmits minimal updates for a particular mannequin coaching activity (targeted assortment), limits entry to information in any respect phases, processes people’ information as early as potential (early aggregation), and discards each collected and processed information as quickly as potential (minimal retention).
One other precept that’s essential for fashions educated on person information is anonymization, which means that the ultimate mannequin mustn’t memorize info distinctive to a selected particular person’s information, e.g., cellphone numbers, addresses, bank card numbers. Nonetheless, FL by itself doesn’t immediately deal with this drawback.
The mathematical idea of DP permits one to formally quantify this precept of anonymization. Differentially personal coaching algorithms add random noise throughout coaching to provide a likelihood distribution over output fashions, and be sure that this distribution does not change an excessive amount of given a small change to the coaching information; ρ-zCDP quantifies how a lot the distribution may probably change. We name this example-level DP when including or eradicating a single coaching instance modifications the output distribution on fashions in a provably minimal method.
Exhibiting that deep studying with example-level differential privateness was even potential within the easier setting of centralized coaching was a significant step ahead in 2016. Achieved by the DP-SGD algorithm, the important thing was amplifying the privateness assure by leveraging the randomness in sampling coaching examples (“amplification-via-sampling”).
Nonetheless, when customers can contribute a number of examples to the coaching dataset, example-level DP isn’t essentially robust sufficient to make sure the customers’ information is not memorized. As a substitute, we’ve got designed algorithms for user-level DP, which requires that the output distribution of fashions does not change even when we add/take away all of the coaching examples from anyone person (or all of the examples from anyone system in our utility). Luckily, as a result of FL summarizes all of a person’s coaching information as a single mannequin replace, federated algorithms are well-suited to providing user-level DP ensures.
Each limiting the contributions from one person and including noise can come on the expense of mannequin accuracy, nonetheless, so sustaining mannequin high quality whereas additionally offering robust DP ensures is a key analysis focus.
The Difficult Path to Federated Studying with Differential Privateness
In 2018, we launched the DP-FedAvg algorithm, which prolonged the DP-SGD method to the federated setting with user-level DP ensures, and in 2020 we deployed this algorithm to cellular units for the primary time. This method ensures the coaching mechanism isn’t too delicate to anyone person’s information, and empirical privateness auditing strategies rule out some types of memorization.
Nonetheless, the amplification-via-samping argument is important to offering a robust DP assure for DP-FedAvg, however in a real-world cross-device FL system making certain units are subsampled exactly and uniformly at random from a big inhabitants can be complicated and laborious to confirm. One problem is that units select when to attach (or “test in”) primarily based on many exterior elements (e.g., requiring the system is idle, on unmetered WiFi, and charging), and the variety of accessible units can differ considerably.
Attaining a proper privateness assure requires a protocol that does all of the next:
- Makes progress on coaching even because the set of units accessible varies considerably with time.
- Maintains privateness ensures even within the face of sudden or arbitrary modifications in system availability.
- For effectivity, permits consumer units to regionally resolve whether or not they may test in to the server as a way to take part in coaching, impartial of different units.
Preliminary work on privateness amplification by way of random check-ins highlighted these challenges and launched a possible protocol, however it will have required complicated modifications to our manufacturing infrastructure to deploy. Additional, as with the amplification-via-sampling evaluation of DP-SGD, the privateness amplification potential with random check-ins is dependent upon a lot of units being accessible. For instance, if solely 1000 units can be found for coaching, and participation of not less than 1000 units is required in every coaching step, that requires both 1) together with all units at the moment accessible and paying a big privateness value since there isn’t a randomness within the choice, or 2) pausing the protocol and never making progress till extra units can be found.
Attaining Provable Differential Privateness for Federated Studying with DP-FTRL
To deal with this problem, the DP-FTRL algorithm is constructed on two key observations: 1) the convergence of gradient-descent-style algorithms relies upon primarily not on the accuracy of particular person gradients, however the accuracy of cumulative sums of gradients; and a pair of) we will present correct estimates of cumulative sums with a robust DP assure by using negatively correlated noise, added by the aggregating server: basically, including noise to 1 gradient and subtracting that very same noise from a later gradient. DP-FTRL accomplishes this effectively utilizing the Tree Aggregation algorithm [1, 2].
The graphic beneath illustrates how estimating cumulative sums moderately than particular person gradients can assist. We take a look at how the noise launched by DP-FTRL and DP-SGD affect mannequin coaching, in comparison with the true gradients (with out added noise; in black) which the first step unit to the best on every iteration. The person DP-FTRL gradient estimates (blue), primarily based on cumulative sums, have bigger mean-squared-error than the individually-noised DP-SGD estimates (orange), however as a result of the DP-FTRL noise is negatively correlated, a few of it cancels out from step to step, and the general studying trajectory stays nearer to the true gradient descent steps.
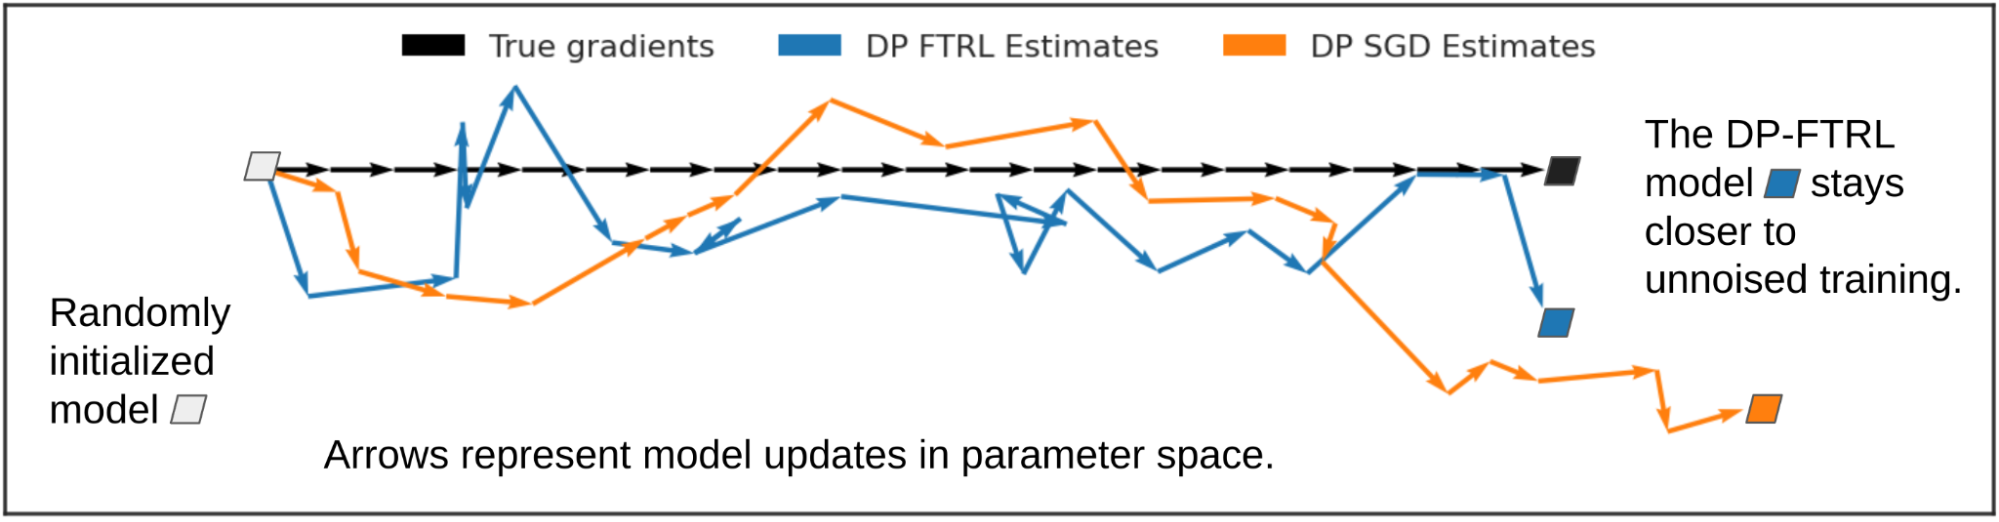 |
To supply a robust privateness assure, we restrict the variety of occasions a person contributes an replace. Luckily, sampling-without-replacement is comparatively straightforward to implement in manufacturing FL infrastructure: every system can bear in mind regionally which fashions it has contributed to up to now, and select to not connect with the server for any later rounds for these fashions.
Manufacturing Coaching Particulars and Formal DP Statements
For the manufacturing DP-FTRL deployment launched above, every eligible system maintains an area coaching cache consisting of person keyboard enter, and when taking part computes an replace to the mannequin which makes it extra prone to recommend the subsequent phrase the person really typed, primarily based on what has been typed thus far. We ran DP-FTRL on this information to coach a recurrent neural community with ~1.3M parameters. Coaching ran for 2000 rounds over six days, with 6500 units taking part per spherical. To permit for the DP assure, units participated in coaching at most as soon as each 24 hours. Mannequin high quality improved over the earlier DP-FedAvg educated mannequin, which supplied empirically-tested privateness benefits over non-DP fashions, however lacked a significant formal DP assure.
The coaching mechanism we used is out there in open-source in TensorFlow Federated and TensorFlow Privateness, and with the parameters utilized in our manufacturing deployment it gives a meaningfully robust privateness assure. Our evaluation offers ρ=0.81 zCDP on the person stage (treating all the information on every system as a distinct person), the place smaller numbers correspond to raised privateness in a mathematically exact method. As a comparability, that is stronger than the ρ=2.63 zCDP assure chosen by the 2020 US Census.
Subsequent Steps
Whereas we’ve got reached the milestone of deploying a manufacturing FL mannequin utilizing a mechanism that gives a meaningfully small zCDP, our analysis journey continues. We’re nonetheless removed from with the ability to say this method is feasible (not to mention sensible) for many ML fashions or product functions, and different approaches to personal ML exist. For instance, membership inference checks and different empirical privateness auditing strategies can present complimentary safeguards towards leakage of customers’ information. Most significantly, we see coaching fashions with user-level DP with even a really massive zCDP as a considerable step ahead, as a result of it requires coaching with a DP mechanism that bounds the sensitivity of the mannequin to anyone person’s information. Additional, it smooths the street to later coaching fashions with improved privateness ensures as higher algorithms or extra information change into accessible. We’re excited to proceed the journey towards maximizing the worth that ML can ship whereas minimizing potential privateness prices to those that contribute coaching information.
Acknowledgements
The authors wish to thank Alex Ingerman and Om Thakkar for vital influence on the weblog put up itself, in addition to the groups at Google that helped develop these concepts and convey them to follow:
- Core analysis crew: Galen Andrew, Borja Balle, Peter Kairouz, Daniel Ramage, Shuang Track, Thomas Steinke, Andreas Terzis, Om Thakkar, Zheng Xu
- FL infrastructure crew: Katharine Daly, Stefan Dierauf, Hubert Eichner, Igor Pisarev, Timon Van Overveldt, Chunxiang Zheng
- Gboard crew: Angana Ghosh, Xu Liu, Yuanbo Zhang
- Speech crew: Françoise Beaufays, Mingqing Chen, Rajiv Mathews, Vidush Mukund, Igor Pisarev, Swaroop Ramaswamy, Dan Zivkovic
[ad_2]

