



[ad_1]
Whereas not instantly apparent, all of us expertise the world in 4 dimensions (4D). For instance, when strolling or driving down the road we observe a stream of visible inputs, snapshots of the 3D world, which, when taken collectively in time, creates a 4D visible enter. At the moment’s autonomous automobiles and robots are capable of seize a lot of this data via varied onboard sensing mechanisms, akin to LiDAR and cameras.
LiDAR is a ubiquitous sensor that makes use of mild pulses to reliably measure the 3D coordinates of objects in a scene, nevertheless, additionally it is sparse and has a restricted vary — the farther one is from a sensor, the less factors will probably be returned. Because of this far-away objects may solely get a handful of factors, or none in any respect, and won’t be seen by LiDAR alone. On the similar time, photographs from the onboard digital camera, which is a dense enter, are extremely helpful for semantic understanding, akin to detecting and segmenting objects. With excessive decision, cameras will be very efficient at detecting objects distant, however are much less correct in measuring the space.
Autonomous automobiles acquire information from each LiDAR and onboard digital camera sensors. Every sensor measurement is recorded at common time intervals, offering an correct illustration of the 4D world. Nevertheless, only a few analysis algorithms use each of those together, particularly when taken “in time”, i.e., as a temporally ordered sequence of knowledge, principally as a consequence of two main challenges. When utilizing each sensing modalities concurrently, 1) it’s troublesome to keep up computational effectivity, and a couple of) pairing the data from one sensor to a different provides additional complexity since there may be not all the time a direct correspondence between LiDAR factors and onboard digital camera RGB picture inputs.
In “4D-Web for Realized Multi-Modal Alignment”, revealed at ICCV 2021, we current a neural community that may course of 4D information, which we name 4D-Web. That is the primary try to successfully mix each forms of sensors, 3D LiDAR level clouds and onboard digital camera RGB photographs, when each are in time. We additionally introduce a dynamic connection studying methodology, which contains 4D data from a scene by performing connection studying throughout each function representations. Lastly, we exhibit that 4D-Web is healthier ready to make use of movement cues and dense picture data to detect distant objects whereas sustaining computational effectivity.
4D-Web
In our state of affairs, we use 4D inputs (3D level clouds and onboard digital camera picture information in time) to resolve a very talked-about visible understanding activity, the 3D field detection of objects. We examine the query of how one can mix the 2 sensing modalities, which come from completely different domains and have options that don’t essentially match — i.e., sparse LiDAR inputs span the 3D house and dense digital camera photographs solely produce 2D projections of a scene. The precise correspondence between their respective options is unknown, so we search to study the connections between these two sensor inputs and their function representations. We think about neural community representations the place every of the function layers will be mixed with different potential layers from different sensor inputs, as proven beneath.
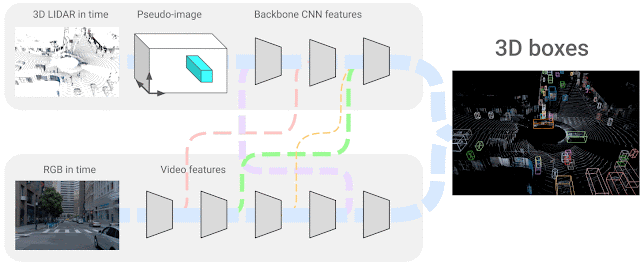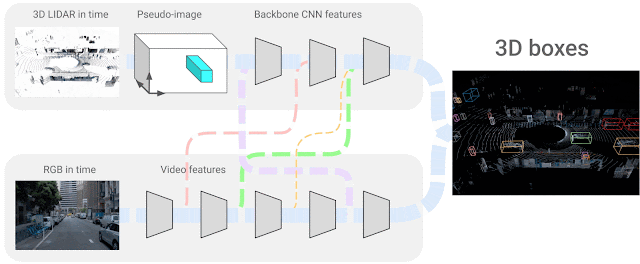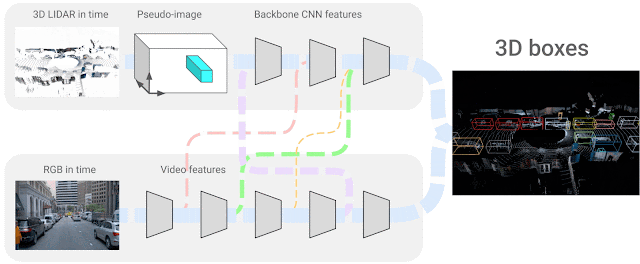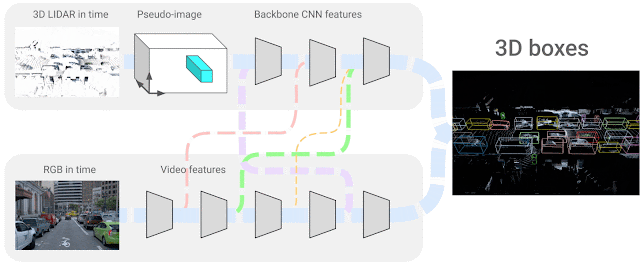 |
| 4D-Web successfully combines 3D LiDAR level clouds in time with RGB photographs, additionally streamed in time as video, studying the connections between completely different sensors and their function representations. |
Dynamic Connection Studying Throughout Sensing Modalities
We use a lightweight neural structure search to study the connections between each forms of sensor inputs and their function representations, to acquire essentially the most correct 3D field detection. Within the autonomous driving area it’s particularly vital to reliably detect objects at extremely variable distances, with trendy LiDAR sensors reaching a number of lots of of meters in vary. This means that extra distant objects will seem smaller within the photographs and essentially the most priceless options for detecting them will probably be in earlier layers of the community, which higher seize fine-scale options, versus close-by objects represented by later layers. Based mostly on this statement, we modify the connections to be dynamic and choose amongst options from all layers utilizing self-attention mechanisms. We apply a learnable linear layer, which is ready to apply attention-weighting to all different layer weights and study the very best mixture for the duty at hand.
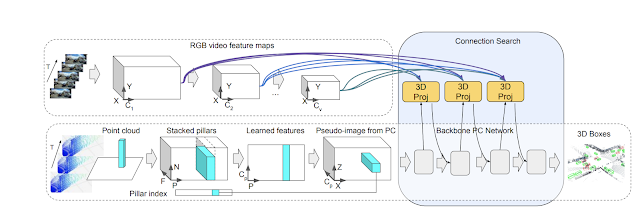 |
| Connection studying method schematic, the place connections between options from the 3D level cloud inputs are mixed with the options from the RGB digital camera video inputs. Every connection learns the weighting for the corresponding inputs. |
Outcomes
We consider our outcomes towards state-of-the-art approaches on the Waymo Open Dataset benchmark, for which earlier fashions have solely leveraged 3D level clouds in time or a mixture of a single level cloud and digital camera picture information. 4D-Web makes use of each sensor inputs effectively, processing 32 level clouds in time and 16 RGB frames inside 164 milliseconds, and performs properly in comparison with different strategies. As compared, the subsequent finest method is much less environment friendly and correct as a result of its neural web computation takes 300 milliseconds, and makes use of fewer sensor inputs than 4D-Web.
 |
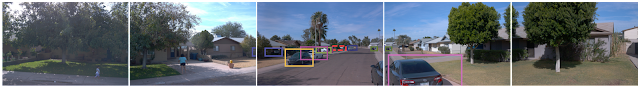 |
| Outcomes on a 3D scene. Prime: 3D packing containers, akin to detected automobiles, are proven in several colours; dotted line packing containers are for objects that have been missed. Backside: The packing containers are proven within the corresponding digital camera photographs for visualization functions. |
Detecting Far-Away Objects
One other advantage of 4D-Web is that it takes benefit of each the excessive decision supplied by RGB, which might precisely detect objects on the picture aircraft, and the correct depth that the purpose cloud information offers. Consequently, objects at a larger distance that have been beforehand missed by level cloud-only approaches will be detected by a 4D-Web. That is as a result of fusion of digital camera information, which is ready to detect distant objects, and effectively propagate this data to the 3D a part of the community to provide correct detections.
Is Information in Time Precious?
To know the worth of the 4D-Web, we carry out a collection of ablation research. We discover that substantial enhancements in detection accuracy are obtained if at the least one of many sensor inputs is streamed in time. Contemplating each sensor inputs in time offers the biggest enhancements in efficiency.
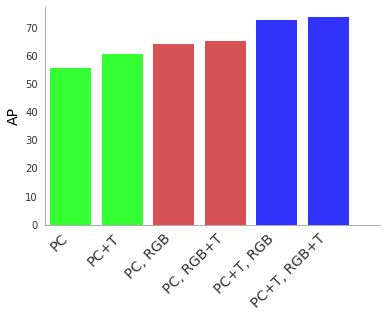 |
| 4D-Web efficiency for 3D object detection measured in common precision (AP) when utilizing level clouds (PC), Level Clouds in Time (PC + T), RGB picture inputs (RGB) and RGB photographs in Time (RGB + T). Combining each sensor inputs in time is finest (rightmost columns in blue) in comparison with the left-most columns (inexperienced) which use a PC with out RGB inputs. All joint strategies use our 4D-Web multi-modal studying. |
Multi-stream 4D-Web
Because the 4D-Web dynamic connection studying mechanism is normal, we’re not restricted to solely combining some extent cloud stream with an RGB video stream. In reality, we discover that it is extremely cost-effective to supply a big decision single-image stream, and a low-resolution video stream along side 3D level cloud stream inputs. Under, we exhibit examples of a four-stream structure, which performs higher than the two-stream one with level clouds in time and pictures in time.
Dynamic connection studying selects particular function inputs to attach collectively. With a number of enter streams, 4D-Web has to study connections between a number of goal function representations, which is easy because the algorithm doesn’t change and easily selects particular options from the union of inputs. That is an extremely lightweight course of that makes use of a differentiable structure search, which might uncover new wiring throughout the mannequin structure itself and thus successfully discover new 4D-Web fashions.
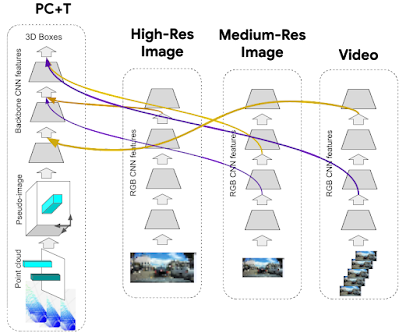 |
| Instance multi-stream 4D-Web which consists of a stream of 3D level clouds in time (PC+T), and a number of picture streams: a high-resolution single picture stream, a medium-resolution single picture stream and a video stream (of even decrease decision) photographs. |
Abstract
Whereas deep studying has made great advances in real-life functions, the analysis group is simply starting to discover studying from a number of sensing modalities. We current 4D-Web which learns learn how to mix 3D level clouds in time and RGB digital camera photographs in time, for the favored software of 3D object detection in autonomous driving. We exhibit that 4D-Web is an efficient method for detecting objects, particularly at distant ranges. We hope this work will present researchers with a priceless useful resource for future 4D information analysis.
Acknowledgements
This work is finished by AJ Piergiovanni, Vincent Casser, Michael Ryoo and Anelia Angelova. We thank our collaborators, Vincent Vanhoucke, Dragomir Anguelov and our colleagues at Waymo and Robotics at Google for his or her help and discussions. We additionally thank Tom Small for the graphics animation.
[ad_2]

