



[ad_1]
Although we’re dwelling via a time of extraordinary innovation in GPU-accelerated machine studying, the newest analysis papers regularly (and prominently) function algorithms which might be many years, in sure circumstances 70 years previous.
Some may contend that many of those older strategies fall into the camp of ‘statistical evaluation’ somewhat than machine studying, and like thus far the appearance of the sector again solely as far as 1957, with the invention of the Perceptron.
Given the extent to which these older algorithms assist and are enmeshed within the newest tendencies and headline-grabbing developments in machine studying, it’s a contestable stance. So let’s check out among the ‘traditional’ constructing blocks underpinning the newest improvements, in addition to some newer entries which might be making an early bid for the AI corridor of fame.
For straightforward reference, right here’s a clickable index of the algorithms coated on this article.
1: Transformers
In 2017 Google Analysis led a analysis collaboration culminating within the paper Consideration Is All You Want. The work outlined a novel structure that promoted consideration mechanisms from ‘piping’ in encoder/decoder and recurrent community fashions to a central transformational expertise in their very own proper.
The strategy was dubbed Transformer, and has since grow to be a revolutionary methodology in Pure Language Processing (NLP), powering, amongst many different examples, the autoregressive language mannequin and AI poster-child GPT-3.


Transformers elegantly solved the issue of sequence transduction, additionally referred to as ‘transformation’, which is occupied with the processing of enter sequences into output sequences. A transformer additionally receives and manages knowledge in a steady method, somewhat than in sequential batches, permitting a ‘persistence of reminiscence’ which RNN architectures will not be designed to acquire. For a extra detailed overview of transformers, check out our reference article.
In distinction to the Recurrent Neural Networks (RNNs) that had begun to dominate ML analysis within the CUDA period, Transformer structure may be simply parallelized, opening the best way to productively handle a far bigger corpus of knowledge than RNNs.
Standard Utilization
Transformers captured the general public creativeness in 2020 with the discharge of OpenAI’s GPT-3, which boasted a then record-breaking 175 billion parameters. This apparently staggering achievement was finally overshadowed by later tasks, such because the 2021 launch of Microsoft’s Megatron-Turing NLG 530B, which (because the identify suggests) options over 530 billion parameters.

A timeline of hyperscale Transformer NLP tasks. Supply: Microsoft
Transformer structure has additionally crossed over from NLP to pc imaginative and prescient, powering a new technology of picture synthesis frameworks equivalent to OpenAI’s CLIP and DALL-E, which use textual content>picture area mapping to complete incomplete photos and synthesize novel photos from educated domains, amongst a rising variety of associated functions.
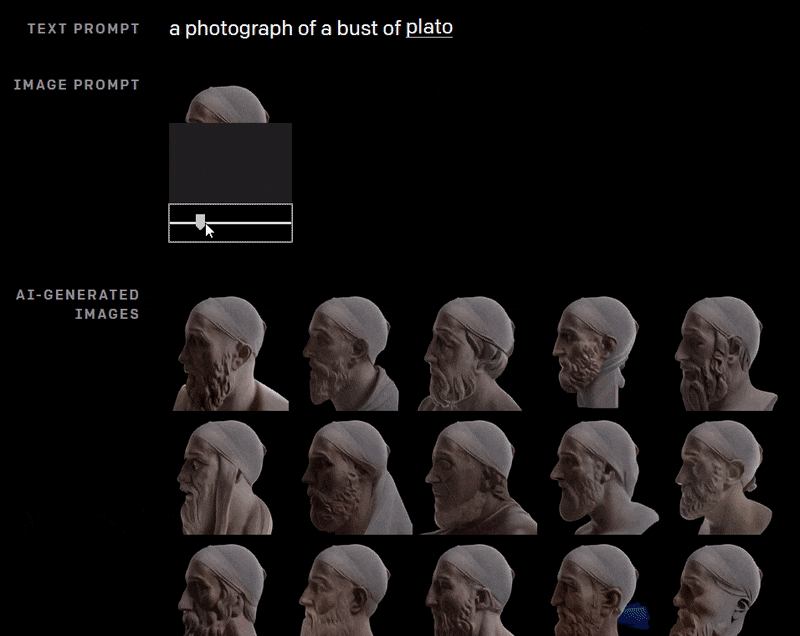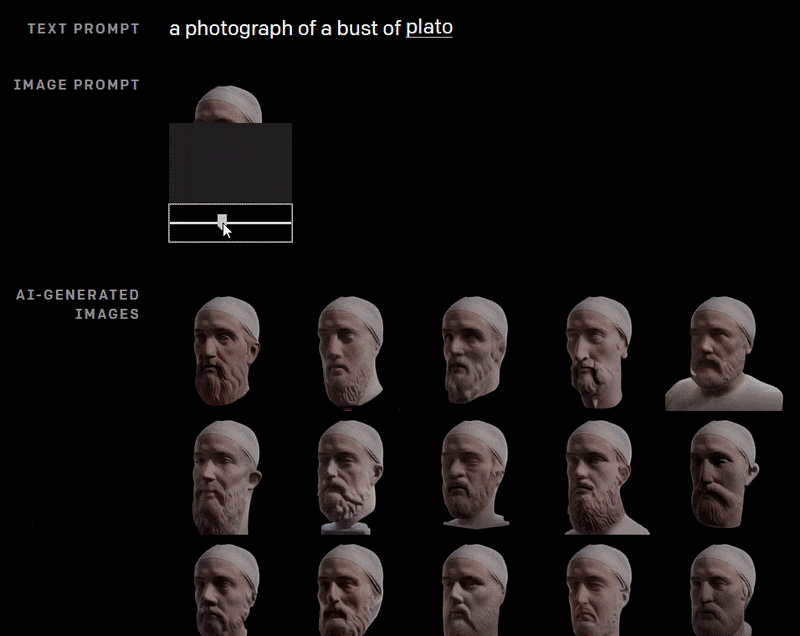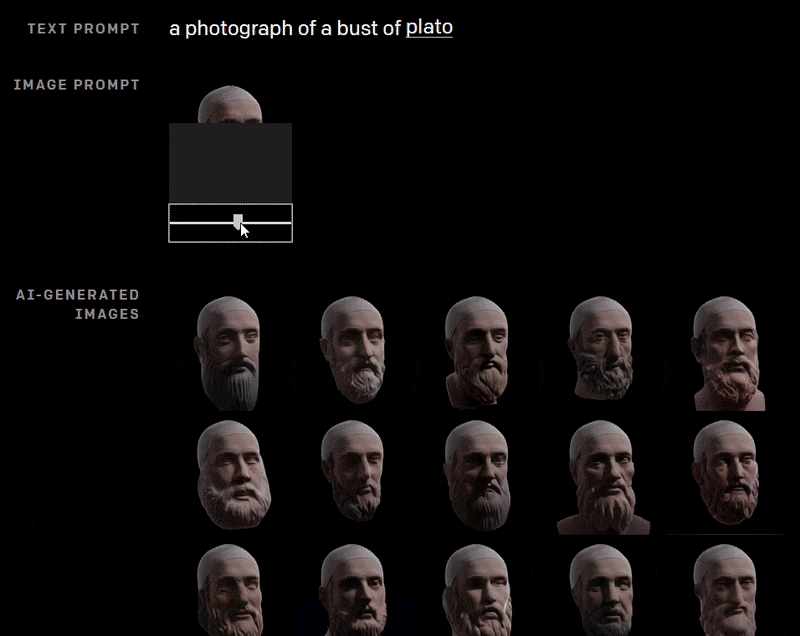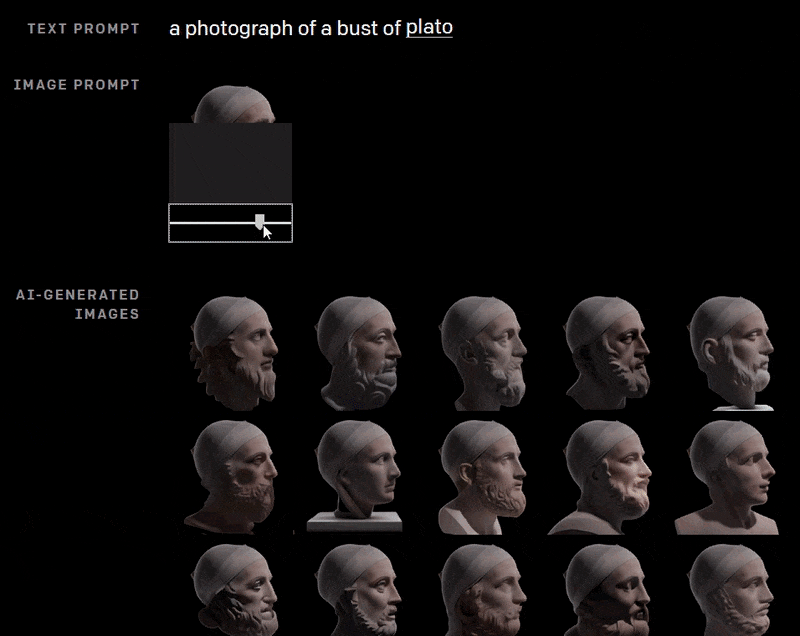
DALL-E makes an attempt to finish a partial picture of a bust of Plato. Supply: https://openai.com/weblog/dall-e/
2: Generative Adversarial Networks (GANs)
Although transformers have gained extraordinary media protection via the discharge and adoption of GPT-3, the Generative Adversarial Community (GAN) has grow to be a recognizable model in its personal proper, and will finally be part of deepfake as a verb.
First proposed in 2014 and primarily used for picture synthesis, a Generative Adversarial Community structure consists of a Generator and a Discriminator. The Generator cycles via 1000’s of photos in a dataset, iteratively making an attempt to reconstruct them. For every try, the Discriminator grades the Generator’s work, and sends the Generator again to do higher, however with none perception into the best way that the earlier reconstruction erred.

Supply: https://builders.google.com/machine-learning/gan/gan_structure
This forces the Generator to discover a multiplicity of avenues, as a substitute of following the potential blind alleys that might have resulted if the Discriminator had informed it the place it was going mistaken (see #8 beneath). By the point the coaching is over, the Generator has an in depth and complete map of relationships between factors within the dataset.
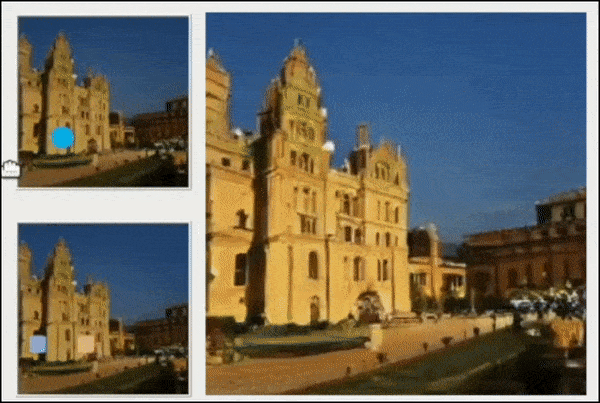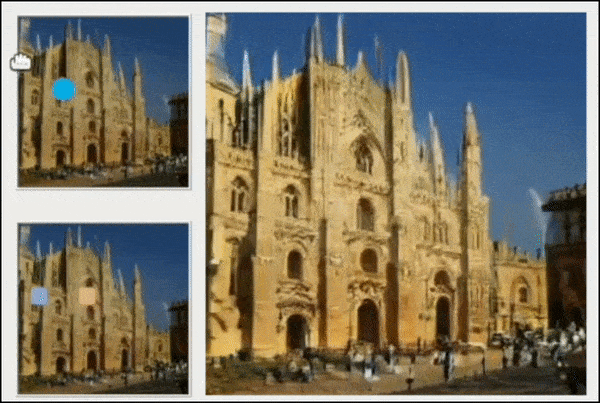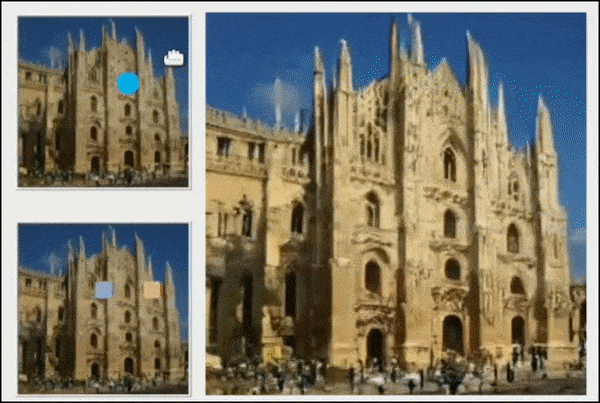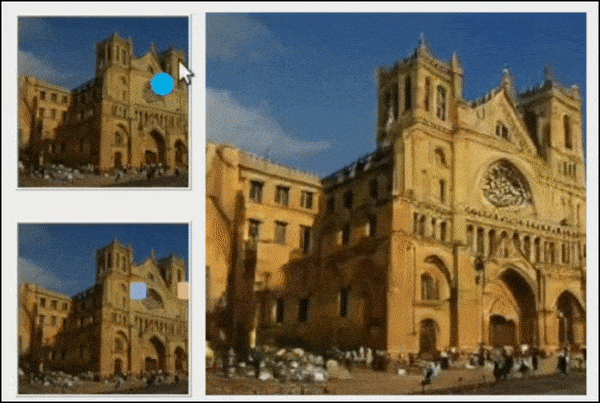
From the paper Bettering GAN Equilibrium by Elevating Spatial Consciousness: a novel framework cycles via the sometimes-mysterious latent house of a GAN, offering responsive instrumentality for a picture synthesis structure. Supply: https://genforce.github.io/eqgan/
By analogy, that is the distinction between studying a single humdrum commute to central London, or painstakingly buying The Data.
The result’s a high-level assortment of options within the latent house of the educated mannequin. The semantic indicator for a excessive stage function might be ‘individual’, while a descent via specificity associated to the function could unearth different realized traits, equivalent to ‘male’ and ‘feminine’. At decrease ranges the sub-features can break right down to, ‘blonde’, ‘Caucasian’, et al.
Entanglement is a notable problem within the latent house of GANs and encoder/decoder frameworks: is the smile on a GAN-generated feminine face an entangled function of her ‘id’ within the latent house, or is it a parallel department?

GAN-generated faces from thispersondoesnotexist. Supply: https://this-person-does-not-exist.com/en
The previous couple of years have introduced forth a rising variety of new analysis initiatives on this respect, maybe paving the best way for feature-level, Photoshop-style modifying for the latent house of a GAN, however in the intervening time, many transformations are successfully ‘all or nothing’ packages. Notably, NVIDIA’s EditGAN launch of late 2021 achieves a excessive stage of interpretability within the latent house by utilizing semantic segmentation masks.
Standard Utilization
Beside their (really pretty restricted) involvement in common deepfake movies, picture/video-centric GANs have proliferated over the past 4 years, enthralling researchers and the general public alike. Maintaining with the dizzying price and frequency of recent releases is a problem, although the GitHub repository Superior GAN Purposes goals to offer a complete record.
Generative Adversarial Networks can in concept derive options from any well-framed area, together with textual content.
3: SVM
Originated in 1963, Assist Vector Machine (SVM) is a core algorithm that crops up regularly in new analysis. Below SVM, vectors map the relative disposition of knowledge factors in a dataset, whereas assist vectors delineate the boundaries between totally different teams, options, or traits.

Assist vectors outline the boundaries between teams. Supply: https://www.kdnuggets.com/2016/07/support-vector-machines-simple-explanation.html
The derived boundary known as a hyperplane.
At low function ranges, the SVM is two-dimensional (picture above), however the place there’s a better acknowledged variety of teams or varieties, it turns into three-dimensional.

A deeper array of factors and teams necessitates a three-dimensional SVM. Supply: https://cml.rhul.ac.uk/svm.html
Standard Utilization
Since assist Vector Machines can successfully and agnostically handle high-dimensional knowledge of many sorts, they crop up extensively throughout a wide range of machine studying sectors, together with deepfake detection, picture classification, hate speech classification, DNA evaluation and inhabitants construction prediction, amongst many others.
4: Ok-Means Clustering
Clustering typically is an unsupervised studying strategy that seeks to categorize knowledge factors via density estimation, making a map of the distribution of the info being studied.

Ok-Means clustering divines segments, teams and communities in knowledge. Supply: https://aws.amazon.com/blogs/machine-learning/k-means-clustering-with-amazon-sagemaker/
Ok-Means Clustering has grow to be the most well-liked implementation of this strategy, shepherding knowledge factors into distinctive ‘Ok Teams’, which can point out demographic sectors, on-line communities, or every other doable secret aggregation ready to be found in uncooked statistical knowledge.

Clusters kind in Ok-Means evaluation. Supply: https://www.geeksforgeeks.org/ml-determine-the-optimal-value-of-k-in-k-means-clustering/
The Ok worth itself is the determinant issue within the utility of the method, and in establishing an optimum worth for a cluster. Initially, the Ok worth is randomly assigned, and its options and vector traits in comparison with its neighbors. These neighbors that the majority carefully resemble the info level with the randomly assigned worth get assigned to its cluster iteratively till the info has yielded all of the groupings that the method permits.
The plot for the squared error, or ‘value’ of differing values among the many clusters will reveal an elbow level for the info:

The ‘elbow level’ in a cluster graph. Supply: https://www.scikit-yb.org/en/newest/api/cluster/elbow.html
The elbow level is comparable in idea to the best way that loss flattens out to diminishing returns on the finish of a coaching session for a dataset. It represents the purpose at which no additional distinctions between teams goes to grow to be obvious, indicating the second to maneuver on to subsequent phases within the knowledge pipeline, or else to report findings.
Standard Utilization
Ok-Means Clustering, for apparent causes, is a major expertise in buyer evaluation, because it presents a transparent and explainable methodology to translate giant portions of economic information into demographic insights and ‘leads’.
Outdoors of this utility, Ok-Means Clustering can also be employed for landslide prediction, medical picture segmentation, picture synthesis with GANs, doc classification, and metropolis planning, amongst many different potential and precise makes use of.
5: Random Forest
Random Forest is an ensemble studying methodology that averages the end result from an array of resolution timber to ascertain an total prediction for the result.

Supply: https://www.tutorialandexample.com/wp-content/uploads/2019/10/Determination-Timber-Root-Node.png
For those who’ve researched it at the same time as little as watching the Again to the Future trilogy, a resolution tree itself is pretty simple to conceptualize: numerous paths lie earlier than you, and every path branches out to a brand new consequence which in flip accommodates additional doable paths.
In reinforcement studying, you may retreat from a path and begin once more from an earlier stance, whereas resolution timber decide to their journeys.
Thus the Random Forest algorithm is basically spread-betting for choices. The algorithm known as ‘random’ as a result of it makes advert hoc choices and observations as a way to perceive the median sum of the outcomes from the choice tree array.
Because it takes under consideration a multiplicity of things, a Random Forest strategy could be tougher to transform into significant graphs than a choice tree, however is prone to be notably extra productive.
Determination timber are topic to overfitting, the place the outcomes obtained are data-specific and never prone to generalize. Random Forest’s arbitrary collection of knowledge factors combats this tendency, drilling via to significant and helpful consultant tendencies within the knowledge.

Determination tree regression. Supply: https://scikit-learn.org/secure/auto_examples/tree/plot_tree_regression.html
Standard Utilization
As with most of the algorithms on this record, Random Forest usually operates as an ‘early’ sorter and filter of knowledge, and as such constantly crops up in new analysis papers. Some examples of Random Forest utilization embody Magnetic Resonance Picture Synthesis, Bitcoin value prediction, census segmentation, textual content classification and bank card fraud detection.
Since Random Forest is a low-level algorithm in machine studying architectures, it could additionally contribute to the efficiency of different low-level strategies, in addition to visualization algorithms, together with Inductive Clustering, Function Transformations, classification of textual content paperwork utilizing sparse options, and displaying Pipelines.
6: Naive Bayes
Coupled with density estimation (see 4, above), a naive Bayes classifier is a strong however comparatively light-weight algorithm able to estimating possibilities primarily based on the calculated options of knowledge.

Function relationships in a naive Bayes classifier. Supply: https://www.sciencedirect.com/subjects/computer-science/naive-bayes-model
The time period ‘naïve’ refers back to the assumption in Bayes’ theorem that options are unrelated, referred to as conditional independence. For those who undertake this standpoint, strolling and speaking like a duck aren’t sufficient to ascertain that we’re coping with a duck, and no ‘apparent’ assumptions are prematurely adopted.
This stage of educational and investigative rigor could be overkill the place ‘widespread sense’ is on the market, however is a helpful customary when traversing the various ambiguities and doubtlessly unrelated correlations that will exist in a machine studying dataset.
In an unique Bayesian community, options are topic to scoring capabilities, together with minimal description size and Bayesian scoring, which might impose restrictions on the info when it comes to the estimated connections discovered between the info factors, and the route by which these connections circulation.
A naive Bayes classifier, conversely, operates by assuming that the options of a given object are impartial, subsequently utilizing Bayes’ theorem to calculate the likelihood of a given object, primarily based on its options.
Standard Utilization
Naive Bayes filters are well-represented in illness prediction and doc categorization, spam filtering, sentiment classification, recommender methods, and fraud detection, amongst different functions.
7: Ok- Nearest Neighbors (KNN)
First proposed by the US Air Drive Faculty of Aviation Drugs in 1951, and having to accommodate itself to the state-of-the-art of mid-Twentieth century computing {hardware}, Ok-Nearest Neighbors (KNN) is a lean algorithm that also options prominently throughout educational papers and personal sector machine studying analysis initiatives.
KNN has been referred to as ‘the lazy learner’, because it exhaustively scans a dataset as a way to consider the relationships between knowledge factors, somewhat than requiring the coaching of a full-fledged machine studying mannequin.

A KNN grouping. Supply: https://scikit-learn.org/secure/modules/neighbors.html
Although KNN is architecturally slender, its systematic strategy does place a notable demand on learn/write operations, and its use in very giant datasets could be problematic with out adjunct applied sciences equivalent to Principal Part Evaluation (PCA), which might rework complicated and excessive quantity datasets into consultant groupings that KNN can traverse with much less effort.
A latest research evaluated the effectiveness and economic system of numerous algorithms tasked to foretell whether or not an worker will go away an organization, discovering that the septuagenarian KNN remained superior to extra fashionable contenders when it comes to accuracy and predictive effectiveness.
Standard Utilization
For all its common simplicity of idea and execution, KNN is just not caught within the Nineteen Fifties – it’s been tailored into a extra DNN-focused strategy in a 2018 proposal by Pennsylvania State College, and stays a central early-stage course of (or post-processing analytical software) in lots of much more complicated machine studying frameworks.
In varied configurations, KNN has been used or for on-line signature verification, picture classification, textual content mining, crop prediction, and facial recognition, apart from different functions and incorporations.

A KNN-based facial recognition system in coaching. Supply: https://pdfs.semanticscholar.org/6f3d/d4c5ffeb3ce74bf57342861686944490f513.pdf
8: Markov Determination Course of (MDP)
A mathematical framework launched by American mathematician Richard Bellman in 1957, The Markov Determination Course of (MDP) is among the most simple blocks of reinforcement studying architectures. A conceptual algorithm in its personal proper, it has been tailored into a large number of different algorithms, and recurs regularly within the present crop of AI/ML analysis.
MDP explores a knowledge surroundings by utilizing its analysis of its present state (i.e. ‘the place’ it’s within the knowledge) to resolve which node of the info to discover subsequent.

Supply: https://www.sciencedirect.com/science/article/abs/pii/S0888613X18304420
A primary Markov Determination Course of will prioritize near-term benefit over extra fascinating long-term goals. For that reason, it’s often embedded into the context of a extra complete coverage structure in reinforcement studying, and is commonly topic to limiting components equivalent to discounted reward, and different modifying environmental variables that can stop it from dashing to a direct objective with out consideration of the broader desired consequence.
Standard Utilization
MDP’s low-level idea is widespread in each analysis and lively deployments of machine studying. It’s been proposed for IoT safety protection methods, fish harvesting, and market forecasting.
Apart from its apparent applicability to chess and different strictly sequential video games, MDP can also be a pure contender for the procedural coaching of robotics methods, as we will see within the video beneath.
9: Time period Frequency-Inverse Doc Frequency
Time period Frequency (TF) divides the variety of occasions a phrase seems in a doc by the whole variety of phrases in that doc. Thus the phrase seal showing as soon as in a thousand-word article has a time period frequency of 0.001. By itself, TF is basically ineffective as an indicator of time period significance, as a consequence of the truth that meaningless articles (equivalent to a, and, the, and it) predominate.
To acquire a significant worth for a time period, Inverse Doc Frequency (IDF) calculates the TF of a phrase throughout a number of paperwork in a dataset, assigning low ranking to very high-frequency stopwords, equivalent to articles. The ensuing function vectors are normalized to entire values, with every phrase assigned an acceptable weight.

TF-IDF weights the relevance of phrases primarily based on frequency throughout numerous paperwork, with rarer incidence an indicator of salience. Supply: https://moz.com/weblog/inverse-document-frequency-and-the-importance-of-uniqueness
Although this strategy prevents semantically vital phrases from being misplaced as outliers, inverting the frequency weight doesn’t robotically imply {that a} low-frequency time period is not an outlier, as a result of some issues are uncommon and nugatory. Due to this fact a low-frequency time period might want to show its worth within the wider architectural context by that includes (even at a low frequency per doc) in numerous paperwork within the dataset.
Regardless of its age, TF-IDF is a strong and common methodology for preliminary filtering passes in Pure Language Processing frameworks.
Standard Utilization
As a result of TF-IDF has performed at the least some half within the growth of Google’s largely occult PageRank algorithm over the past twenty years, it has grow to be very extensively adopted as a manipulative search engine optimization tactic, regardless of John Mueller’s 2019 disavowal of its significance to go looking outcomes.
Because of the secrecy round PageRank, there isn’t any clear proof that TF-IDF is not presently an efficient tactic for rising in Google’s rankings. Incendiary dialogue amongst IT professionals currently signifies a well-liked understanding, appropriate or not, that time period abuse should still lead to improved search engine optimization placement (although extra accusations of monopoly abuse and extreme promoting blur the confines of this concept).
Stochastic Gradient Descent (SGD) is an more and more common methodology for optimizing the coaching of machine studying fashions.
Gradient Descent itself is a technique of optimizing and subsequently quantifying the advance {that a} mannequin is making throughout coaching.
On this sense, ‘gradient’ signifies a slope downwards (somewhat than a color-based gradation, see picture beneath), the place the best level of the ‘hill’, on the left, represents the start of the coaching course of. At this stage the mannequin has not but seen the whole thing of the info even as soon as, and has not realized sufficient about relationships between the info to provide efficient transformations.

A gradient descent on a FaceSwap coaching session. We will see that the coaching has plateaued for a while within the second half, however has finally recovered its method down the gradient in the direction of an appropriate convergence.
The bottom level, on the appropriate, represents convergence (the purpose at which the mannequin is as efficient as it’s ever going to get below the imposed constraints and settings).
The gradient acts as a file and predictor for the disparity between the error price (how precisely the mannequin has presently mapped the info relationships) and the weights (the settings that affect the best way by which the mannequin will be taught).
This file of progress can be utilized to tell a studying price schedule, an automated course of that tells the structure to grow to be extra granular and exact because the early obscure particulars rework into clear relationships and mappings. In impact, gradient loss gives a just-in-time map of the place the coaching ought to go subsequent, and the way it ought to proceed.
The innovation of Stochastic Gradient Descent is that it updates the mannequin’s parameters on every coaching instance per iteration, which typically accelerates the journey to convergence. Because of the introduction of hyperscale datasets lately, SGD has grown in recognition currently as one doable methodology to handle the following logistic points.
Then again, SGD has unfavorable implications for function scaling, and will require extra iterations to attain the identical end result, requiring extra planning and extra parameters, in comparison with common Gradient Descent.
Standard Utilization
As a result of its configurability, and regardless of its shortcomings, SGD has grow to be the most well-liked optimization algorithm for becoming neural networks. One configuration of SGD that’s turning into dominant in new AI/ML analysis papers is the selection of the Adaptive Second Estimation (ADAM, launched in 2015) optimizer.
ADAM adapts the training price for every parameter dynamically (‘adaptive studying price’), in addition to incorporating outcomes from earlier updates into the next configuration (‘momentum’). Moreover, it may be configured to make use of later improvements, equivalent to Nesterov Momentum.
Nevertheless, some preserve that using momentum can even pace ADAM (and comparable algorithms) to a sub-optimal conclusion. As with many of the bleeding fringe of the machine studying analysis sector, SGD is a piece in progress.
First printed tenth February 2022.
[ad_2]

