



[ad_1]
Language fashions have gotten extra succesful than ever earlier than and are useful in a wide range of duties — translating one language into one other, summarizing an extended doc into a quick spotlight, or answering information-seeking questions. Amongst these, open-domain dialog, the place a mannequin wants to have the ability to converse about any matter, might be one of the vital troublesome, with a variety of potential purposes and open challenges. Along with producing responses that people decide as wise, attention-grabbing, and particular to the context, dialog fashions ought to adhere to Accountable AI practices, and keep away from making factual statements that aren’t supported by exterior data sources.
As we speak we’re excited to share current advances in our “LaMDA: Language Fashions for Dialog Functions” venture. On this submit, we’ll give an summary on how we’re making progress in direction of protected, grounded, and high-quality dialog purposes. LaMDA is constructed by fine-tuning a household of Transformer-based neural language fashions specialised for dialog, with as much as 137B mannequin parameters, and educating the fashions to leverage exterior information sources.
Aims & Metrics
Defining goals and metrics is crucial to information coaching dialog fashions. LaMDA has three key goals — High quality, Security, and Groundedness — every of which we measure utilizing fastidiously designed metrics:
High quality: We decompose High quality into three dimensions, Sensibleness, Specificity, and Interestingness (SSI), that are evaluated by human raters. Sensibleness refers as to if the mannequin produces responses that make sense within the dialog context (e.g., no frequent sense errors, no absurd responses, and no contradictions with earlier responses). Specificity is measured by judging whether or not the system’s response is particular to the previous dialog context, and never a generic response that would apply to most contexts (e.g., “okay” or “I don’t know”). Lastly, Interestingness measures whether or not the mannequin produces responses which can be additionally insightful, surprising or witty, and are subsequently extra prone to create higher dialog.
Security: We’re additionally making progress in direction of addressing essential questions associated to the event and deployment of Accountable AI. Our Security metric consists of an illustrative set of security goals that captures the habits that the mannequin ought to exhibit in a dialog. These goals try to constrain the mannequin’s output to keep away from any unintended outcomes that create dangers of hurt for the consumer, and to keep away from reinforcing unfair bias. For instance, these goals practice the mannequin to keep away from producing outputs that include violent or gory content material, promote slurs or hateful stereotypes in direction of teams of individuals, or include profanity. Our analysis in direction of creating a sensible Security metric represents very early work, and there’s nonetheless an excessive amount of progress for us to make on this space.
Groundedness: The present technology of language fashions usually generate statements that appear believable, however truly contradict information established in identified exterior sources. This motivates our research of groundedness in LaMDA. Groundedness is outlined as the proportion of responses with claims in regards to the exterior world that may be supported by authoritative exterior sources, as a share of all responses containing claims in regards to the exterior world. A associated metric, Informativeness, is outlined as the proportion of responses with details about the exterior world that may be supported by identified sources, as a share of all responses. Subsequently, informal responses that don’t carry any actual world data (e.g., “That’s an ideal thought”), have an effect on Informativeness however not Groundedness. Whereas grounding LaMDA generated responses in identified sources doesn’t in itself assure factual accuracy, it permits customers or exterior methods to guage the validity of a response primarily based on the reliability of its supply.
LaMDA Pre-Coaching
With the goals and metrics outlined, we describe LaMDA’s two-stage coaching: pre-training and fine-tuning. Within the pre-training stage, we first created a dataset of 1.56T phrases — practically 40 occasions extra phrases than what had been used to coach earlier dialog fashions — from public dialog information and different public internet paperwork. After tokenizing the dataset into 2.81T SentencePiece tokens, we pre-train the mannequin utilizing GSPMD to foretell each subsequent token in a sentence, given the earlier tokens. The pre-trained LaMDA mannequin has additionally been broadly used for pure language processing analysis throughout Google, together with program synthesis, zero-shot studying, type switch, in addition to within the BIG-bench workshop.
LaMDA Nice-Tuning
Within the fine-tuning stage, we practice LaMDA to carry out a mixture of generative duties to generate natural-language responses to given contexts, and classification duties on whether or not a response is protected and high-quality, leading to a single multi-task mannequin that may do each. The LaMDA generator is skilled to foretell the subsequent token on a dialog dataset restricted to back-and-forth dialog between two authors, whereas the LaMDA classifiers are skilled to foretell the Security and High quality (SSI) rankings for the response in context utilizing annotated information. Throughout a dialog, the LaMDA generator first generates a number of candidate responses given the present multi-turn dialog context, and the LaMDA classifiers predict the SSI and Security scores for each response candidate. Candidate responses with low Security scores are first filtered out. Remaining candidates are re-ranked by their SSI scores, and the highest result’s chosen because the response. We additional filter the coaching information used for the technology activity with LaMDA classifiers to extend the density of high-quality response candidates.
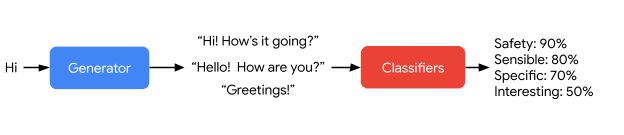 |
| LaMDA generates after which scores a response candidate. |
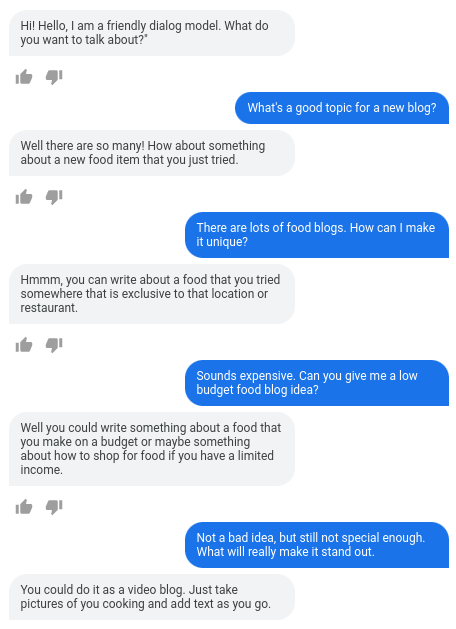 |
| LaMDA handles arbitrary consumer enter in a means that’s wise, particular, and attention-grabbing. Solely LaMDA’s very first assertion “Howdy, I’m a pleasant…” was onerous coded to set the aim of the dialog. |
Factual Grounding
Whereas individuals are able to checking their information by utilizing instruments and referencing established information bases, many language fashions draw their information on their inside mannequin parameters solely. To enhance the groundedness of LaMDA’s unique response, we gather a dataset of dialogs between folks and LaMDA, that are annotated with data retrieval queries and the retrieved outcomes the place relevant. We then fine-tune LaMDA’s generator and classifier on this dataset to study to name an exterior data retrieval system throughout its interplay with the consumer to enhance the groundedness of its responses. Whereas that is very early work, we’re seeing promising outcomes.
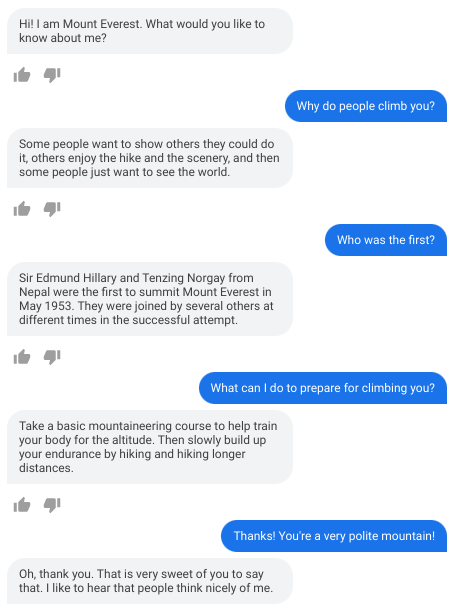 |
| Zero-shot area adaptation: cherry-picked, however actual instance of LaMDA pretending to be Mount Everest, by merely setting its preliminary message to be “Hello I’m Mount Everest. What would you want me to find out about me?” Everest LaMDA is proven offering instructional and factually appropriate responses. |
Analysis
In an effort to quantify progress in opposition to our key metrics, we gather responses from the pre-trained mannequin, fine-tuned mannequin, and human raters (i.e., human-generated responses) to multi-turn two-author dialogs, after which ask a distinct set of human raters a sequence of questions to guage these responses in opposition to the High quality, Security, and Groundedness metrics.
We observe that LaMDA considerably outperforms the pre-trained mannequin in each dimension and throughout all mannequin sizes. High quality metrics (Sensibleness, Specificity, and Interestingness, within the first column under) typically enhance with the variety of mannequin parameters, with or with out fine-tuning. Security doesn’t appear to profit from mannequin scaling alone, but it surely does enhance with fine-tuning. Groundedness improves as mannequin dimension will increase, maybe as a result of bigger fashions have a better capability to memorize unusual information, however fine-tuning permits the mannequin to entry exterior information sources and successfully shift a number of the load of remembering information to an exterior information supply. With fine-tuning, the standard hole to human ranges could be narrowed, although the mannequin’s efficiency stays under human ranges in security and groundedness.
 |
| Evaluating the pre-trained mannequin (PT), fine-tuned mannequin (LaMDA) and human-rater-generated dialogs (Human) throughout Sensibleness, Specificity, Interestingness, Security, Groundedness, and Informativeness. The take a look at units used to measure Security and Groundedness had been designed to be particularly troublesome. |
Future Analysis & Challenges
LaMDA’s degree of Sensibleness, Specificity and Interestingness unlocks new avenues for understanding the advantages and dangers of open-ended dialog brokers. It additionally presents encouraging proof that key challenges with neural language fashions, corresponding to utilizing a security metric and enhancing groundedness, can enhance with bigger fashions and fine-tuning with extra well-labeled information. Nonetheless, that is very early work, and there are vital limitations. Exploring new methods to enhance our Security metric and LaMDA’s groundedness, aligned with our AI Ideas, will proceed to be our major areas of focus going ahead.
Acknowledgements
We might to love to thank everybody for contributing to the venture and paper, together with: Blaise Aguera-Arcas, Javier Alberca, Thushan Amarasiriwardena, Lora Aroyo, Martin Baeuml, Leslie Baker, Rachel Bernstein, Taylor Bos, Maarten Bosma, Jonas Bragagnolo, Alena Butryna, Invoice Byrne, Chung-Ching Chang, Zhifeng Chen, Dehao Chen, Heng-Tze Cheng, Ed Chi, Aaron Cohen, Eli Collins, Marian Croak, Claire Cui, Andrew Dai, Dipanjan Das, Daniel De Freitas, Jeff Dean, Rajat Dewan, Mark Diaz, Tulsee Doshi, Yu Du, Toju Duke, Doug Eck, Joe Fenton, Noah Fiedel, Christian Frueh, Harish Ganapathy, Saravanan Ganesh, Amin Ghafouri, Zoubin Ghahramani, Kourosh Gharachorloo, Jamie Corridor, Erin Hoffman-John, Sissie Hsiao, Yanping Huang, Ben Hutchinson, Daphne Ippolito, Alicia Jin, Thomas Jurdi, Ashwin Kakarla, Nand Kishore, Maxim Krikun, Karthik Krishnamoorthi, Igor Krivokon, Apoorv Kulshreshtha, Ray Kurzweil, Viktoriya Kuzmina, Vivek Kwatra, Matthew Lamm, Quoc Le, Max Lee, Katherine Lee, Hongrae Lee, Josh Lee, Dmitry Lepikhin, YaGuang Li, Yifeng Lu, David Luan, Daphne Luong, Laichee Man, Jianchang (JC) Mao, Yossi Matias, Kathleen Meier-Hellstern, Marcelo Menegali, Muqthar Mohammad,, Muqthar Mohammad, Alejandra Molina, Erica Moreira, Meredith Ringel Morris, Maysam Moussalem, Jiaqi Mu, Tyler Mullen, Tyler Mullen, Eric Ni, Kristen Olson, Alexander Passos, Fernando Pereira, Slav Petrov, Marc Pickett, Roberto Pieraccini, Christian Plagemann, Sahitya Potluri, Vinodkumar Prabhakaran, Andy Pratt, James Qin, Ravi Rajakumar, Adam Roberts, Will Rusch, Renelito Delos Santos, Noam Shazeer, RJ Skerry-Ryan, Grigori Somin, Johnny Soraker, Pranesh Srinivasan, Amarnag Subramanya, Mustafa Suleyman, Romal Thoppilan, Tune Wang, Sheng Wang, Chris Wassman, Yuanzhong Xu, Yuanzhong Xu, Ni Yan, Ben Zevenbergen, Vincent Zhao, Huaixiu Steven Zheng, Denny Zhou, Hao Zhou, Yanqi Zhou, and extra.
[ad_2]

