



[ad_1]
Scaling giant language fashions has resulted in important high quality enhancements pure language understanding (T5), technology (GPT-3) and multilingual neural machine translation (M4). One frequent strategy to constructing a bigger mannequin is to extend the depth (variety of layers) and width (layer dimensionality), merely enlarging current dimensions of the community. Such dense fashions take an enter sequence (divided into smaller elements, known as tokens) and move each token by the complete community, activating each layer and parameter. Whereas these giant, dense fashions have achieved state-of-the-art outcomes on a number of pure language processing (NLP) duties, their coaching price will increase linearly with mannequin dimension.
An alternate, and more and more widespread, strategy is to construct sparsely activated fashions based mostly on a combination of consultants (MoE) (e.g., GShard-M4 or GLaM), the place every token handed to the community follows a separate subnetwork by skipping among the mannequin parameters. The selection of how you can distribute the enter tokens to every subnetwork (the “consultants”) is decided by small router networks which might be skilled along with the remainder of the community. This enables researchers to extend mannequin dimension (and therefore, efficiency) and not using a proportional improve in coaching price.
Whereas that is an efficient technique at coaching time, sending tokens of a protracted sequence to a number of consultants, once more makes inference computationally costly as a result of the consultants need to be distributed amongst a lot of accelerators. For instance, serving the 1.2T parameter GLaM mannequin requires 256 TPU-v3 chips. Very like dense fashions, the variety of processors wanted to serve an MoE mannequin nonetheless scales linearly with respect to the mannequin dimension, growing compute necessities whereas additionally leading to important communication overhead and added engineering complexity.
In “Past Distillation: Job-level Combination-of-Specialists for Environment friendly Inference”, we introduce a way known as Job-level Combination-of-Specialists (TaskMoE), that takes benefit of the standard features of mannequin scaling whereas nonetheless being environment friendly to serve. Our answer is to coach a big multi-task mannequin from which we then extract smaller, stand-alone per-task subnetworks appropriate for inference with no loss in mannequin high quality and with considerably lowered inference latency. We exhibit the effectiveness of this technique for multilingual neural machine translation (NMT) in comparison with different combination of consultants fashions and to fashions compressed utilizing data distillation.
Coaching Giant Sparsely Activated Fashions with Job Data
We practice a sparsely activated mannequin, the place router networks study to ship tokens of every task-specific enter to completely different subnetworks of the mannequin related to the duty of curiosity. For instance, within the case of multilingual NMT, each token of a given language is routed to the identical subnetwork. This differs from different current approaches, such because the sparsely gated combination of professional fashions (e.g., TokenMoE), the place router networks study to ship completely different tokens in an enter to completely different subnetworks unbiased of activity.
Inference: Bypassing Distillation by Extracting Subnetworks
A consequence of this distinction in coaching between TaskMoE and fashions like TokenMoE is in how we strategy inference. As a result of TokenMoE follows the observe of distributing tokens of the identical activity to many consultants at each coaching and inference time, it’s nonetheless computationally costly at inference.
For TaskMoE, we dedicate a smaller subnetwork to a single activity identification throughout coaching and inference. At inference time, we extract subnetworks by discarding unused consultants for every activity. TaskMoE and its variants allow us to coach a single giant multi-task community after which use a separate subnetwork at inference time for every activity with out utilizing any extra compression strategies post-training. We illustrate the method of coaching a TaskMoE community after which extracting per-task subnetworks for inference under.
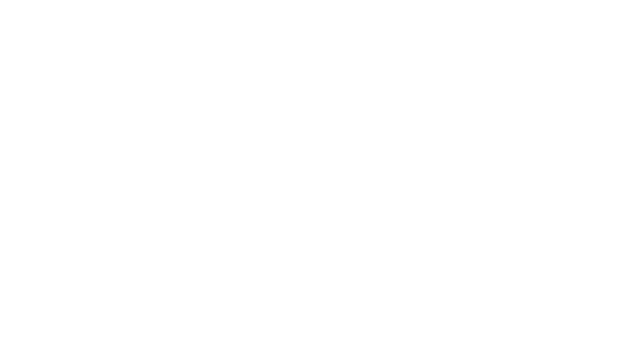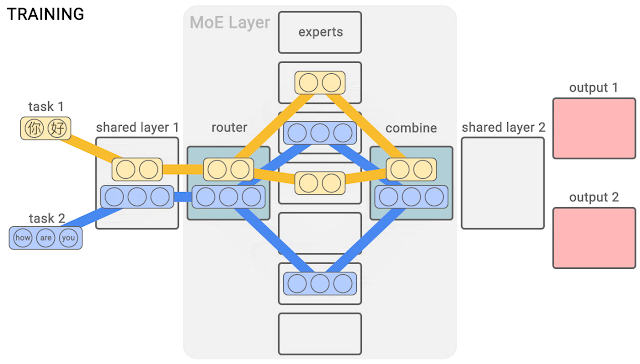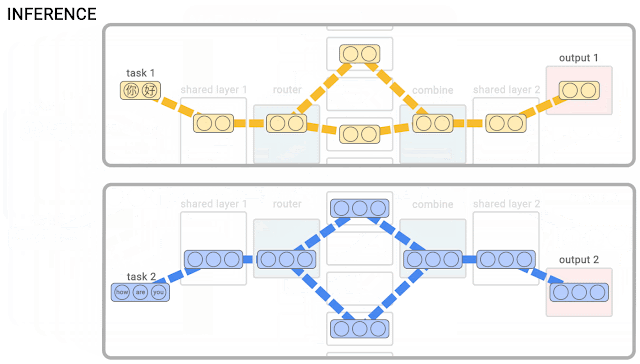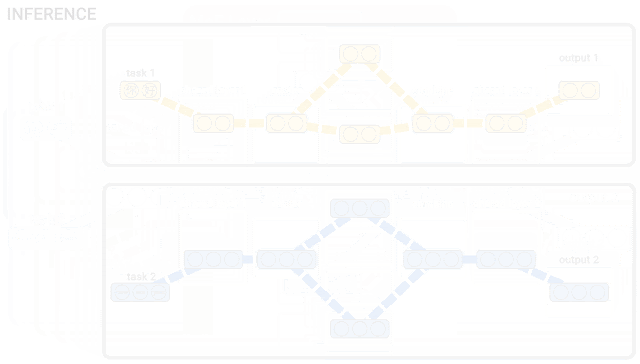 |
| Throughout coaching, tokens of the identical language are routed to the identical professional based mostly on language info (both supply, goal or each) in task-based MoE. Later, throughout inference we extract subnetworks for every activity and discard unused consultants. |
To exhibit this strategy, we practice fashions based mostly on the Transformer structure. Just like GShard-M4 and GLaM, we exchange the feedforward community of each different transformer layer with a Combination-of-Specialists (MoE) layer that consists of a number of equivalent feedforward networks, the “consultants”. For every activity, the routing community, skilled together with the remainder of the mannequin, retains observe of the duty identification for all enter tokens and chooses a sure variety of consultants per layer (two on this case) to type the task-specific subnetwork. The baseline dense Transformer mannequin has 143M parameters and 6 layers on each the encoder and decoder. The TaskMoE and TokenMoE that we practice are additionally each 6 layers deep however with 32 consultants for each MoE layer and have a complete of 533M parameters. We practice our fashions utilizing publicly out there WMT datasets, with over 431M sentences throughout 30 language pairs from completely different language households and scripts. We level the reader to the full paper for additional particulars.
Outcomes
With a view to exhibit the benefit of utilizing TaskMoE at inference time, we examine the throughput, or the variety of tokens decoded per second, for TaskMoE, TokenMoE, and a baseline dense mannequin. As soon as the subnetwork for every activity is extracted, TaskMoE is 7x smaller than the 533M parameter TokenMoE mannequin, and it may be served on a single TPUv3 core, as a substitute of 64 cores required for TokenMoE. We see that TaskMoE has a peak throughput twice as excessive as that of TokenMoE fashions. As well as, on inspecting the TokenMoE mannequin, we discover that 25% of the inference time has been spent in inter-device communication, whereas just about no time is spent in communication by TaskMoE.
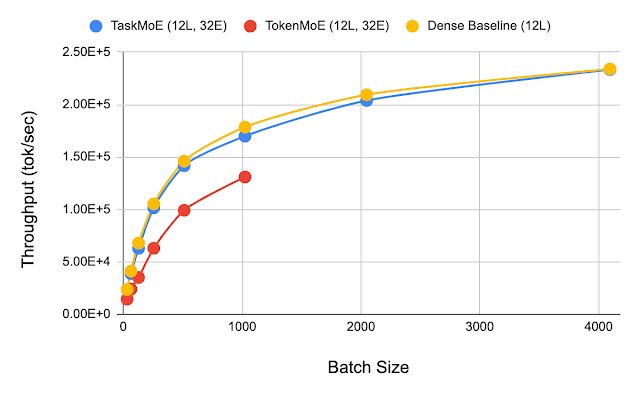 |
| Evaluating the throughput of TaskMoE with TokenMoE throughout completely different batch sizes. The utmost batch dimension for TokenMoE is 1024 versus 4096 for TaskMoE and the dense baseline mannequin. Right here, TokenMoE has one occasion distributed throughout 64 TPUv3 cores, whereas TaskMoE and the baseline mannequin have one occasion on every of the 64 cores. |
A preferred strategy to constructing a smaller community that also performs nicely is thru data distillation, during which a big instructor mannequin trains a smaller scholar mannequin with the objective of matching the instructor’s efficiency. Nevertheless, this technique comes at the price of extra computation wanted to coach the scholar from the instructor. So, we additionally examine TaskMoE to a baseline TokenMoE mannequin that we compress utilizing data distillation. The compressed TokenMoE mannequin has a dimension similar to the per-task subnetwork extracted from TaskMoE.
We discover that along with being an easier technique that doesn’t want any extra coaching, TaskMoE improves upon a distilled TokenMoE mannequin by 2.1 BLEU on common throughout all languages in our multilingual translation mannequin. We notice that distillation retains 43% of the efficiency features achieved from scaling a dense multilingual mannequin to a TokenMoE, whereas extracting the smaller subnetwork from the TaskMoE mannequin ends in no lack of high quality.
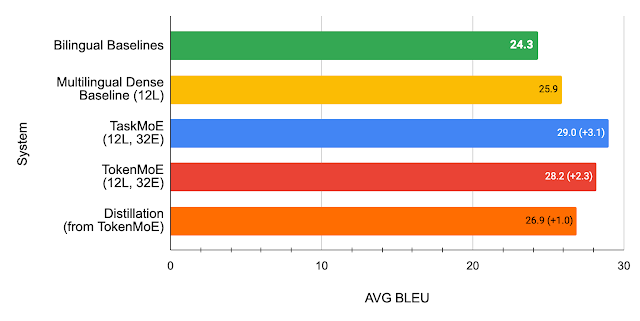 |
| BLEU scores (larger is best) evaluating a distilled TokenMoE mannequin to the TaskMoE and TokenMoE fashions with 12 layers (6 on the encoder and 6 on the decoder) and 32 consultants. Whereas each approaches enhance upon a multilingual dense baseline, TaskMoE improves upon the baseline by 3.1 BLEU on common whereas distilling from TokenMoE improves upon the baseline by 1.0 BLEU on common. |
Subsequent Steps
The standard enhancements typically seen with scaling machine studying fashions has incentivized the analysis neighborhood to work towards advancing scaling expertise to allow environment friendly coaching of enormous fashions. The rising want to coach fashions able to generalizing to a number of duties and modalities solely will increase the necessity for scaling fashions even additional. Nevertheless, the practicality of serving these giant fashions stays a serious problem. Effectively deploying giant fashions is a crucial course of analysis, and we consider TaskMoE is a promising step in direction of extra inference pleasant algorithms that retain the standard features of scaling.
Acknowledgements
We wish to first thank our coauthors – Yanping Huang, Ankur Bapna, Maxim Krikun, Dmitry Lepikhin and Minh-Thang Luong. We might additionally prefer to thank Wolfgang Macherey, Yuanzhong Xu, Zhifeng Chen and Macduff Richard Hughes for his or her useful suggestions. Particular due to the Translate and Mind groups for his or her helpful enter and discussions, and your entire GShard growth group for his or her foundational contributions to this challenge. We might additionally prefer to thank Tom Small for creating the animations for the weblog publish.
[ad_2]

