



[ad_1]
Googlebot is the net crawler utilized by Google to assemble the data wanted and construct a searchable index of the net. Googlebot has cell and desktop crawlers, in addition to specialised crawlers for information, photos, and movies.
There are extra crawlers Google makes use of for particular duties, and every crawler will determine itself with a unique string of textual content referred to as a “person agent.” Googlebot is evergreen, that means it sees web sites as customers would within the newest Chrome browser.
Googlebot runs on hundreds of machines. They decide how briskly and what to crawl on web sites. However they may decelerate their crawling in order to not overwhelm web sites.
Let’s have a look at their course of for constructing an index of the internet.
How Googlebot crawls and indexes the internet
Google has shared a couple of variations of its pipeline previously. The beneath is the newest.
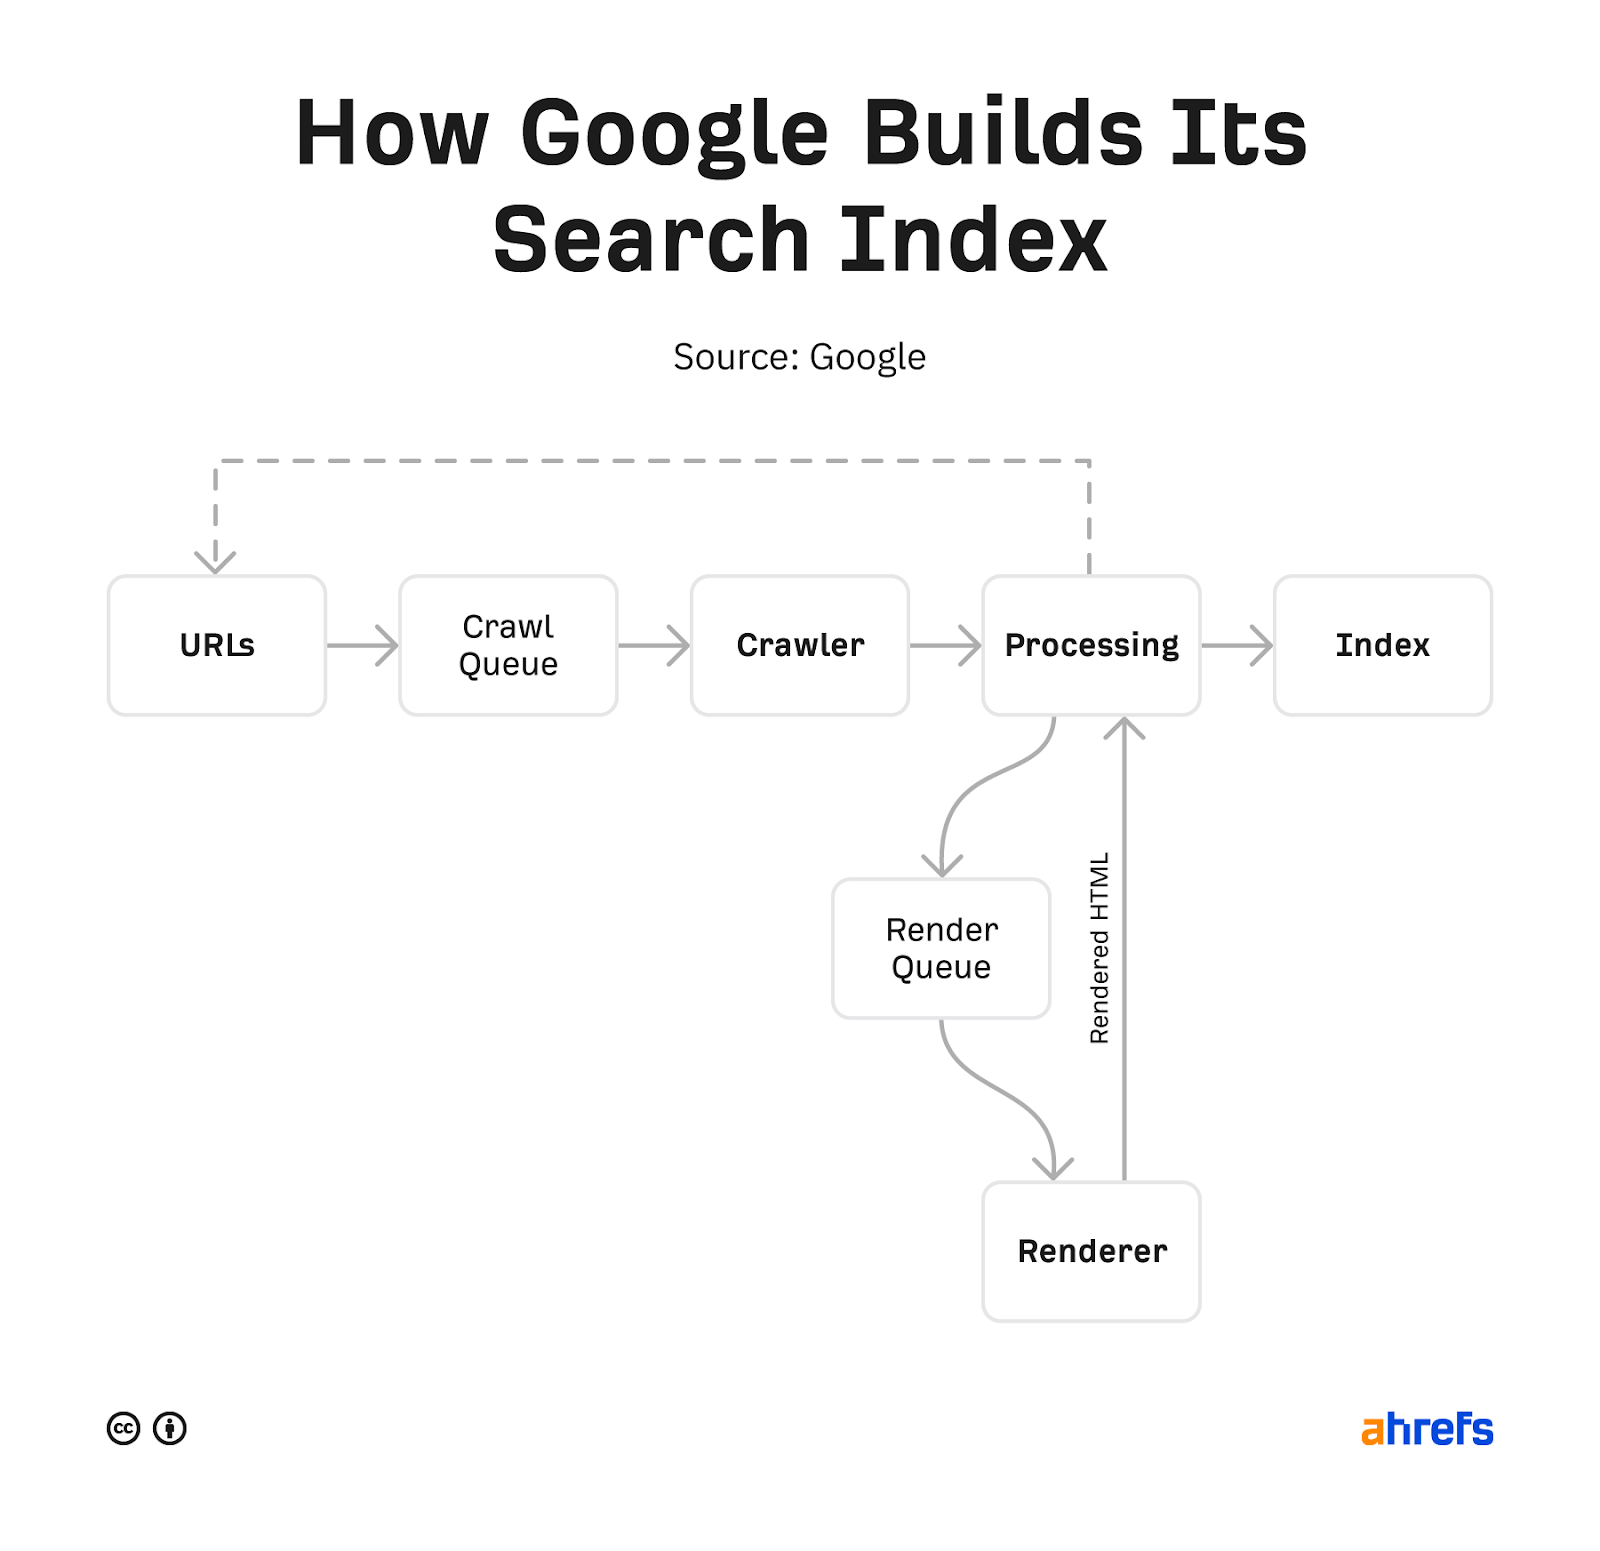
Google begins with an inventory of URLs it collects from varied sources, similar to pages, sitemaps, RSS feeds, and URLs submitted in Google Search Console or the Indexing API. It prioritizes what it needs to crawl, fetches the pages, and shops copies of the pages.
These pages are processed to seek out extra hyperlinks, together with hyperlinks to issues like API requests, JavaScript, and CSS that Google must render a web page. All of those extra requests get crawled and cached (saved). Google makes use of a rendering service that makes use of these cached assets to view pages much like how a person would.
It processes this once more and appears for any adjustments to the web page or new hyperlinks. The content material of the rendered pages is what’s saved and searchable in Google’s index. Any new hyperlinks discovered return to the bucket of URLs for it to crawl.
We’ve got extra particulars on this course of in our article on how search engines like google work.
Learn how to management Googlebot
Google offers you a couple of methods to regulate what will get crawled and listed.
Methods to regulate crawling
Methods to regulate indexing
- Delete your content material – Should you delete a web page, then there’s nothing to index. The draw back to that is nobody else can entry it both.
- Prohibit entry to the content material – Google doesn’t log in to web sites, so any type of password safety or authentication will stop it from seeing the content material.
- Noindex – A noindex within the meta robots tag tells search engines like google to not index your web page.
- URL removing device – The title for this device from Google is barely deceptive, as the best way it really works is it’s going to quickly conceal the content material. Google will nonetheless see and crawl this content material, however the pages received’t seem in search outcomes.
- Robots.txt (Photographs solely) – Blocking Googlebot Picture from crawling implies that your photos is not going to be listed.
Should you’re undecided which indexing management you must use, take a look at our flowchart in our put up on eradicating URLs from Google search.
Is it actually Googlebot?
Many search engine optimisation instruments and a few malicious bots will fake to be Googlebot. This may increasingly permit them to entry web sites that attempt to block them.
Up to now, you wanted to run a DNS lookup to confirm Googlebot. However lately, Google made it even simpler and offered a checklist of public IPs you should use to confirm the requests are from Google. You’ll be able to examine this to the info in your server logs.
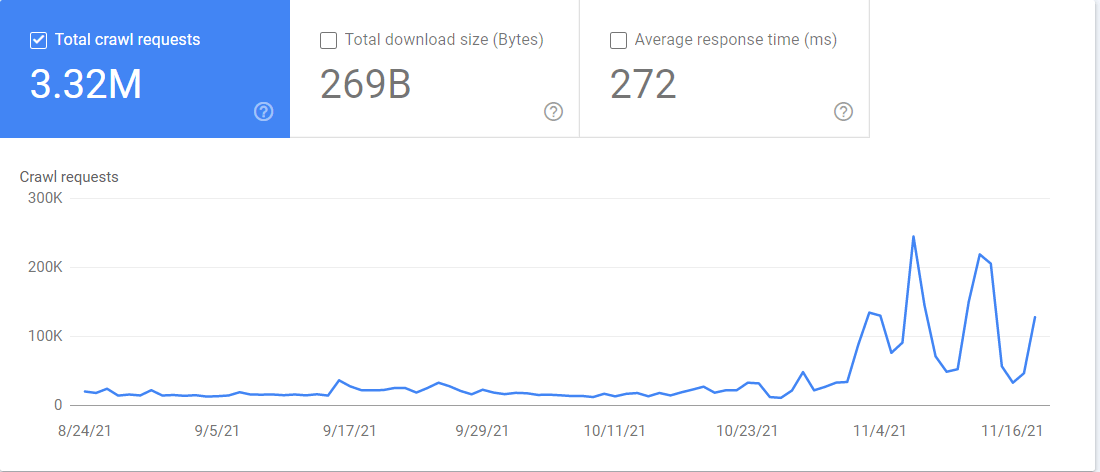
You even have entry to a “Crawl stats” report in Google Search Console. Should you go to Settings > Crawl Stats, the report comprises a variety of details about how Google is crawling your web site. You’ll be able to see which Googlebot is crawling what recordsdata and when it accessed them.
Remaining ideas
The online is a giant and messy place. Googlebot has to navigate all of the totally different setups, together with downtimes and restrictions, to assemble the info Google wants for its search engine to work.
A enjoyable reality to wrap issues up is that Googlebot is normally depicted as a robotic and is aptly known as “Googlebot.” There’s additionally a spider mascot that’s named “Crawley.”
Nonetheless have questions? Let me know on Twitter.
[ad_2]

