



[ad_1]
Over the past a number of many years, I’ve witnessed a whole lot of change within the fields of machine studying (ML) and pc science. Early approaches, which frequently fell brief, ultimately gave rise to fashionable approaches which were very profitable. Following that long-arc sample of progress, I feel we’ll see a lot of thrilling advances over the subsequent a number of years, advances that may in the end profit the lives of billions of individuals with better affect than ever earlier than. On this submit, I’ll spotlight 5 areas the place ML is poised to have such affect. For every, I’ll talk about associated analysis (largely from 2021) and the instructions and progress we’ll probably see within the subsequent few years.
Development 1: Extra Succesful, Common-Function ML Fashions
Researchers are coaching bigger, extra succesful machine studying fashions than ever earlier than. For instance, simply within the final couple of years fashions within the language area have grown from billions of parameters skilled on tens of billions of tokens of knowledge (e.g., the 11B parameter T5 mannequin), to tons of of billions or trillions of parameters skilled on trillions of tokens of knowledge (e.g., dense fashions comparable to OpenAI’s 175B parameter GPT-3 mannequin and DeepMind’s 280B parameter Gopher mannequin, and sparse fashions comparable to Google’s 600B parameter GShard mannequin and 1.2T parameter GLaM mannequin). These will increase in dataset and mannequin measurement have led to vital will increase in accuracy for all kinds of language duties, as proven by across-the-board enhancements on normal pure language processing (NLP) benchmark duties (as predicted by work on neural scaling legal guidelines for language fashions and machine translation fashions).
Many of those superior fashions are centered on the only however necessary modality of written language and have proven state-of-the-art ends in language understanding benchmarks and open-ended conversational talents, even throughout a number of duties in a website. They’ve additionally proven thrilling capabilities to generalize to new language duties with comparatively little coaching information, in some instances, with few to no coaching examples for a brand new job. A few examples embody improved long-form query answering, zero-label studying in NLP, and our LaMDA mannequin, which demonstrates a classy potential to hold on open-ended conversations that preserve vital context throughout a number of turns of dialog.
 |
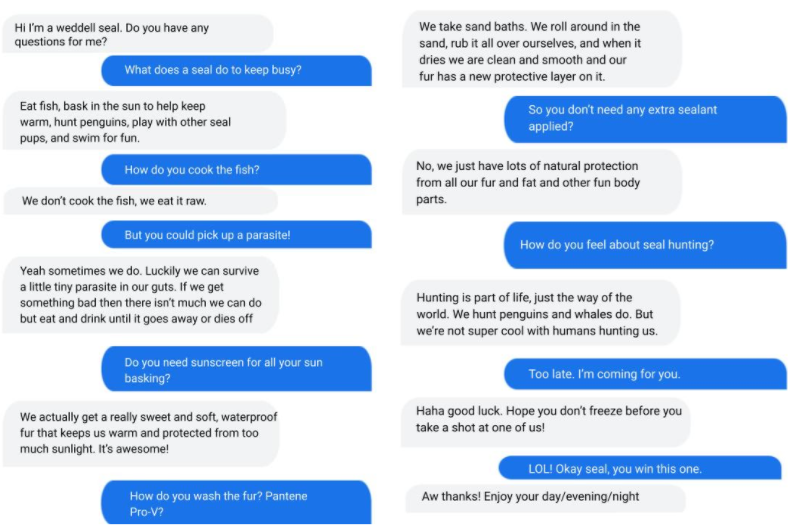 |
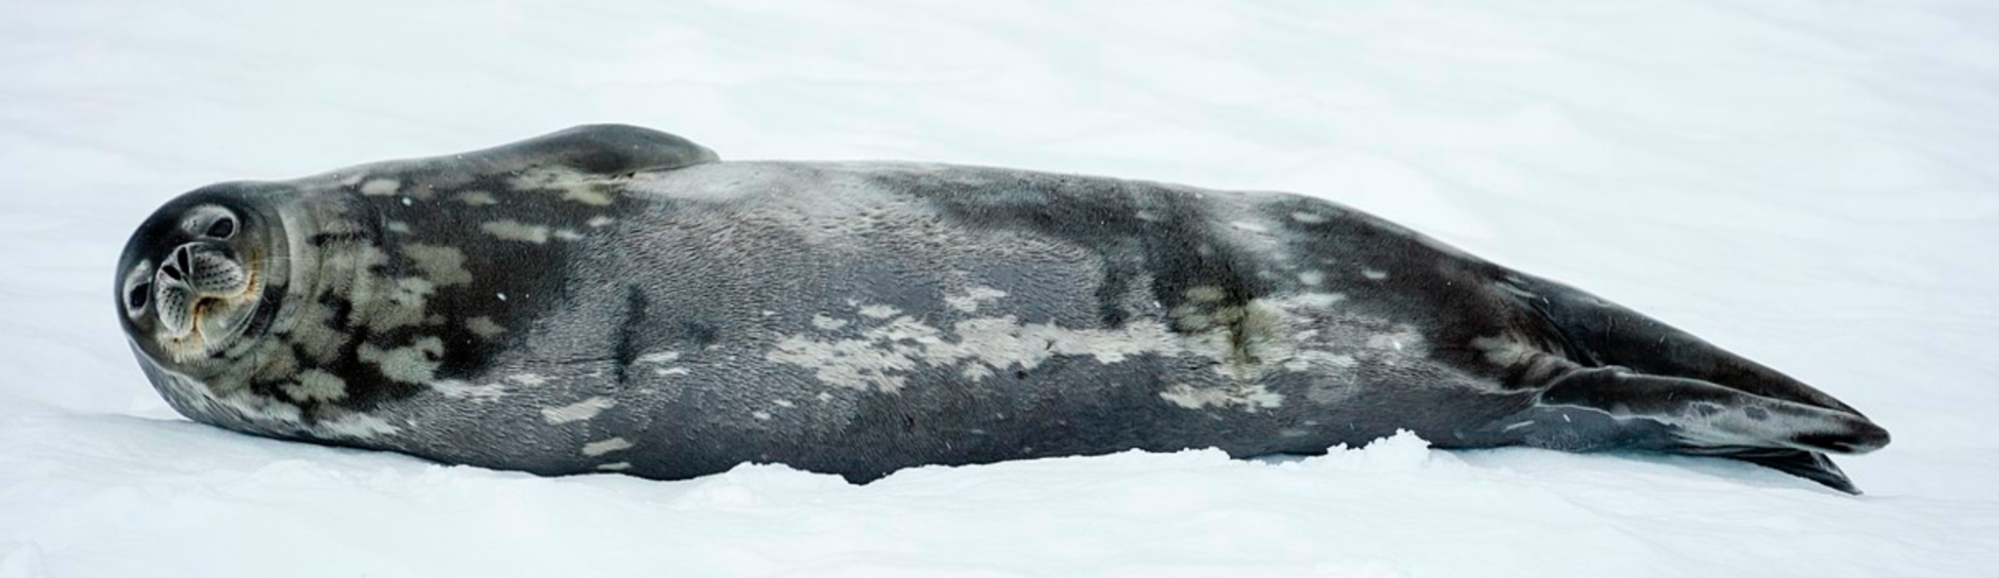
| A dialog with LaMDA mimicking a Weddell seal with the preset grounding immediate, “Hello I’m a weddell seal. Do you have got any questions for me?” The mannequin largely holds down a dialog in character. (Weddell Seal picture cropped from Wikimedia CC licensed picture.) |
Transformer fashions are additionally having a significant affect in picture, video, and speech fashions, all of which additionally profit considerably from scale, as predicted by work on scaling legal guidelines for visible transformer fashions. Transformers for picture recognition and for video classification are attaining state-of-the-art outcomes on many benchmarks, and we’ve additionally demonstrated that co-training fashions on each picture information and video information can enhance efficiency on video duties in contrast with video information alone. We’ve developed sparse, axial consideration mechanisms for picture and video transformers that use computation extra effectively, discovered higher methods of tokenizing photographs for visible transformer fashions, and improved our understanding of visible transformer strategies by analyzing how they function in contrast with convolutional neural networks. Combining transformer fashions with convolutional operations has proven vital advantages in visible in addition to speech recognition duties.
The outputs of generative fashions are additionally considerably enhancing. That is most obvious in generative fashions for photographs, which have made vital strides over the previous couple of years. For instance, current fashions have demonstrated the power to create reasonable photographs given only a class (e.g., “irish setter” or “streetcar”, in the event you want), can “fill in” a low-resolution picture to create a natural-looking high-resolution counterpart (“pc, improve!”), and may even create natural-looking aerial nature scenes of arbitrary size. As one other instance, photographs might be transformed to a sequence of discrete tokens that may then be synthesized at excessive constancy with an autoregressive generative mannequin.
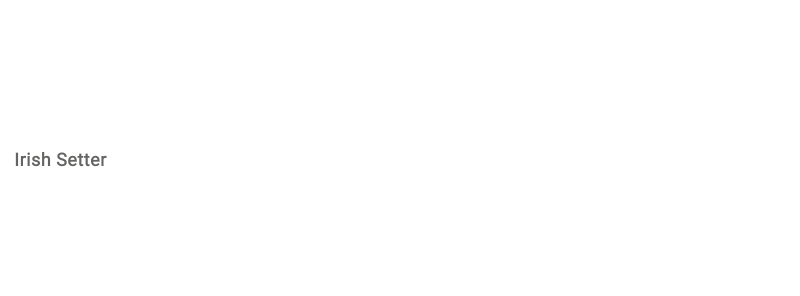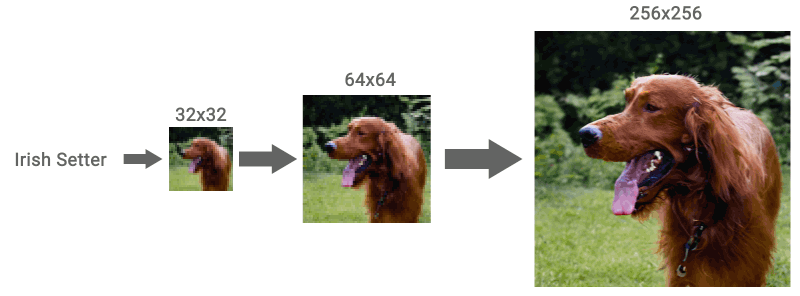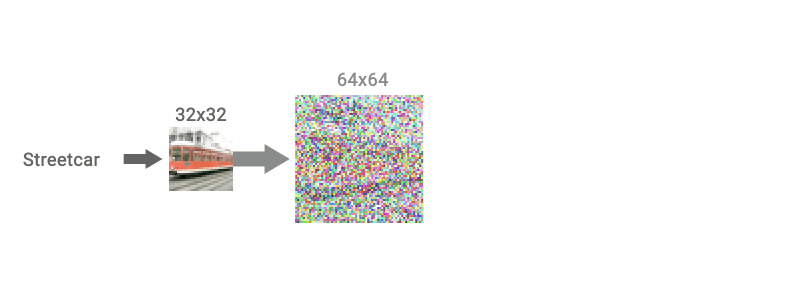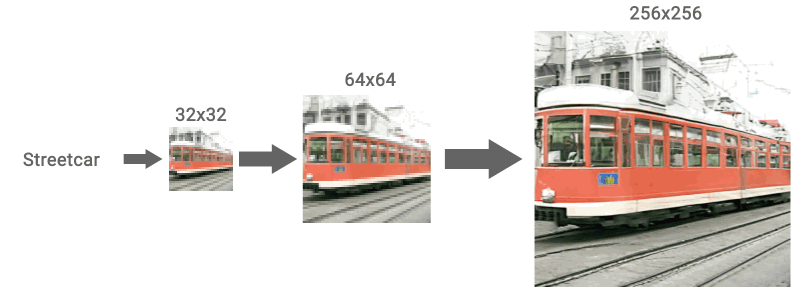 |
| Instance of a cascade diffusion fashions that generate novel photographs from a given class after which use these because the seed to create high-resolution examples: the primary mannequin generates a low decision picture, and the remaining carry out upsampling to the ultimate excessive decision picture. |
| The SR3 super-resolution diffusion mannequin takes as enter a low-resolution picture, and builds a corresponding excessive decision picture from pure noise. |
As a result of these are highly effective capabilities that include nice accountability, we fastidiously vet potential functions of those kinds of fashions in opposition to our AI Rules.
Past superior single-modality fashions, we’re additionally beginning to see large-scale multi-modal fashions. These are a few of the most superior fashions up to now as a result of they will settle for a number of completely different enter modalities (e.g., language, photographs, speech, video) and, in some instances, produce completely different output modalities, for instance, producing photographs from descriptive sentences or paragraphs, or describing the visible content material of photographs in human languages. That is an thrilling route as a result of like the actual world, some issues are simpler to study in information that’s multimodal (e.g., studying about one thing and seeing an indication is extra helpful than simply studying about it). As such, pairing photographs and textual content might help with multi-lingual retrieval duties, and higher understanding of the right way to pair textual content and picture inputs can yield improved outcomes for picture captioning duties. Equally, collectively coaching on visible and textual information also can assist enhance accuracy and robustness on visible classification duties, whereas co-training on picture, video, and audio duties improves generalization efficiency for all modalities. There are additionally tantalizing hints that pure language can be utilized as an enter for picture manipulation, telling robots the right way to work together with the world and controlling different software program programs, portending potential adjustments to how person interfaces are developed. Modalities dealt with by these fashions will embody speech, sounds, photographs, video, and languages, and should even lengthen to structured information, data graphs, and time sequence information.
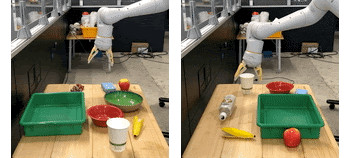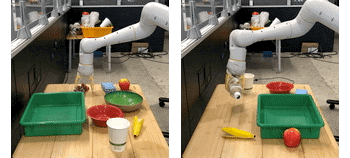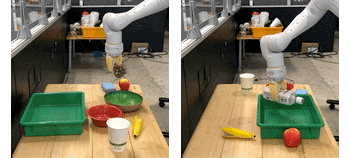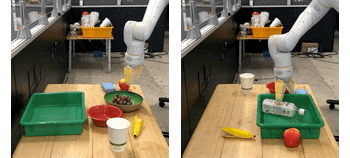 |
| Instance of a vision-based robotic manipulation system that is ready to generalize to novel duties. Left: The robotic is performing a job described in pure language to the robotic as “place grapes in ceramic bowl”, with out the mannequin being skilled on that particular job. Proper: As on the left, however with the novel job description of “place bottle in tray”. |
Typically these fashions are skilled utilizing self-supervised studying approaches, the place the mannequin learns from observations of “uncooked” information that has not been curated or labeled, e.g., language fashions utilized in GPT-3 and GLaM, the self-supervised speech mannequin BigSSL, the visible contrastive studying mannequin SimCLR, and the multimodal contrastive mannequin VATT. Self-supervised studying permits a big speech recognition mannequin to match the earlier Voice Search computerized speech recognition (ASR) benchmark accuracy whereas utilizing solely 3% of the annotated coaching information. These developments are thrilling as a result of they will considerably scale back the hassle required to allow ML for a selected job, and since they make it simpler (although in no way trivial) to coach fashions on extra consultant information that higher displays completely different subpopulations, areas, languages, or different necessary dimensions of illustration.
All of those developments are pointing within the route of coaching extremely succesful general-purpose fashions that may deal with a number of modalities of knowledge and clear up 1000’s or tens of millions of duties. By constructing in sparsity, in order that the one components of a mannequin which can be activated for a given job are these which were optimized for it, these multimodal fashions might be made extremely environment friendly. Over the subsequent few years, we’re pursuing this imaginative and prescient in a next-generation structure and umbrella effort known as Pathways. We count on to see substantial progress on this space, as we mix collectively many concepts that up to now have been pursued comparatively independently.
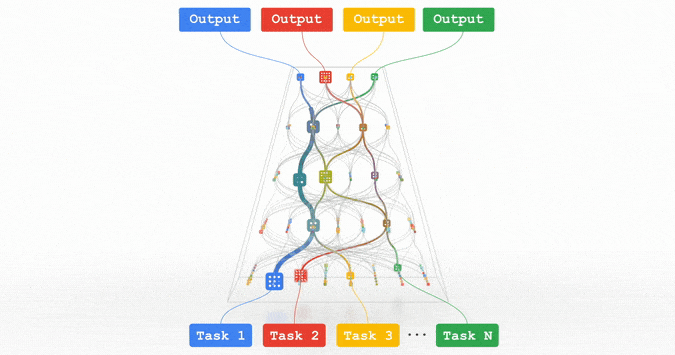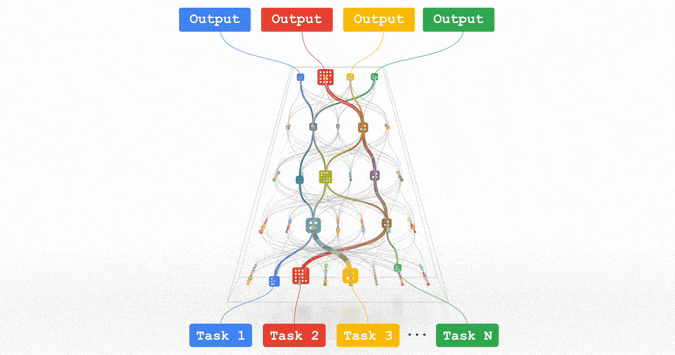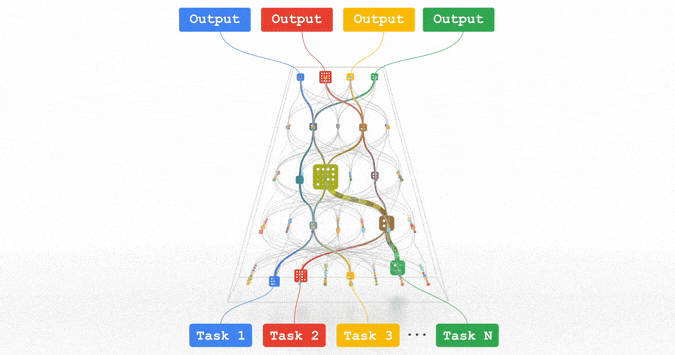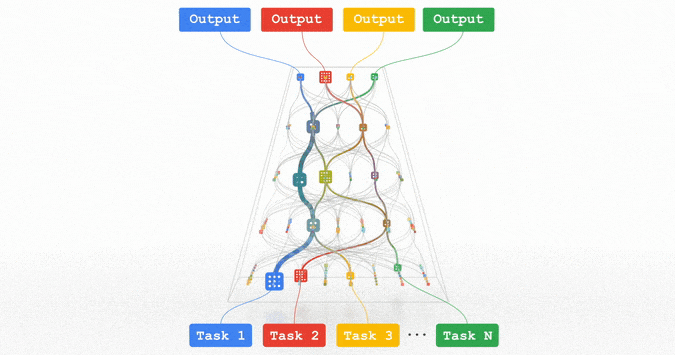 |
| Pathways: an outline of a single mannequin we’re working in direction of that may generalize throughout tens of millions of duties. |
Development 2: Continued Effectivity Enhancements for ML
Enhancements in effectivity — arising from advances in pc {hardware} design in addition to ML algorithms and meta-learning analysis — are driving better capabilities in ML fashions. Many features of the ML pipeline, from the {hardware} on which a mannequin is skilled and executed to particular person elements of the ML structure, might be optimized for effectivity whereas sustaining or enhancing on state-of-the-art efficiency total. Every of those completely different threads can enhance effectivity by a big multiplicative issue, and brought collectively, can scale back computational prices, together with CO2 equal emissions (CO2e), by orders of magnitude in comparison with just some years in the past. This better effectivity has enabled a lot of crucial advances that may proceed to dramatically enhance the effectivity of machine studying, enabling bigger, greater high quality ML fashions to be developed cheaply and additional democratizing entry. I’m very enthusiastic about these instructions of analysis!
Continued Enhancements in ML Accelerator Efficiency
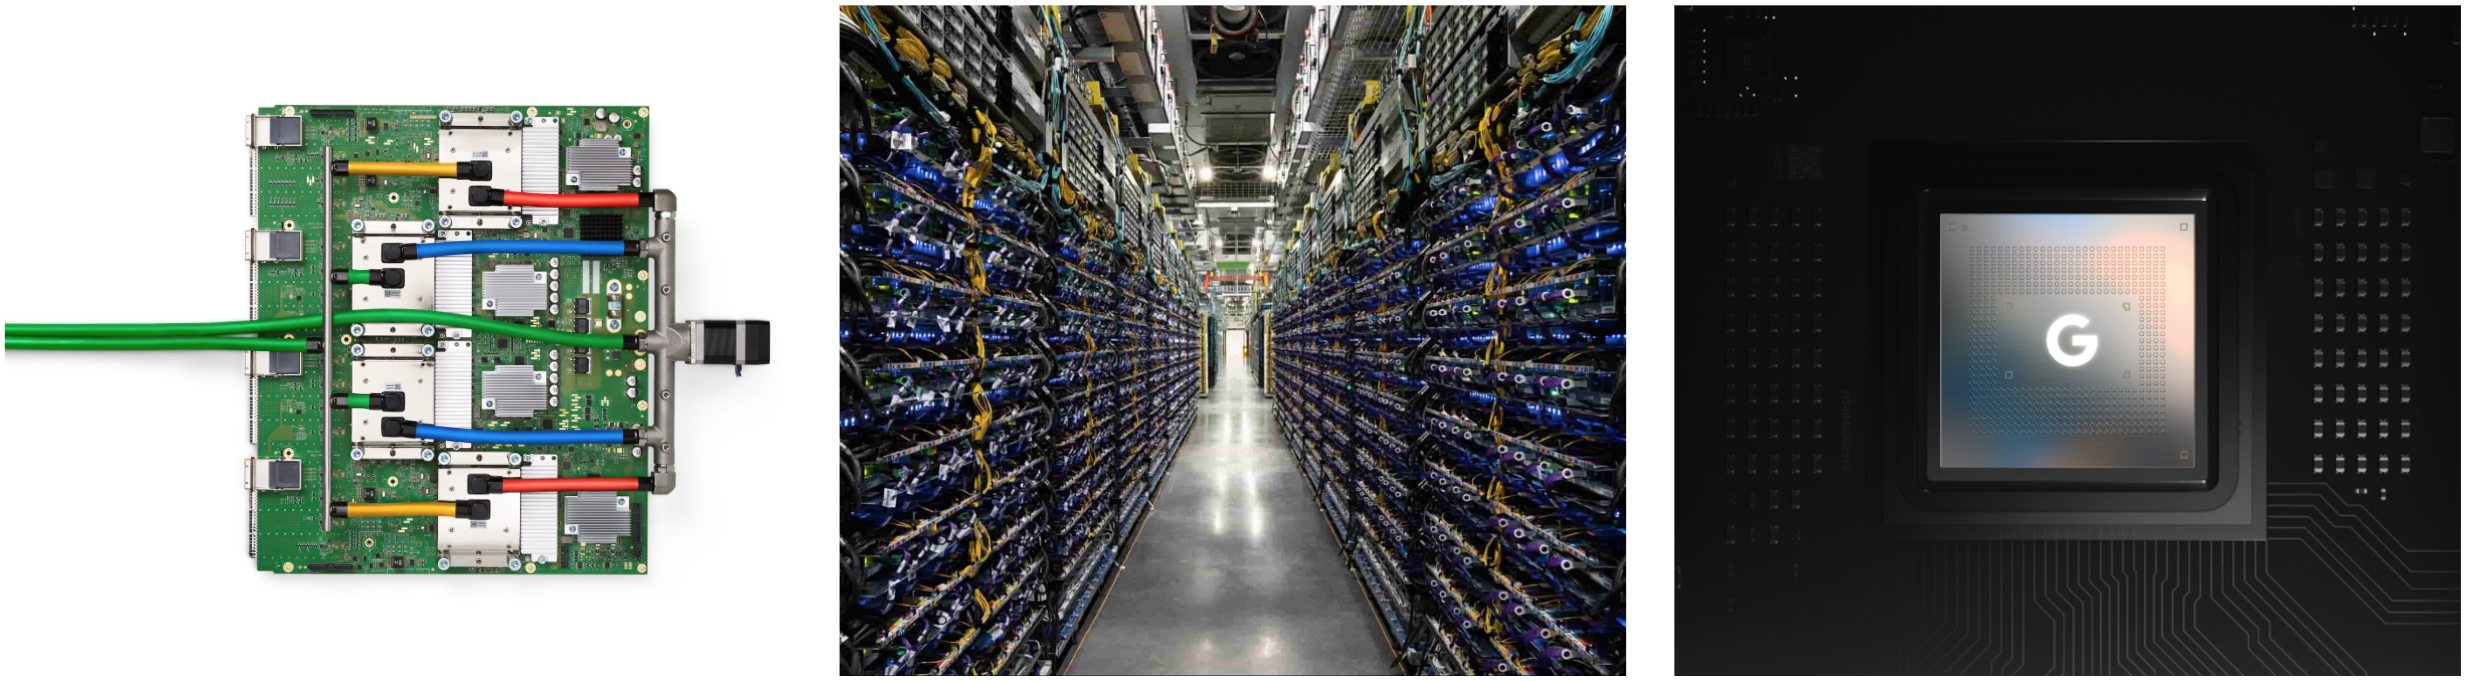
Every technology of ML accelerator improves on earlier generations, enabling quicker efficiency per chip, and infrequently rising the dimensions of the general programs. Final 12 months, we introduced our TPUv4 programs, the fourth technology of Google’s Tensor Processing Unit, which demonstrated a 2.7x enchancment over comparable TPUv3 ends in the MLPerf benchmarks. Every TPUv4 chip has ~2x the height efficiency per chip versus the TPUv3 chip, and the dimensions of every TPUv4 pod is 4096 chips (4x that of TPUv3 pods), yielding a efficiency of roughly 1.1 exaflops per pod (versus ~100 petaflops per TPUv3 pod). Having pods with bigger numbers of chips which can be linked along with excessive pace networks improves effectivity for bigger fashions.
ML capabilities on cellular gadgets are additionally rising considerably. The Pixel 6 cellphone contains a model new Google Tensor processor that integrates a robust ML accelerator to higher assist necessary on-device options.
Left: TPUv4 board; Heart: A part of a TPUv4 pod; Proper: Google Tensor chip present in Pixel 6 telephones. Our use of ML to speed up the design of pc chips of every kind (extra on this beneath) can be paying dividends, significantly to provide higher ML accelerators.
Continued Enhancements in ML Compilation and Optimization of ML Workloads
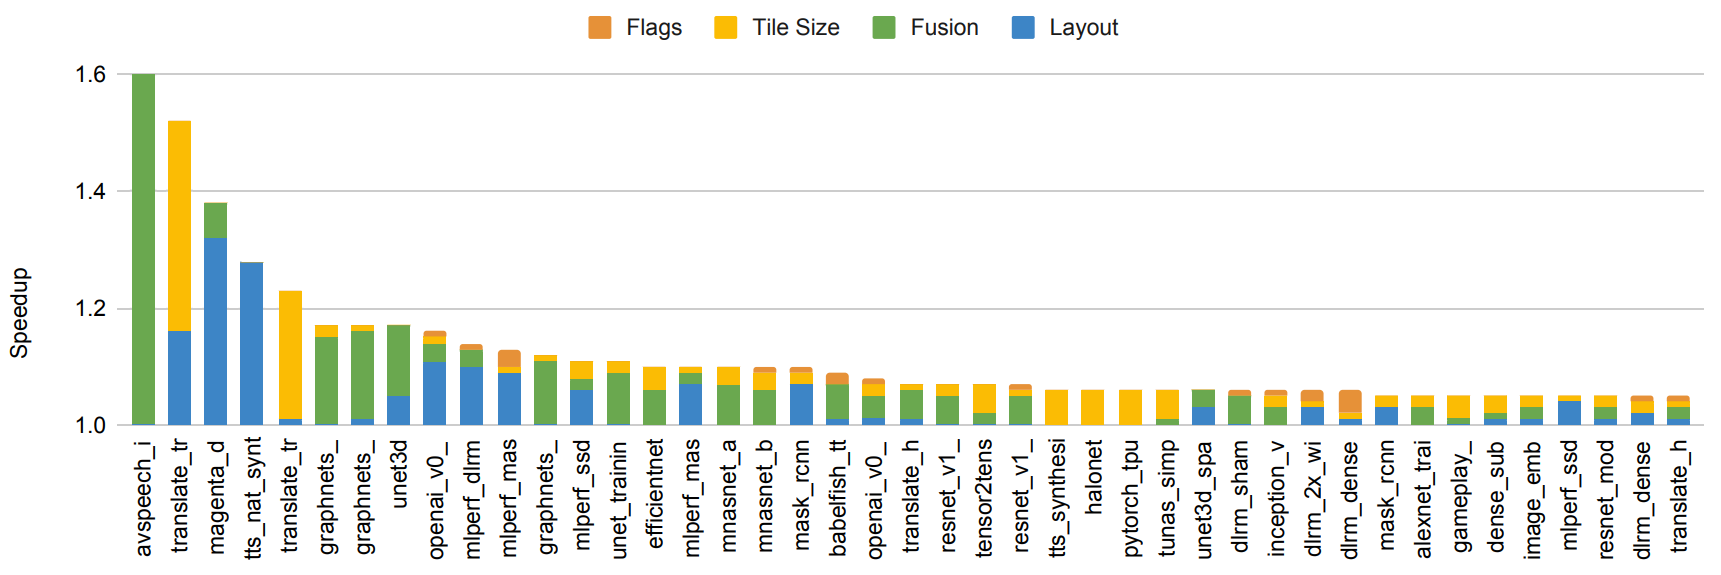
Even when the {hardware} is unchanged, enhancements in compilers and different optimizations in system software program for machine studying accelerators can result in vital enhancements in effectivity. For instance, “A Versatile Strategy to Autotuning Multi-pass Machine Studying Compilers” exhibits the right way to use machine studying to carry out auto-tuning of compilation settings to get across-the-board efficiency enhancements of 5-15% (and generally as a lot as 2.4x enchancment) for a set of ML packages on the identical underlying {hardware}. GSPMD describes an computerized parallelization system based mostly on the XLA compiler that’s able to scaling most deep studying community architectures past the reminiscence capability of an accelerator and has been utilized to many massive fashions, comparable to GShard-M4, LaMDA, BigSSL, ViT, MetNet-2, and GLaM, resulting in state-of-the-art outcomes throughout a number of domains.
Finish-to-end mannequin speedups from utilizing ML-based compiler autotuning on 150 ML fashions. Included are fashions that obtain enhancements of 5% or extra. Bar colours symbolize relative enchancment from optimizing completely different mannequin elements.
Human-Creativity–Pushed Discovery of Extra Environment friendly Mannequin Architectures
Continued enhancements in mannequin architectures give substantial reductions within the quantity of computation wanted to realize a given degree of accuracy for a lot of issues. For instance, the Transformer structure, which we developed in 2017, was capable of enhance the cutting-edge on a number of NLP and translation benchmarks whereas concurrently utilizing 10x to 100x much less computation to realize these outcomes than a wide range of different prevalent strategies, comparable to LSTMs and different recurrent architectures. Equally, the Imaginative and prescient Transformer was capable of present improved state-of-the-art outcomes on a lot of completely different picture classification duties regardless of utilizing 4x to 10x much less computation than convolutional neural networks.
Machine-Pushed Discovery of Extra Environment friendly Mannequin Architectures
Neural structure search (NAS) can mechanically uncover new ML architectures which can be extra environment friendly for a given drawback area. A major benefit of NAS is that it will probably tremendously scale back the hassle wanted for algorithm growth, as a result of NAS requires solely a one-time effort per search area and drawback area mixture. As well as, whereas the preliminary effort to carry out NAS might be computationally costly, the ensuing fashions can tremendously scale back computation in downstream analysis and manufacturing settings, leading to tremendously decreased useful resource necessities total. For instance, the one-time search to find the Advanced Transformer generated solely 3.2 tons of CO2e (a lot lower than the 284t CO2e reported elsewhere; see Appendix C and D on this joint Google/UC Berkeley preprint), however yielded a mannequin to be used by anybody within the NLP neighborhood that’s 15-20% extra environment friendly than the plain Transformer mannequin. A more moderen use of NAS found an much more environment friendly structure known as Primer (that has additionally been open-sourced), which reduces coaching prices by 4x in comparison with a plain Transformer mannequin. On this manner, the invention prices of NAS searches are sometimes recouped from using the more-efficient mannequin architectures which can be found, even when they’re utilized to solely a handful of downstream makes use of (and plenty of NAS outcomes are reused 1000’s of occasions).
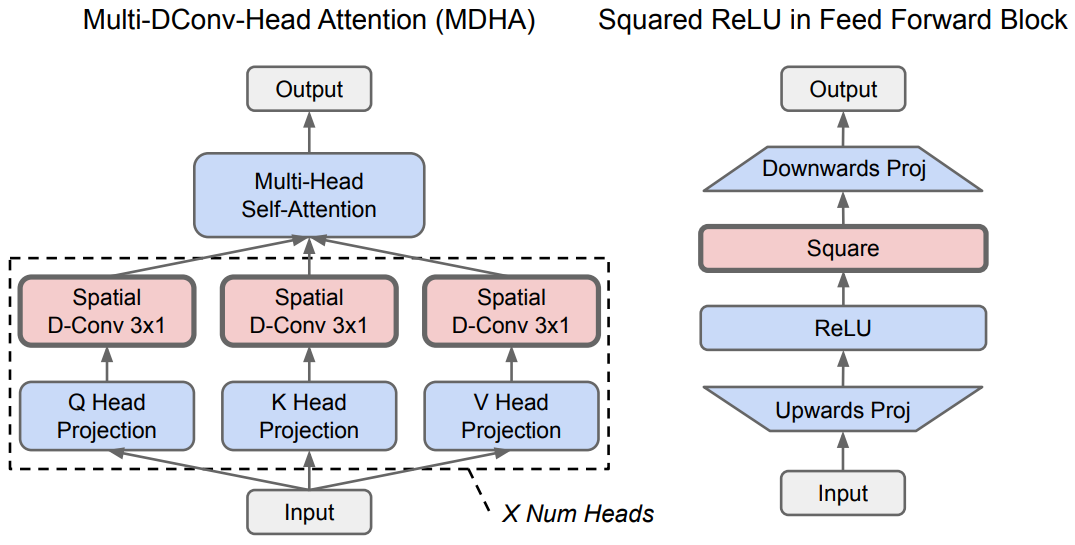
The Primer structure found by NAS is 4x as environment friendly in contrast with a plain Transformer mannequin. This picture exhibits (in pink) the 2 foremost modifications that give Primer most of its positive aspects: depthwise convolution added to consideration multi-head projections and squared ReLU activations (blue signifies parts of the unique Transformer). NAS has additionally been used to find extra environment friendly fashions within the imaginative and prescient area. The EfficientNetV2 mannequin structure is the results of a neural structure search that collectively optimizes for mannequin accuracy, mannequin measurement, and coaching pace. On the ImageNet benchmark, EfficientNetV2 improves coaching pace by 5–11x whereas considerably decreasing mannequin measurement over earlier state-of-the-art fashions. The CoAtNet mannequin structure was created with an structure search that makes use of concepts from the Imaginative and prescient Transformer and convolutional networks to create a hybrid mannequin structure that trains 4x quicker than the Imaginative and prescient Transformer and achieves a brand new ImageNet cutting-edge.
The broad use of search to assist enhance ML mannequin architectures and algorithms, together with using reinforcement studying and evolutionary methods, has impressed different researchers to use this strategy to completely different domains. To help others in creating their very own mannequin searches, we’ve open-sourced Mannequin Search, a platform that permits others to discover mannequin seek for their domains of curiosity. Along with mannequin architectures, automated search will also be used to seek out new, extra environment friendly reinforcement studying algorithms, constructing on the sooner AutoML-Zero work that demonstrated this strategy for automating supervised studying algorithm discovery.
Use of Sparsity
Sparsity, the place a mannequin has a really massive capability, however just some components of the mannequin are activated for a given job, instance or token, is one other necessary algorithmic advance that may tremendously enhance effectivity. In 2017, we launched the sparsely-gated mixture-of-experts layer, which demonstrated higher outcomes on a wide range of translation benchmarks whereas utilizing 10x much less computation than earlier state-of-the-art dense LSTM fashions. Extra lately, Swap Transformers, which pair a mixture-of-experts–fashion structure with the Transformer mannequin structure, demonstrated a 7x speedup in coaching time and effectivity over the dense T5-Base Transformer mannequin. The GLaM mannequin confirmed that transformers and mixture-of-expert–fashion layers might be mixed to provide a mannequin that exceeds the accuracy of the GPT-3 mannequin on common throughout 29 benchmarks utilizing 3x much less power for coaching and 2x much less computation for inference. The notion of sparsity will also be utilized to scale back the price of the eye mechanism within the core Transformer structure.
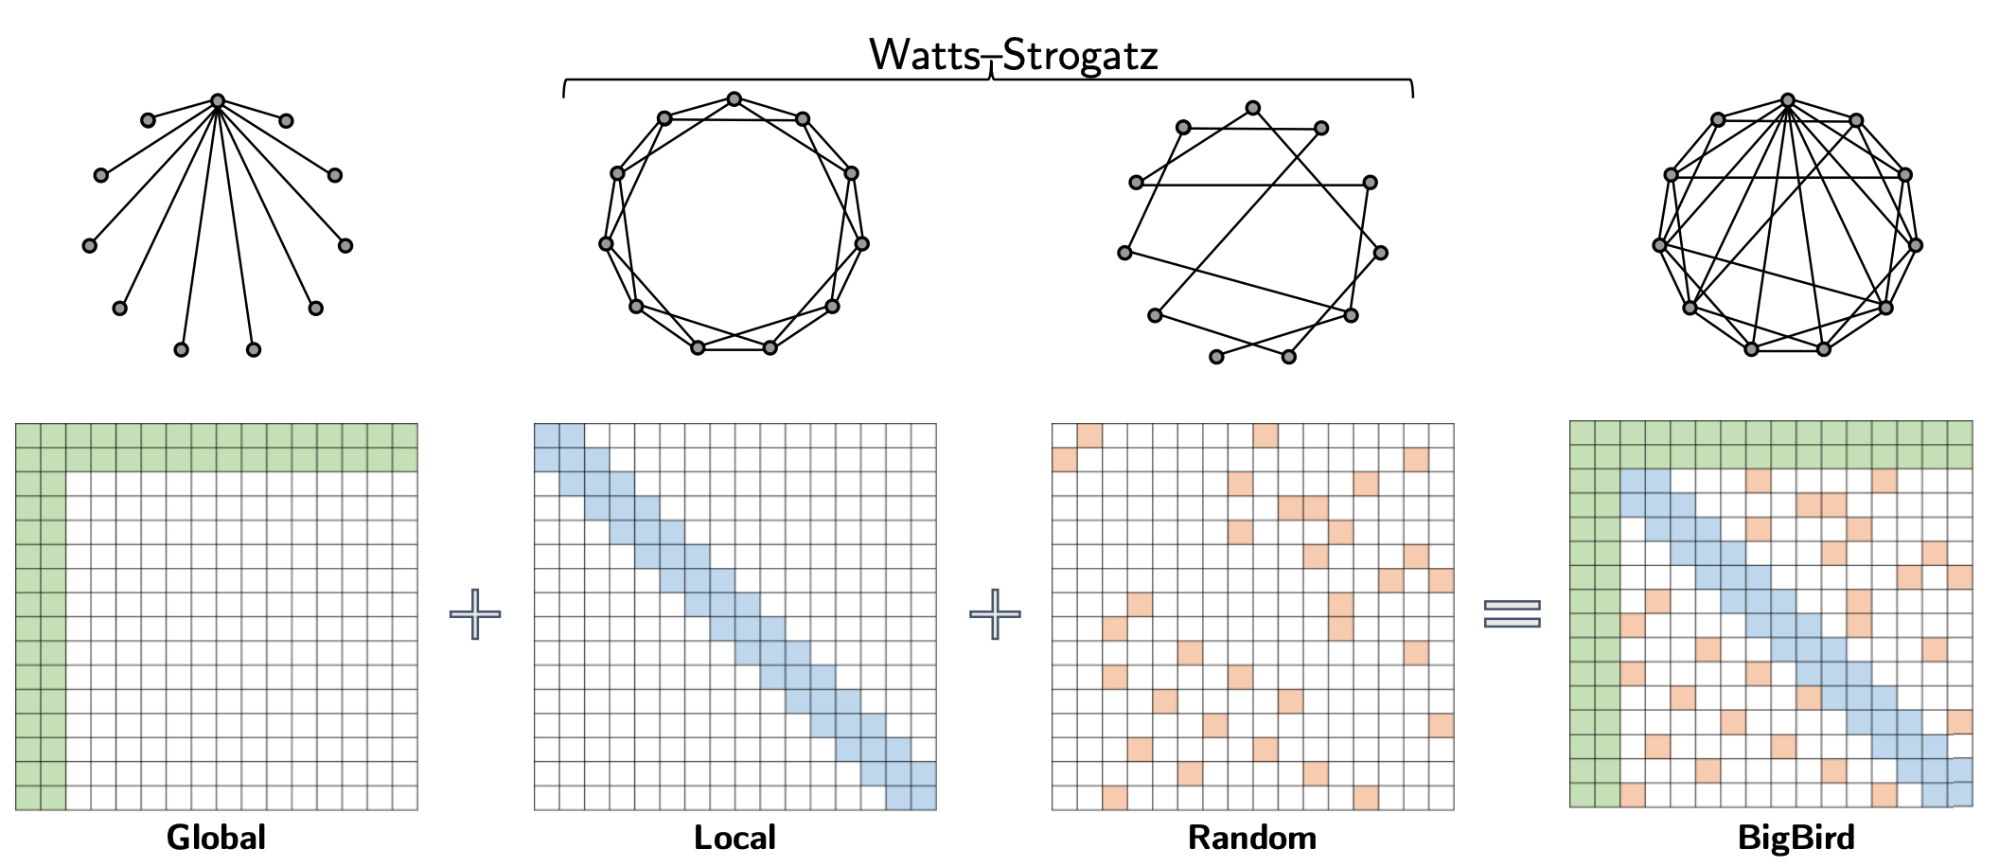
The BigBird sparse consideration mannequin consists of world tokens that attend to all components of an enter sequence, native tokens, and a set of random tokens. Theoretically, this may be interpreted as including just a few world tokens on a Watts-Strogatz graph. The usage of sparsity in fashions is clearly an strategy with very excessive potential payoff by way of computational effectivity, and we’re solely scratching the floor by way of analysis concepts to be tried on this route.
Every of those approaches for improved effectivity might be mixed collectively in order that equivalent-accuracy language fashions skilled right this moment in environment friendly information facilities are ~100 occasions extra power environment friendly and produce ~650 occasions much less CO2e emissions, in comparison with a baseline Transformer mannequin skilled utilizing P100 GPUs in a median U.S. datacenter utilizing a median U.S. power combine. And this doesn’t even account for Google’s carbon-neutral, 100% renewable power offsets. We’ll have a extra detailed weblog submit analyzing the carbon emissions developments of NLP fashions quickly.
Development 3: ML Is Changing into Extra Personally and Communally Helpful
A bunch of recent experiences are made potential as innovation in ML and silicon {hardware} (just like the Google Tensor processor on the Pixel 6) allow cellular gadgets to be extra able to constantly and effectively sensing their surrounding context and setting. These advances have improved accessibility and ease of use, whereas additionally boosting computational energy, which is crucial for in style options like cellular pictures, dwell translation and extra. Remarkably, current technological advances additionally present customers with a extra personalized expertise whereas strengthening privateness safeguards.
Extra folks than ever depend on their cellphone cameras to report their every day lives and for creative expression. The intelligent utility of ML to computational pictures has continued to advance the capabilities of cellphone cameras, making them simpler to make use of, enhancing efficiency, and leading to higher-quality photographs. Advances, comparable to improved HDR+, the power to take photos in very low mild, higher dealing with of portraits, and efforts to make cameras extra inclusive in order that they work for all pores and skin tones, yield higher images which can be extra true to the photographer’s imaginative and prescient and to their topics. Such images might be additional improved utilizing the highly effective ML-based instruments now obtainable in Google Images, like cinematic images, noise and blur discount, and the Magic Eraser.
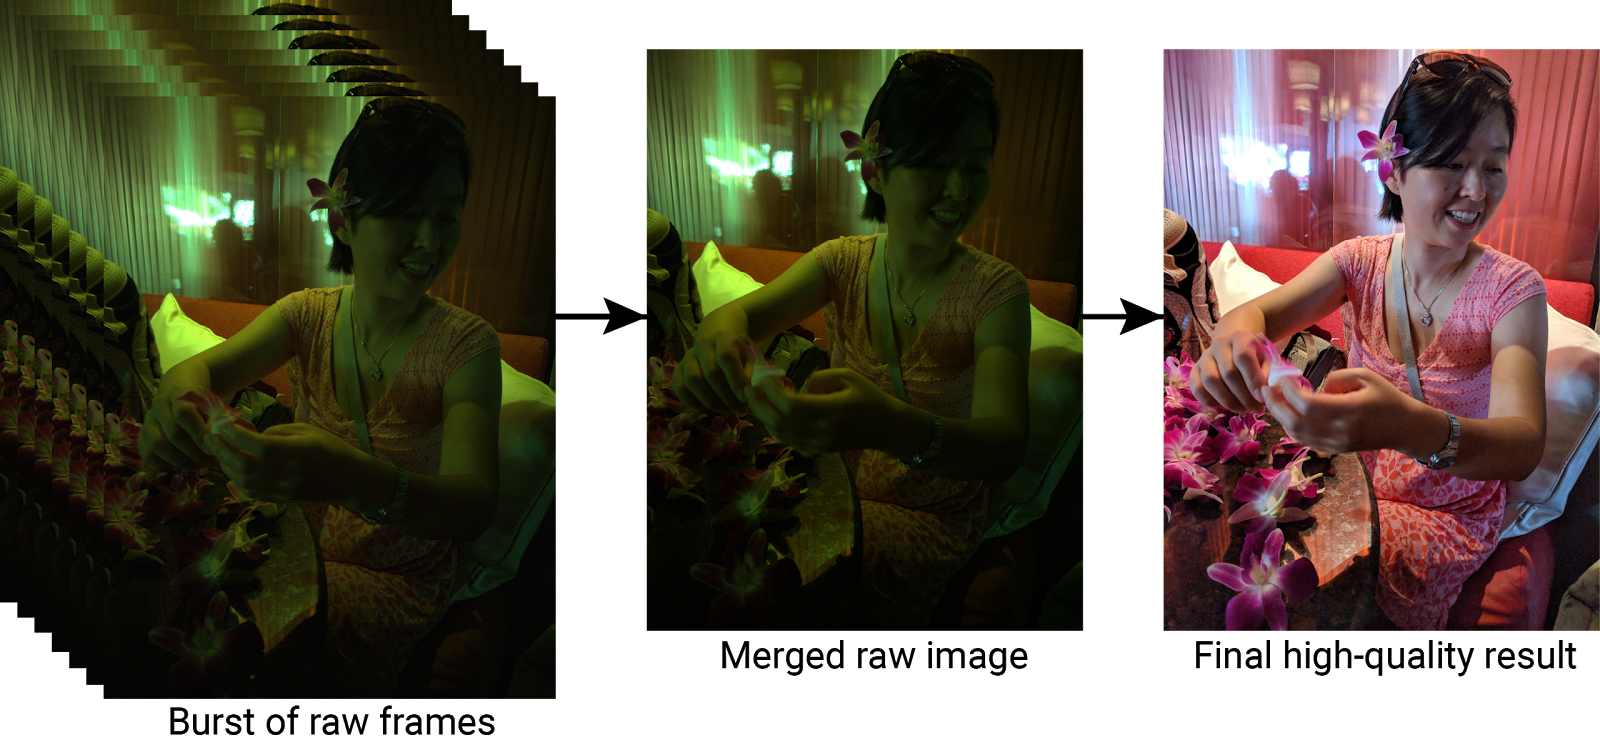 |
| HDR+ begins from a burst of full-resolution uncooked photographs, every underexposed by the identical quantity (left). The merged picture has decreased noise and elevated dynamic vary, resulting in a better high quality ultimate consequence (proper). |
Along with utilizing their telephones for inventive expression, many individuals depend on them to assist talk with others throughout languages and modalities in real-time utilizing Stay Translate in messaging apps and Stay Caption for cellphone calls. Speech recognition accuracy has continued to make substantial enhancements due to methods like self-supervised studying and noisy pupil coaching, with marked enhancements for accented speech, noisy situations or environments with overlapping speech, and throughout many languages. Constructing on advances in text-to-speech synthesis, folks can hearken to net pages and articles utilizing our Learn Aloud expertise on a rising quantity of platforms, making info extra obtainable throughout boundaries of modality and languages. Stay speech translations within the Google Translate app have develop into considerably higher by stabilizing the translations which can be generated on-the-fly, and prime quality, strong and accountable direct speech-to-speech translation offers a significantly better person expertise in speaking with folks talking a special language. New work on combining ML with conventional codec approaches within the Lyra speech codec and the extra common SoundStream audio codec permits greater constancy speech, music, and different sounds to be communicated reliably at a lot decrease bitrate.
On a regular basis interactions have gotten far more pure with options like computerized name screening and ML brokers that may wait on maintain for you, due to advances in Duplex. Even brief duties that customers might carry out ceaselessly have been improved with instruments comparable to Sensible Textual content Choice, which mechanically selects entities like cellphone numbers or addresses for straightforward copy and pasting, and grammar correction as you sort on Pixel 6 telephones. As well as, Display screen Consideration prevents the cellphone display screen from dimming when you find yourself taking a look at it and enhancements in gaze recognition are opening up new use instances for accessibility and for improved wellness and well being. ML can be enabling new strategies for guaranteeing the protection of individuals and communities. For instance, Suspicious Message Alerts warn in opposition to potential phishing assaults and Safer Routing detects hard-braking occasions to counsel alternate routes.
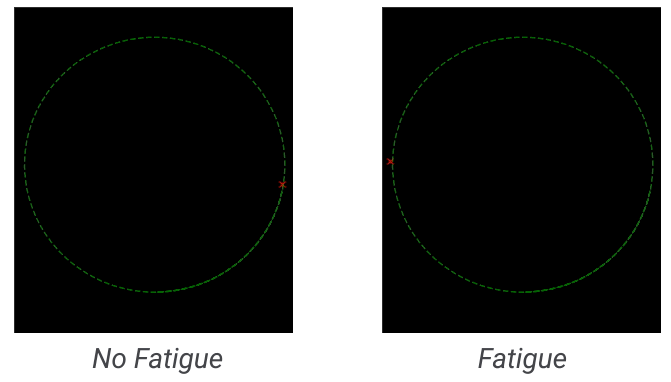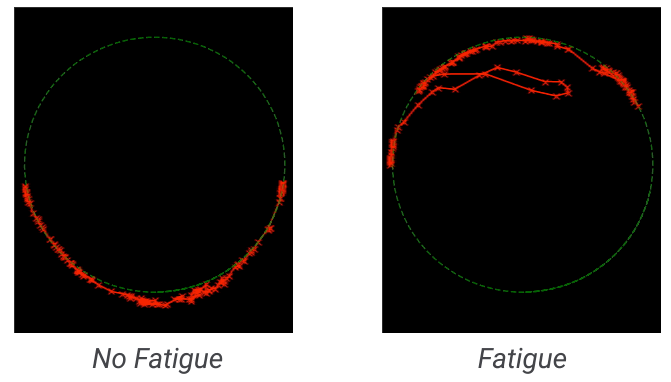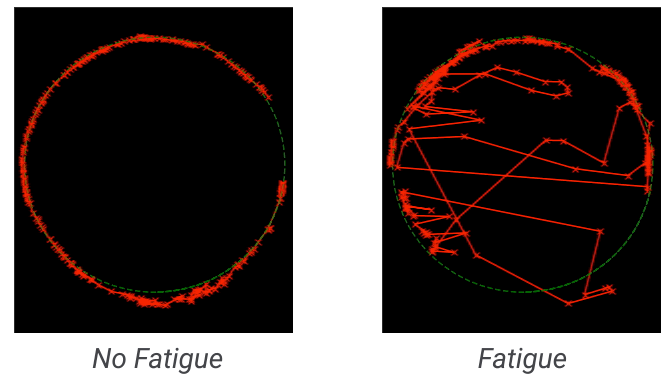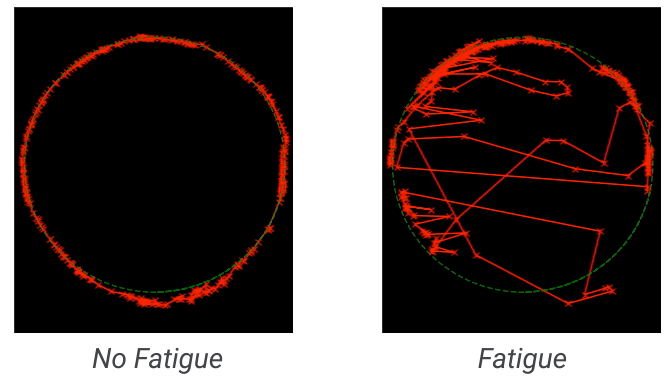 |
| Current work demonstrates the power of gaze recognition as an necessary biomarker of psychological fatigue. |
Given the possibly delicate nature of the info that underlies these new capabilities, it’s important that they’re designed to be personal by default. Lots of them run inside Android’s Non-public Compute Core — an open supply, safe setting remoted from the remainder of the working system. Android ensures that information processed within the Non-public Compute Core just isn’t shared to any apps with out the person taking an motion. Android additionally prevents any characteristic contained in the Non-public Compute Core from having direct entry to the community. As a substitute, options talk over a small set of open-source APIs to Non-public Compute Companies, which strips out figuring out info and makes use of privateness applied sciences, together with federated studying, federated analytics, and personal info retrieval, enabling studying whereas concurrently guaranteeing privateness.
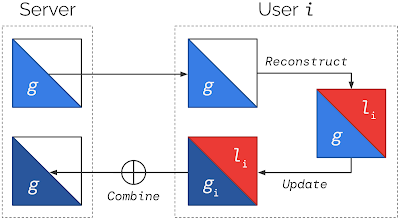 |
| Federated Reconstruction is a novel partially native federated studying method during which fashions are partitioned into world and native parameters. For every spherical of Federated Reconstruction coaching: (1) The server sends the present world parameters g to every person i; (2) Every person i freezes g and reconstructs their native parameters li; (3) Every person i freezes li and updates g to provide gi; (4) Customers’ gi are averaged to provide the worldwide parameters for the subsequent spherical. |
These applied sciences are crucial to evolving next-generation computation and interplay paradigms, whereby private or communal gadgets can each study from and contribute to coaching a collective mannequin of the world with out compromising privateness. A federated unsupervised strategy to privately study the sorts of aforementioned general-purpose fashions with fine-tuning for a given job or context might unlock more and more clever programs which can be much more intuitive to work together with — extra like a social entity than a machine. Broad and equitable entry to those clever interfaces will solely be potential with deep adjustments to our expertise stacks, from the edge to the datacenter, in order that they correctly assist neural computing.
Development 4: Rising Impression of ML in Science, Well being and Sustainability
Lately, we’ve seen an rising affect of ML within the primary sciences, from physics to biology, with a lot of thrilling sensible functions in associated realms, comparable to renewable power and drugs. Laptop imaginative and prescient fashions have been deployed to handle issues at each private and world scales. They’ll help physicians of their common work, develop our understanding of neural physiology, and likewise present higher climate forecasts and streamline catastrophe reduction efforts. Different varieties of ML fashions are proving crucial in addressing local weather change by discovering methods to cut back emissions and enhancing the output of other power sources. Such fashions may even be leveraged as inventive instruments for artists! As ML turns into extra strong, well-developed, and extensively accessible, its potential for high-impact functions in a broad array of real-world domains continues to develop, serving to to unravel a few of our most difficult issues.
Giant-Scale Software of Laptop Imaginative and prescient for New Insights
The advances in pc imaginative and prescient over the previous decade have enabled computer systems for use for all kinds of duties throughout completely different scientific domains. In neuroscience, automated reconstruction methods can recuperate the neural connective construction of mind tissues from excessive decision electron microscopy photographs of skinny slices of mind tissue. In earlier years, we’ve collaborated to create such assets for fruit fly, mouse, and songbird brains, however final 12 months, we collaborated with the Lichtman Lab at Harvard College to investigate the biggest pattern of mind tissue imaged and reconstructed on this degree of element, in any species, and produced the primary large-scale research of synaptic connectivity within the human cortex that spans a number of cell sorts throughout all layers of the cortex. The objective of this work is to provide a novel useful resource to help neuroscientists in finding out the gorgeous complexity of the human mind. The picture beneath, for instance, exhibits six neurons out of about 86 billion neurons in an grownup human mind.
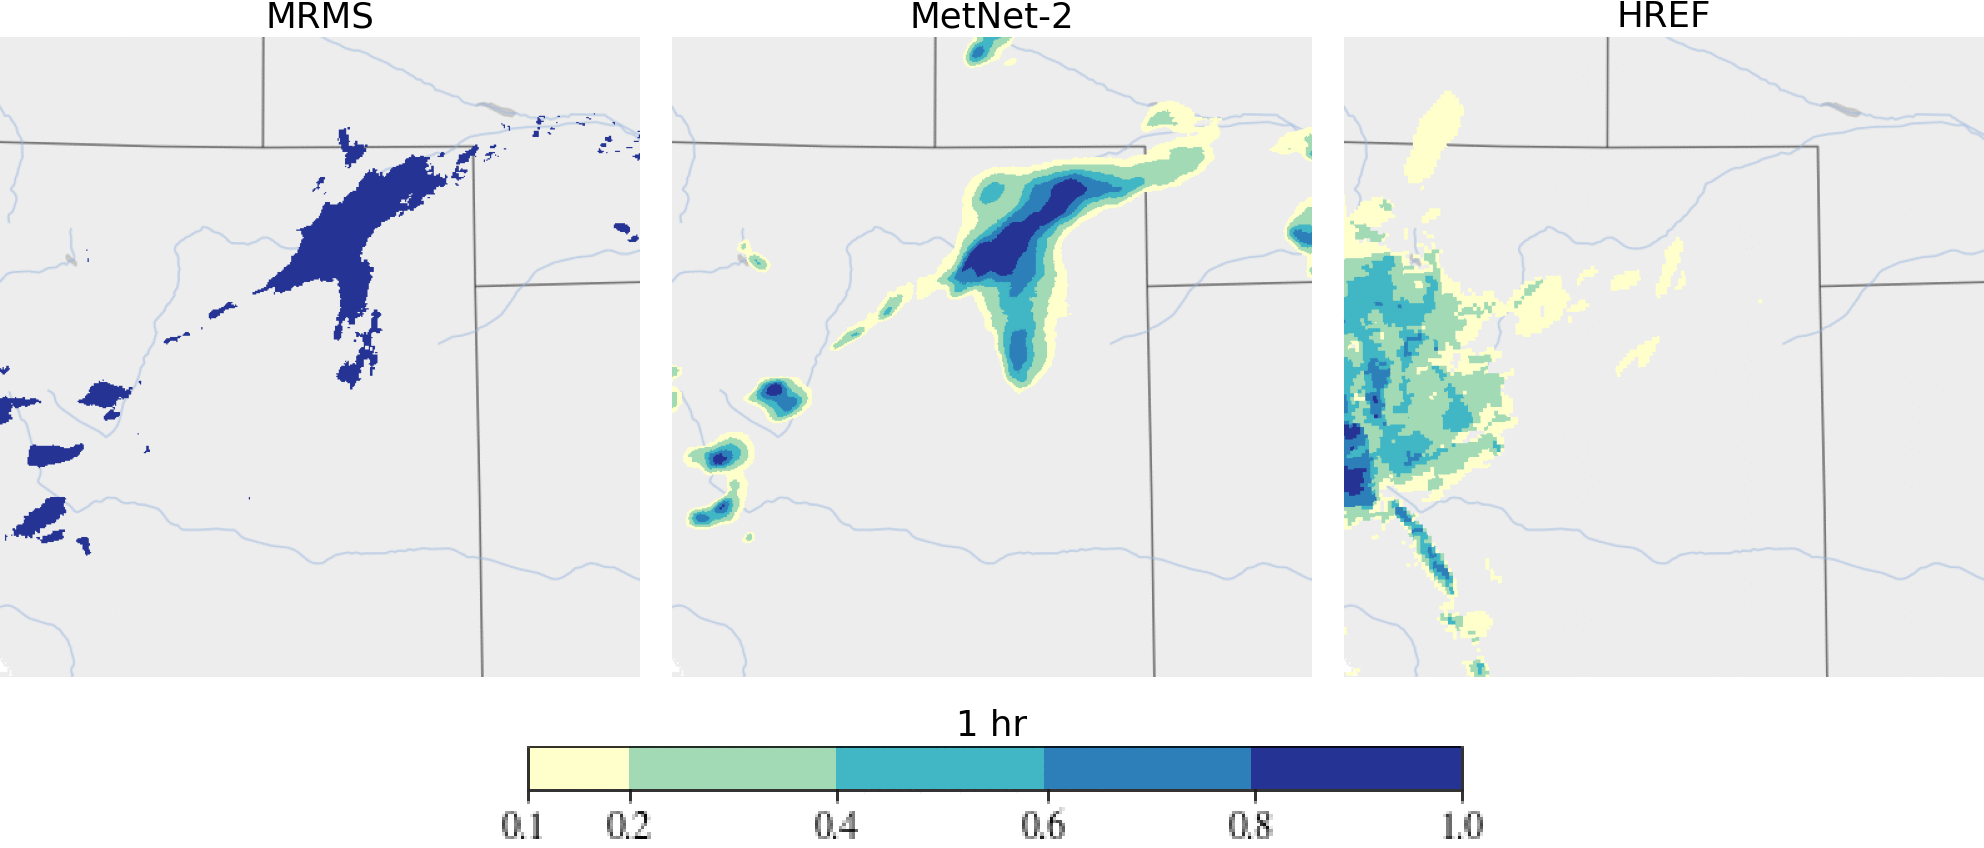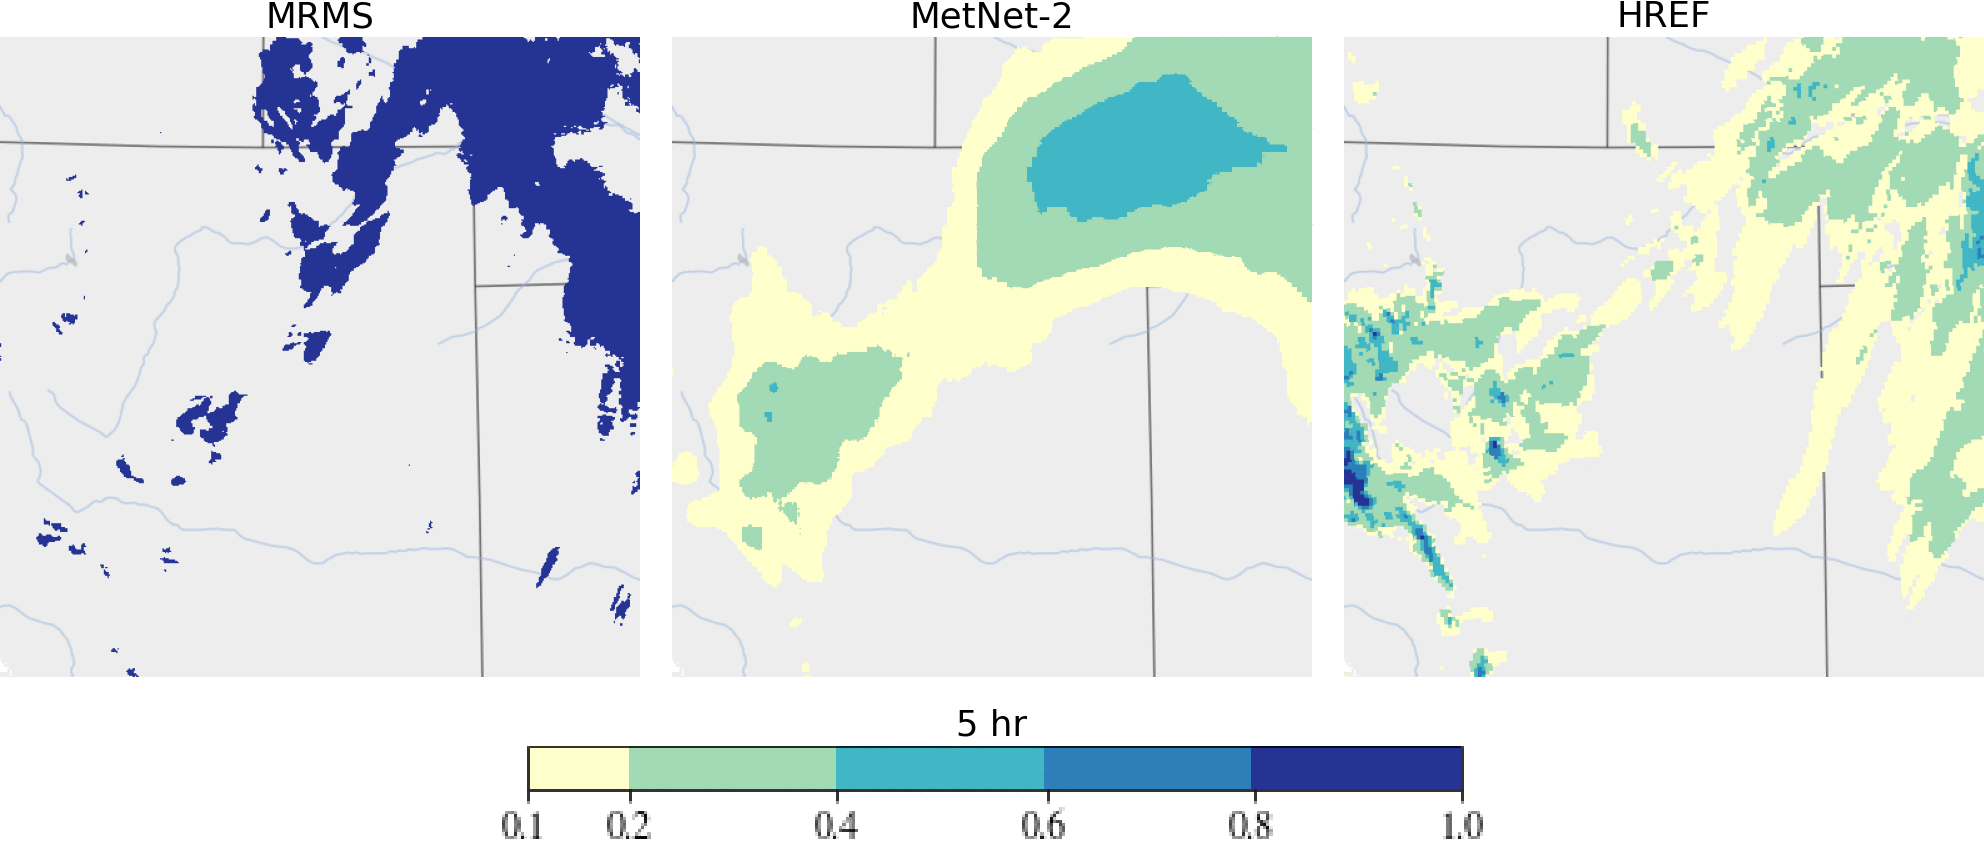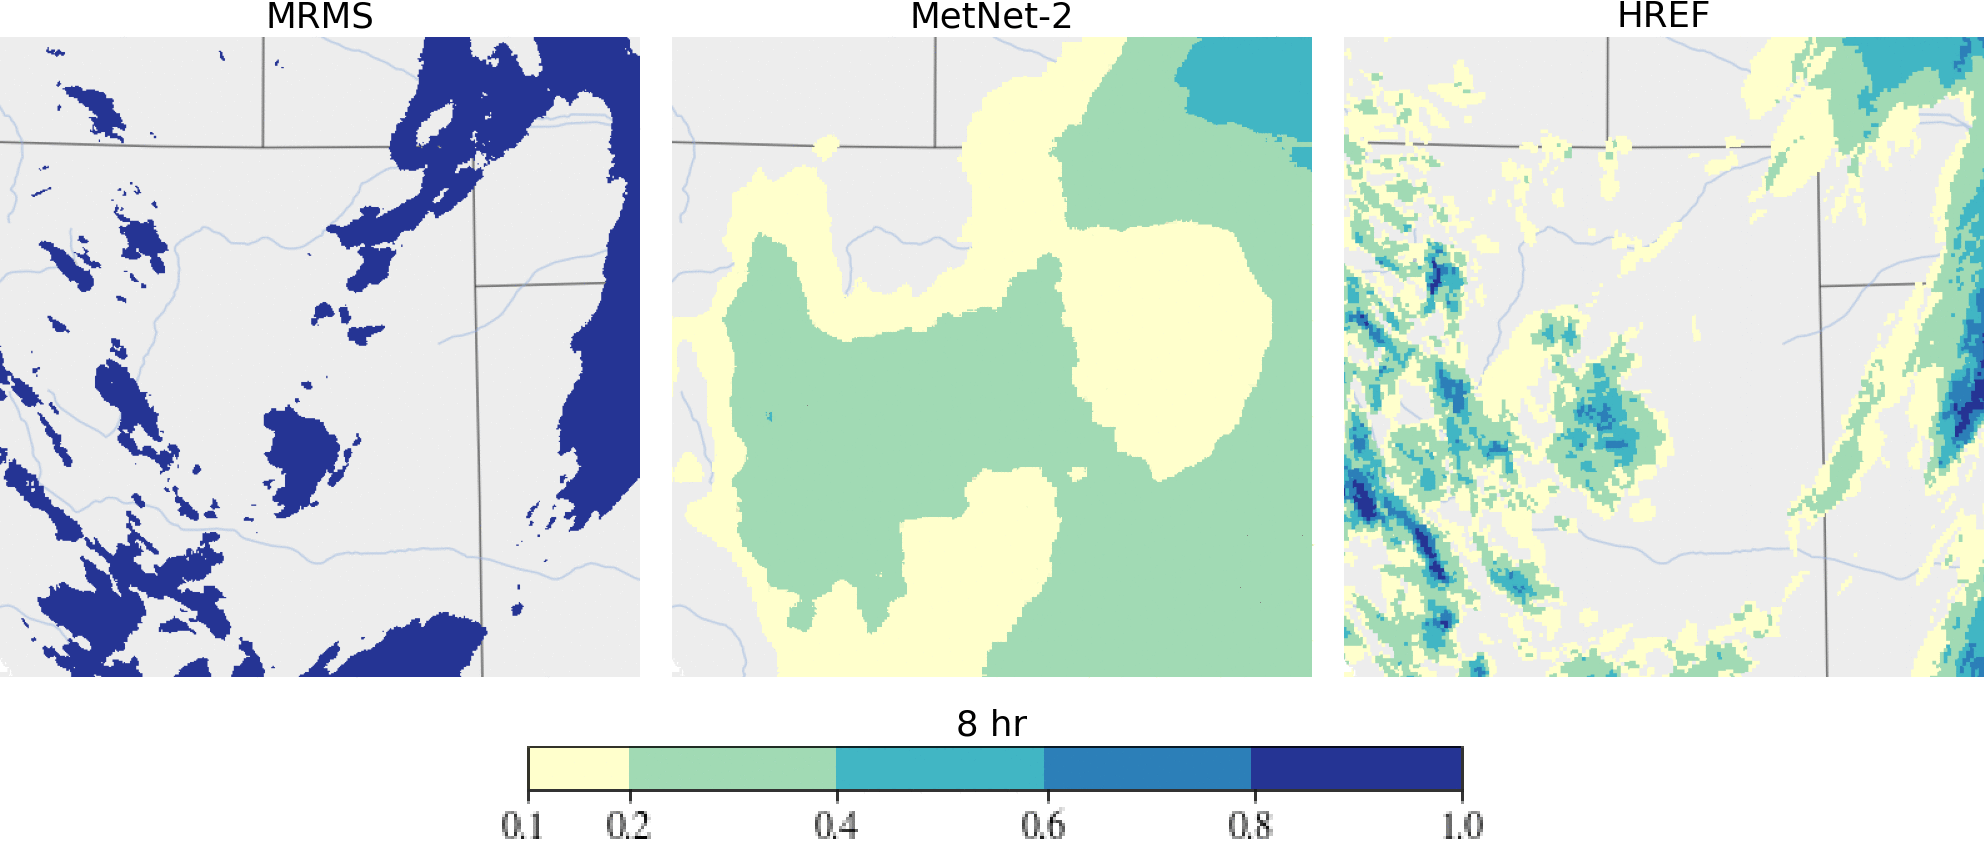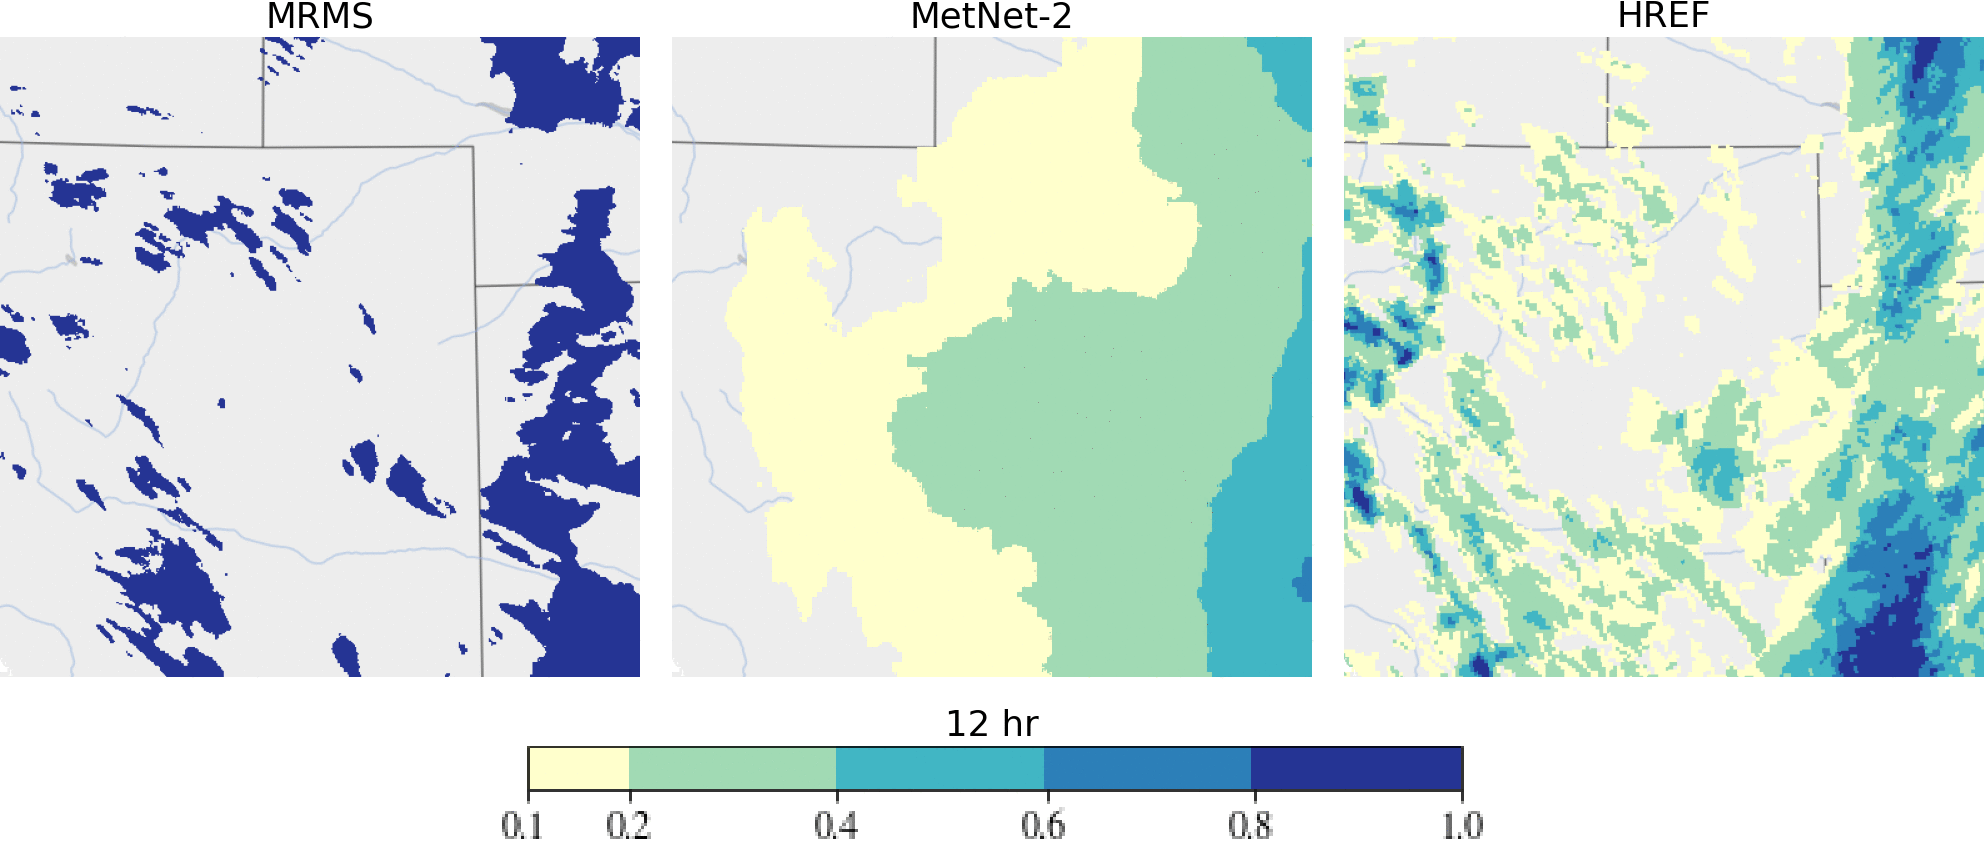
Laptop imaginative and prescient expertise additionally offers highly effective instruments to handle challenges at a lot bigger, even world, scales. A deep-learning–based mostly strategy to climate forecasting that makes use of satellite tv for pc and radar imagery as inputs, mixed with different atmospheric information, produces climate and precipitation forecasts which can be extra correct than conventional physics-based fashions at forecasting occasions as much as 12 hours. They’ll additionally produce up to date forecasts far more shortly than conventional strategies, which might be crucial in occasions of maximum climate.
Comparability of 0.2 mm/hr precipitation on March 30, 2020 over Denver, Colorado. Left: Floor fact, supply MRMS. Heart: Likelihood map as predicted by MetNet-2. Proper: Likelihood map as predicted by the physics-based HREF mannequin. MetNet-2 is ready to predict the onset of the storm earlier within the forecast than HREF in addition to the storm’s beginning location, whereas HREF misses the initiation location, however captures its development section nicely. Having an correct report of constructing footprints is crucial for a spread of functions, from inhabitants estimation and concrete planning to humanitarian response and environmental science. In lots of components of the world, together with a lot of Africa, this info wasn’t beforehand obtainable, however new work exhibits that utilizing pc imaginative and prescient methods utilized to satellite tv for pc imagery might help determine constructing boundaries at continental scales. The outcomes of this strategy have been launched within the Open Buildings dataset, a brand new open-access information useful resource that accommodates the places and footprints of 516 million buildings with protection throughout a lot of the African continent. We’ve additionally been in a position to make use of this distinctive dataset in our collaboration with the World Meals Programme to supply quick harm evaluation after pure disasters via utility of ML.
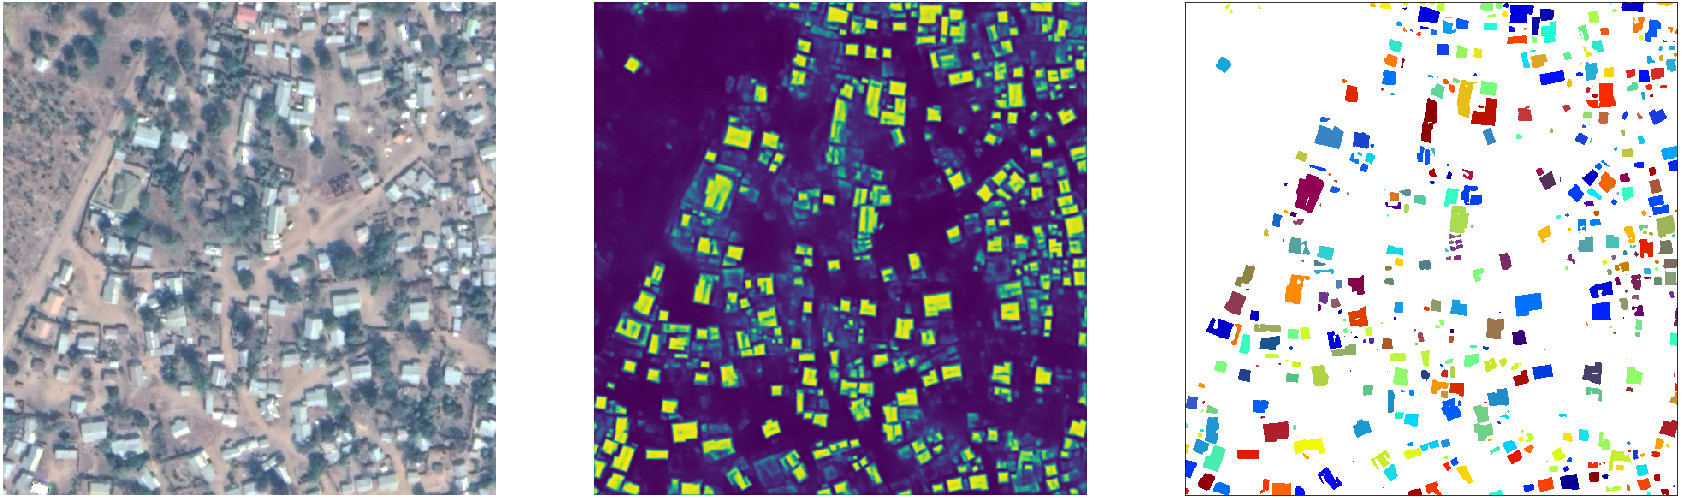
Instance of segmenting buildings in satellite tv for pc imagery. Left: Supply picture; Heart: Semantic segmentation, with every pixel assigned a confidence rating that it’s a constructing vs. non-building; Proper: Occasion segmentation, obtained by thresholding and grouping collectively linked elements. A typical theme throughout every of those instances is that ML fashions are capable of carry out specialised duties effectively and precisely based mostly on evaluation of obtainable visible information, supporting excessive affect downstream duties.
Automated Design House Exploration
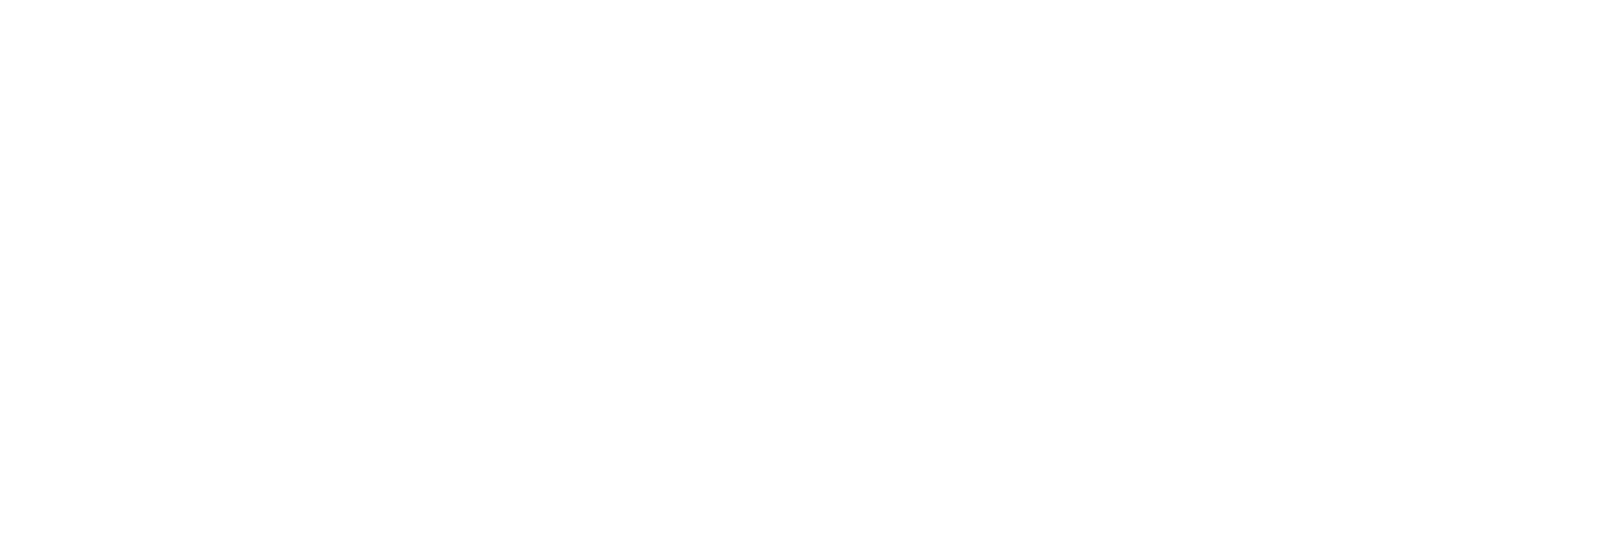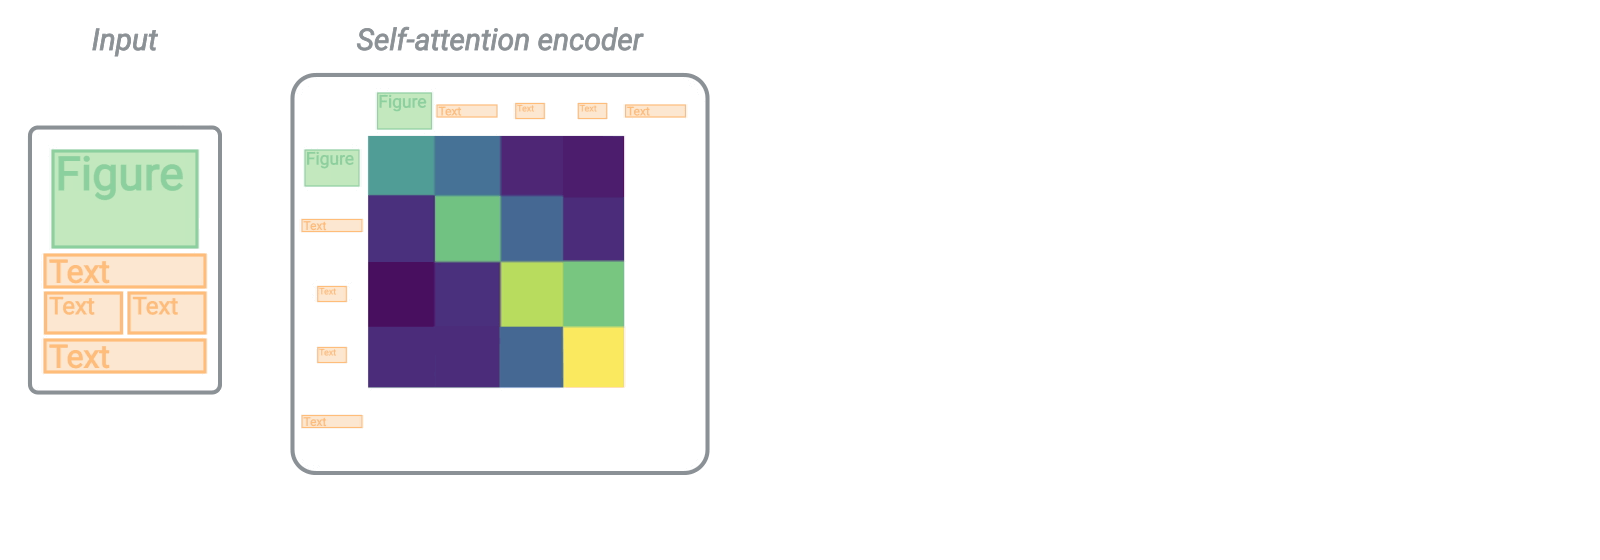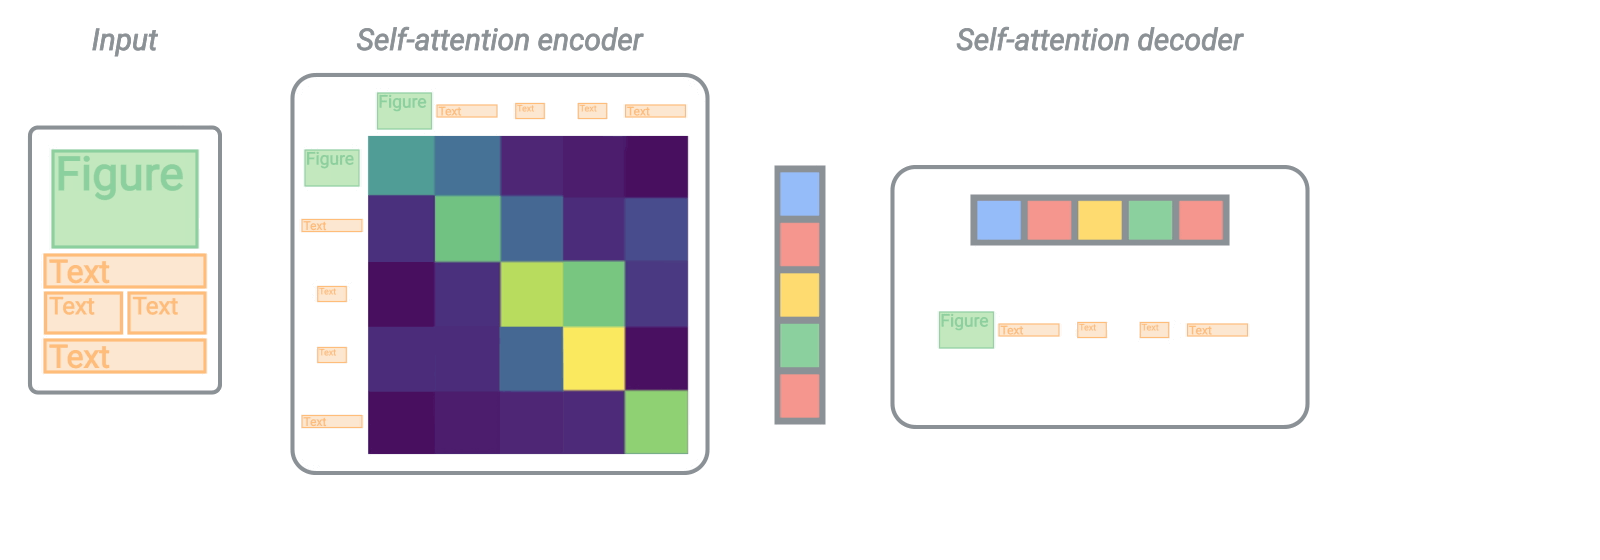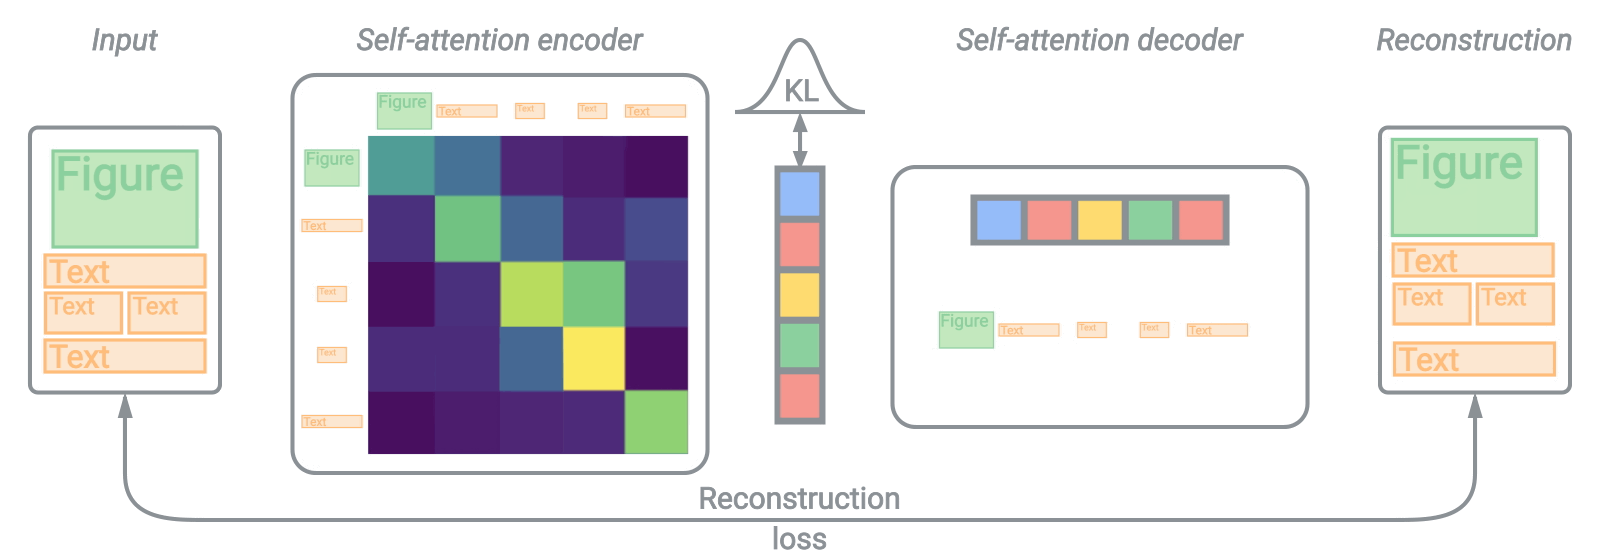
One other strategy that has yielded wonderful outcomes throughout many fields is to permit an ML algorithm to discover and consider an issue’s design area for potential options in an automatic manner. In a single utility, a Transformer-based variational autoencoder learns to create aesthetically-pleasing and helpful doc layouts, and the identical strategy might be prolonged to discover potential furnishings layouts. One other ML-driven strategy automates the exploration of the large design area of tweaks for pc sport guidelines to enhance playability and different attributes of a sport, enabling human sport designers to create fulfilling video games extra shortly.
A visualization of the Variational Transformer Community (VTN) mannequin, which is ready to extract significant relationships between the structure parts (paragraphs, tables, photographs, and many others.) as a way to generate reasonable artificial paperwork (e.g., with higher alignment and margins). Different ML algorithms have been used to consider the design area of pc architectural selections for ML accelerator chips themselves. We’ve additionally proven that ML can be utilized to shortly create chip placements for ASIC designs which can be higher than layouts generated by human specialists and might be generated in a matter of hours as an alternative of weeks. This reduces the fastened engineering prices of chips and lowers the barrier to shortly creating specialised {hardware} for various functions. We’ve efficiently used this automated placement strategy within the design of our upcoming TPU-v5 chip.
Such exploratory ML approaches have additionally been utilized to supplies discovery. In a collaboration between Google Analysis and Caltech, a number of ML fashions, mixed with a modified inkjet printer and a custom-built microscope, had been capable of quickly search over tons of of 1000’s of potential supplies to hone in on 51 beforehand uncharacterized three-metal oxide supplies with promising properties for functions in areas like battery expertise and electrolysis of water.
These automated design area exploration approaches might help speed up many scientific fields, particularly when your entire experimental loop of producing the experiment and evaluating the consequence can all be executed in an automatic or mostly-automated method. I count on to see this strategy utilized to good impact in lots of extra areas within the coming years.
Software to Well being
Along with advancing primary science, ML also can drive advances in drugs and human well being extra broadly. The thought of leveraging advances in pc science in well being is nothing new — actually a few of my very own early experiences had been in growing software program to assist analyze epidemiological information. However ML opens new doorways, raises new alternatives, and sure, poses new challenges.
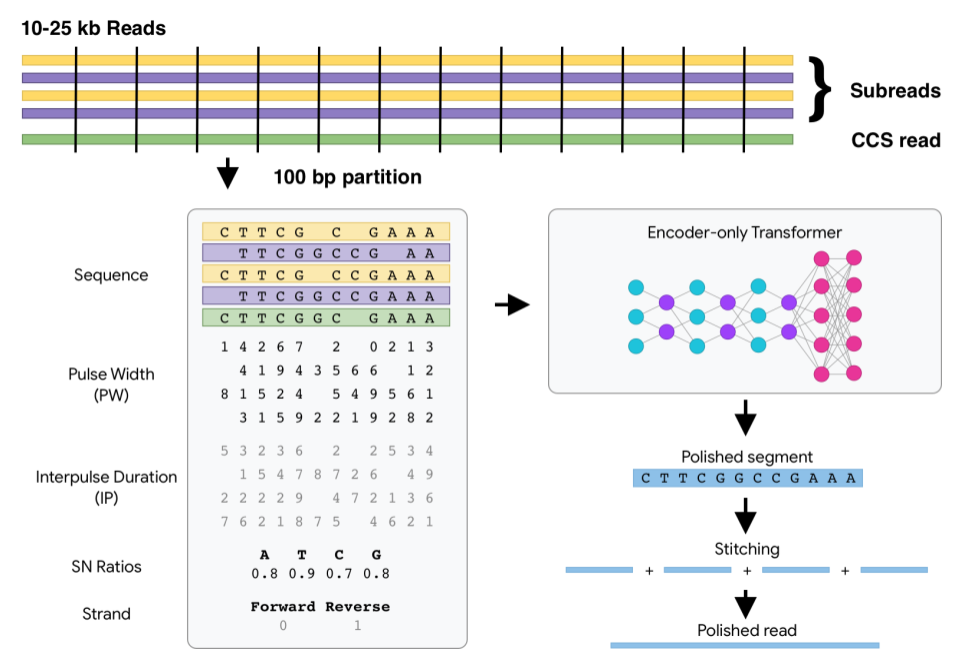
Take for instance the sphere of genomics. Computing has been necessary to genomics since its inception, however ML provides new capabilities and disrupts previous paradigms. When Google researchers started working on this space, the thought of utilizing deep studying to assist infer genetic variants from sequencer output was thought of far-fetched by many specialists. Immediately, this ML strategy is taken into account state-of-the-art. However the future holds an much more necessary function for ML — genomics firms are growing new sequencing devices which can be extra correct and quicker, but additionally current new inference challenges. Our launch of open-source software program DeepConsensus and, in collaboration with UCSC, PEPPER-DeepVariant, helps these new devices with cutting-edge informatics. We hope that extra speedy sequencing can result in close to time period applicability with affect for actual sufferers.
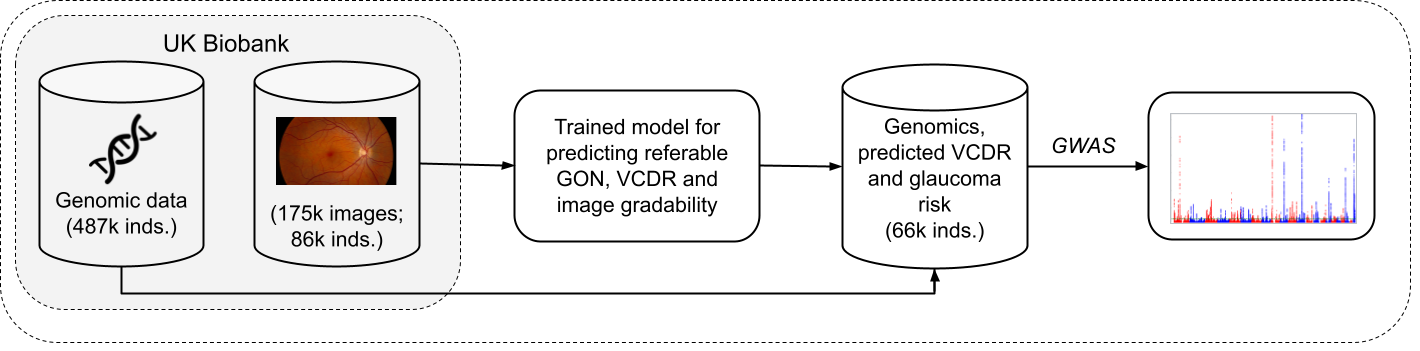
A schematic of the Transformer structure for DeepConsensus, which corrects sequencing errors to enhance yield and correctness. There are different alternatives to make use of ML to speed up our use of genomic info for personalised well being outdoors of processing the sequencer information. Giant biobanks of extensively phenotyped and sequenced people can revolutionize how we perceive and handle genetic predisposition to illness. Our ML-based phenotyping technique improves the scalability of changing massive imaging and textual content datasets into phenotypes usable for genetic affiliation research, and our DeepNull technique higher leverages massive phenotypic information for genetic discovery. We’re completely satisfied to launch each as open-source strategies for the scientific neighborhood.
The method for producing large-scale quantification of anatomical and illness traits for mixture with genomic information in Biobanks. Simply as ML helps us see hidden traits of genomics information, it will probably assist us uncover new info and glean new insights from different well being information sorts as nicely. Prognosis of illness is usually about figuring out a sample, quantifying a correlation, or recognizing a brand new occasion of a bigger class — all duties at which ML excels. Google researchers have used ML to deal with a variety of such issues, however maybe none of those has progressed farther than the functions of ML to medical imaging.
In actual fact, Google’s 2016 paper describing the utility of deep studying to the screening for diabetic retinopathy, was chosen by the editors of the Journal of the American Medical Affiliation (JAMA) as one of many high 10 most influential papers of the last decade — not simply essentially the most influential papers on ML and well being, essentially the most influential JAMA papers of the last decade total. However the power of our analysis doesn’t finish at contributions to the literature, however extends to our potential to construct programs working in the actual world. Via our world community of deployment companions, this identical program has helped display screen tens of 1000’s of sufferers in India, Thailand, Germany and France who would possibly in any other case have been untested for this vision-threatening illness.
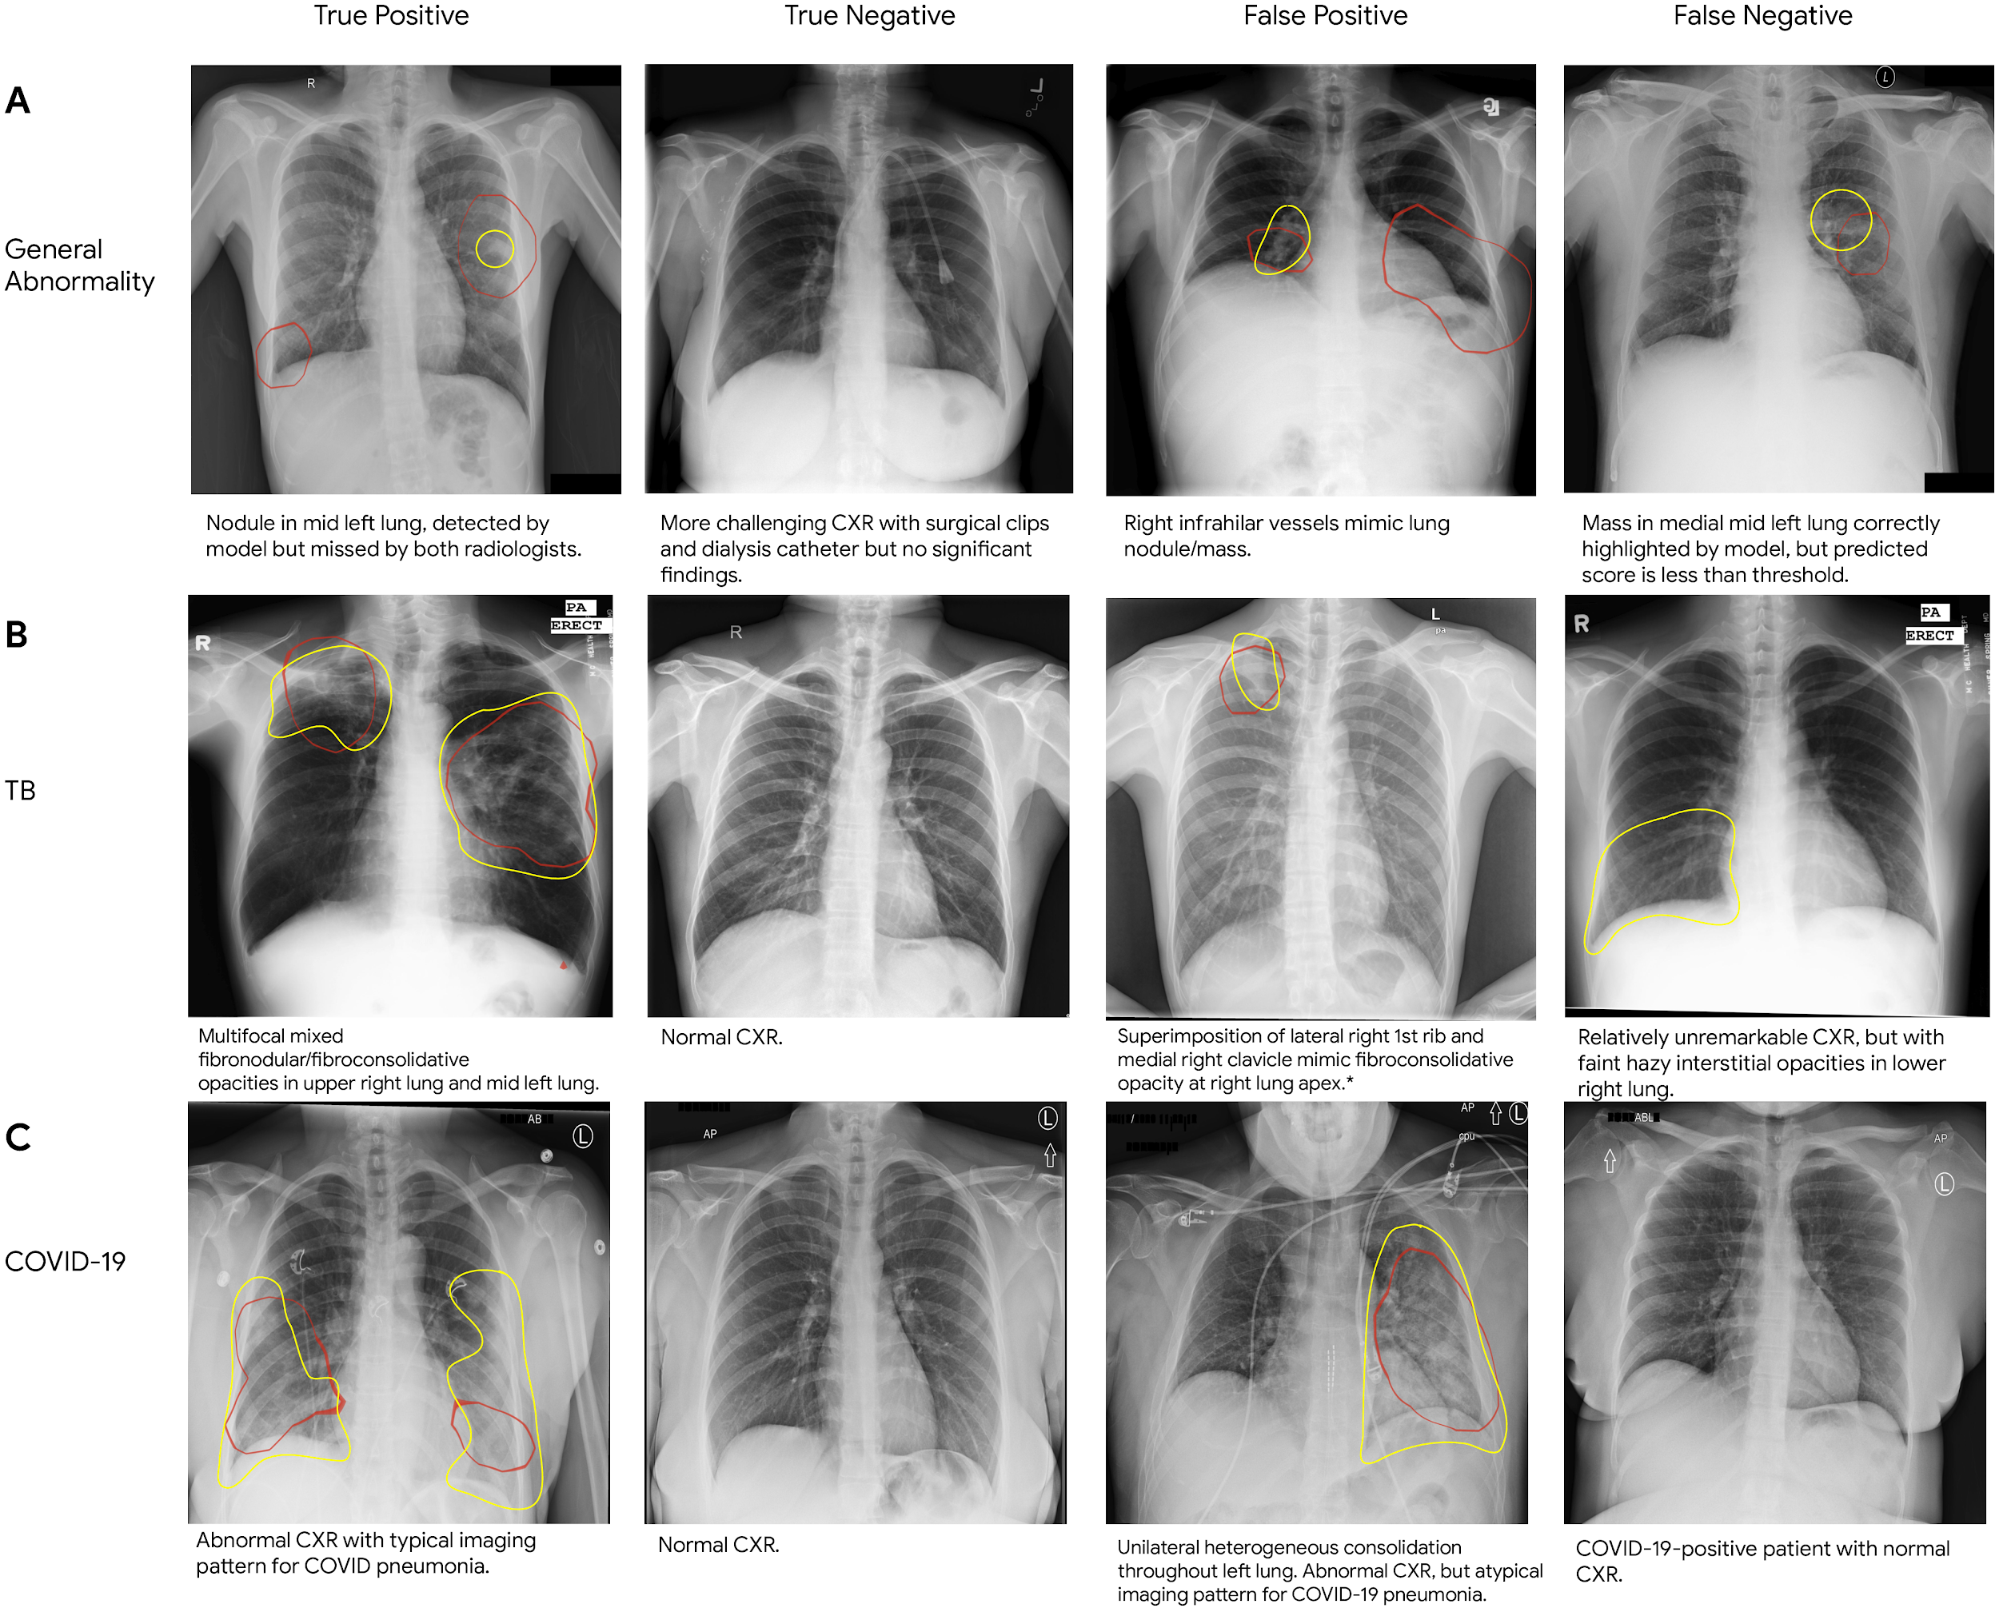
We count on to see this identical sample of assistive ML programs deployed to enhance breast most cancers screening, detect lung most cancers, speed up radiotherapy remedies for most cancers, flag irregular X-rays, and stage prostate most cancers biopsies. Every area presents new alternatives to be useful. ML-assisted colonoscopy procedures are a very attention-grabbing instance of going past the fundamentals. Colonoscopies are usually not simply used to diagnose colon most cancers — the elimination of polyps in the course of the process are the entrance line of halting illness development and stopping critical sickness. On this area we’ve demonstrated that ML can assist guarantee docs don’t miss polyps, might help detect elusive polyps, and may add new dimensions of high quality assurance, like protection mapping via the applying of simultaneous localization and mapping methods. In collaboration with Shaare Zedek Medical Heart in Jerusalem, we’ve proven these programs can work in actual time, detecting a median of 1 polyp per process that might have in any other case been missed, with fewer than 4 false alarms per process.
Pattern chest X-rays (CXR) of true and false positives, and true and false negatives for (A) common abnormalities, (B) tuberculosis, and (C) COVID-19. On every CXR, pink outlines point out areas on which the mannequin centered to determine abnormalities (i.e., the category activation map), and yellow outlines consult with areas of curiosity recognized by a radiologist. One other bold healthcare initiative, Care Studio, makes use of state-of-the-art ML and superior NLP methods to investigate structured information and medical notes, presenting clinicians with essentially the most related info on the proper time — in the end serving to them ship extra proactive and correct care.
As necessary as ML could also be to increasing entry and enhancing accuracy within the scientific setting, we see a brand new equally necessary pattern rising: ML utilized to assist folks of their every day well being and well-being. Our on a regular basis gadgets have highly effective sensors that may assist democratize well being metrics and knowledge so folks could make extra knowledgeable selections about their well being. We’ve already seen launches that allow a smartphone digital camera to evaluate coronary heart charge and respiratory charge to assist customers with out extra {hardware}, and Nest Hub gadgets that assist contactless sleep sensing and permit customers to higher perceive their nighttime wellness. We’ve seen that we will, on the one hand, considerably enhance speech recognition high quality for disordered speech in our personal ASR programs, and on the opposite, use ML to assist recreate the voice of these with speech impairments, empowering them to speak in their very own voice. ML enabled smartphones that assist folks higher analysis rising pores and skin situations or assist these with restricted imaginative and prescient go for a jog, appear to be simply across the nook. These alternatives supply a future too shiny to disregard.
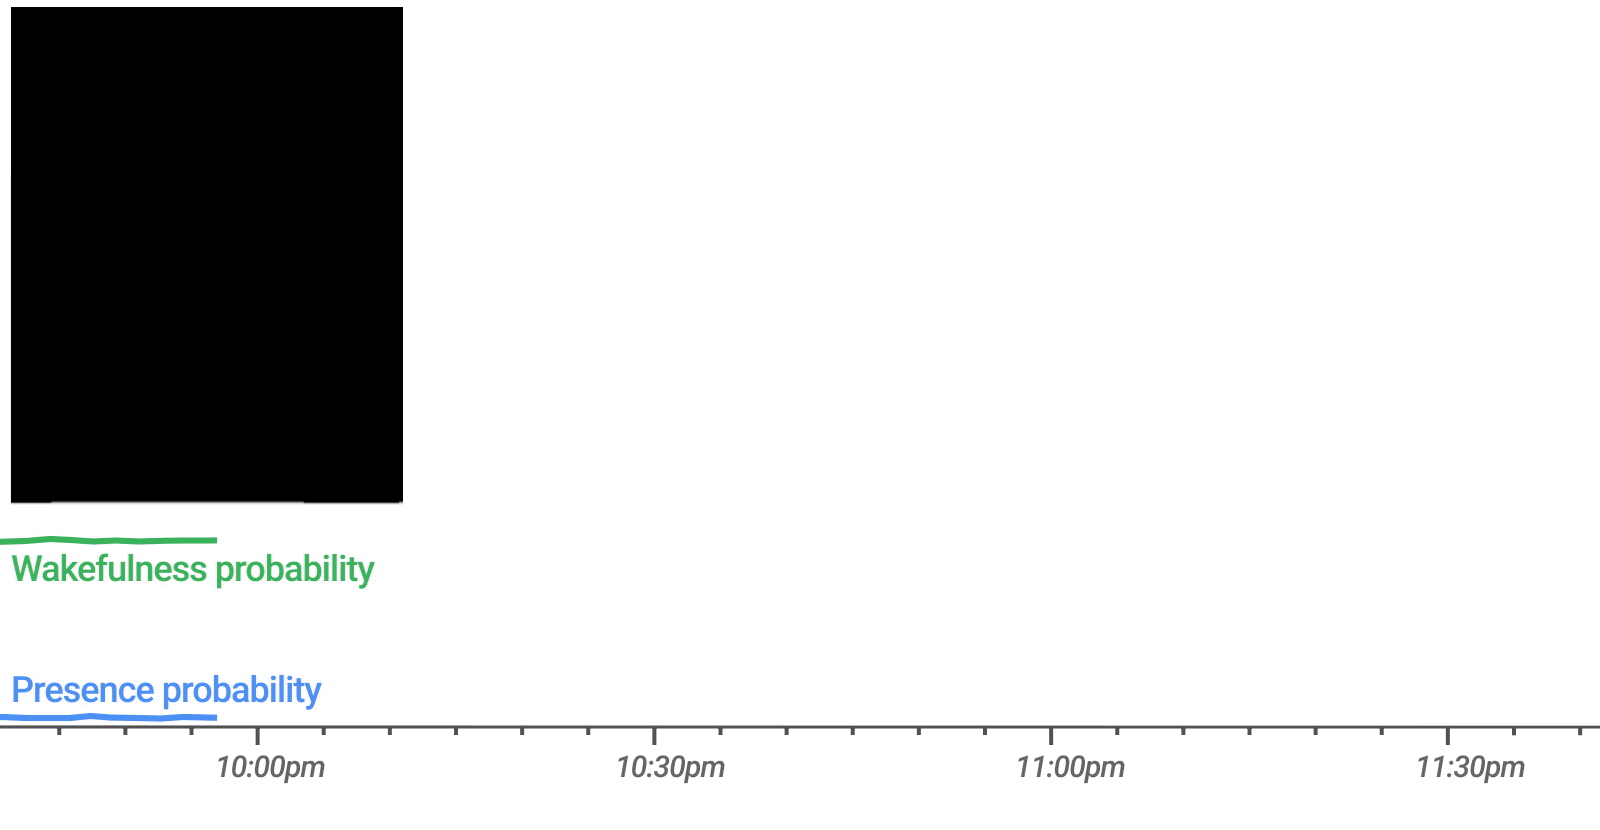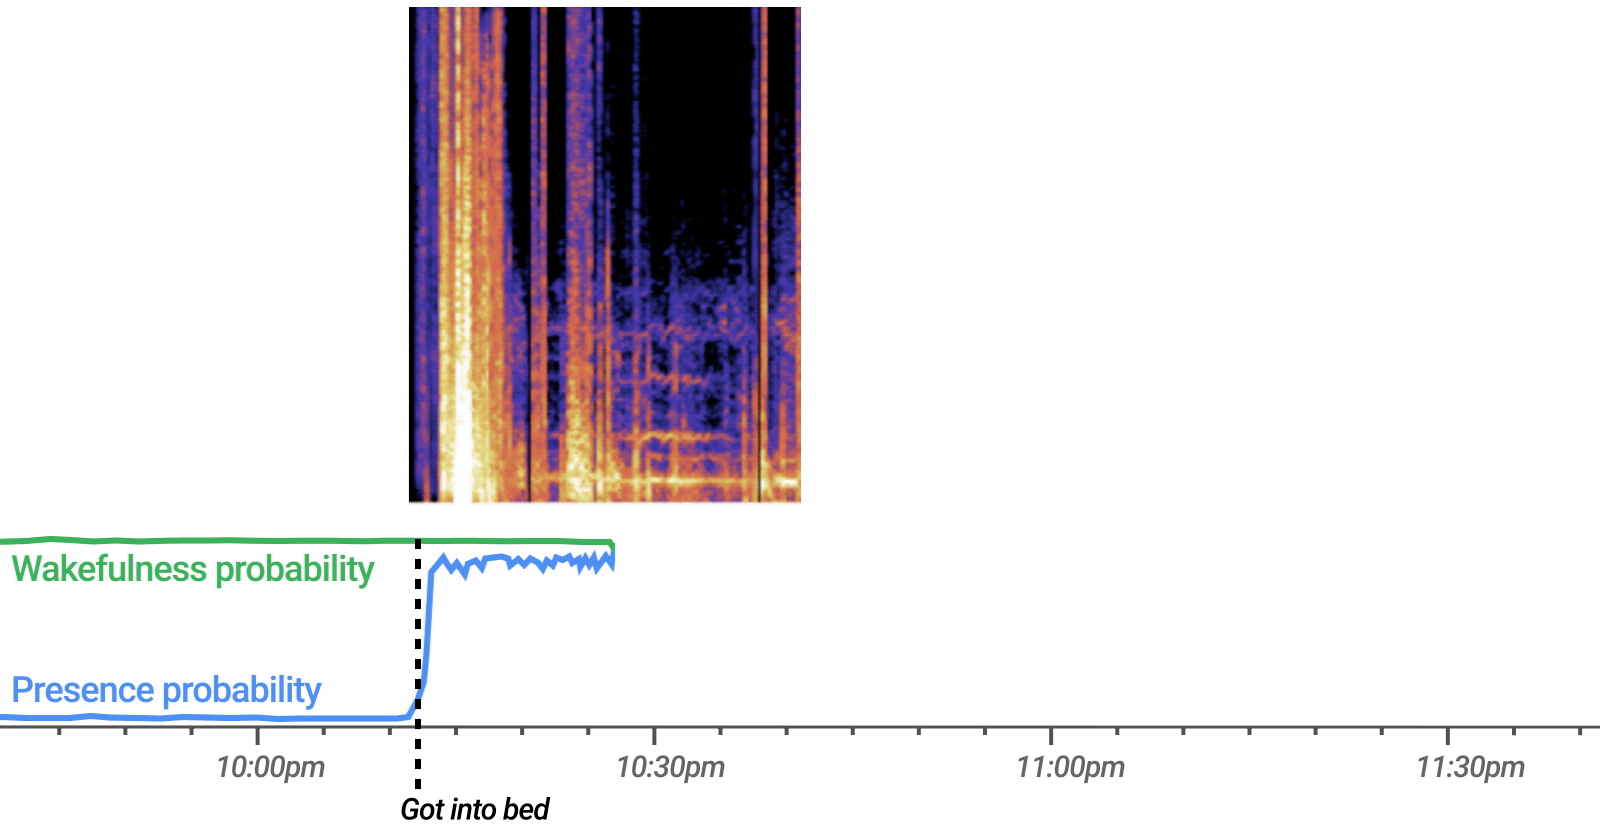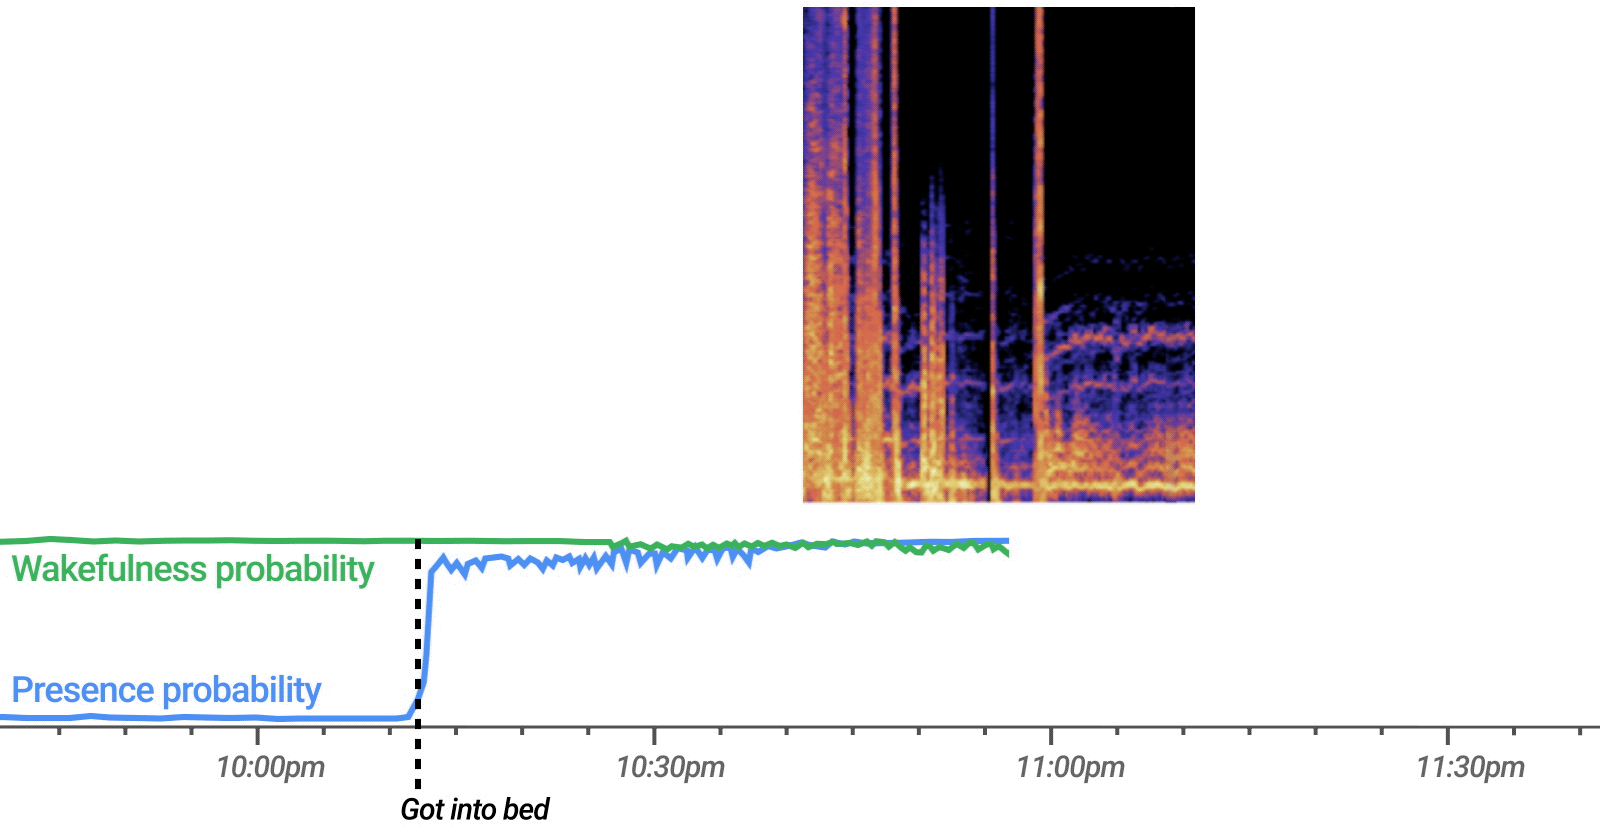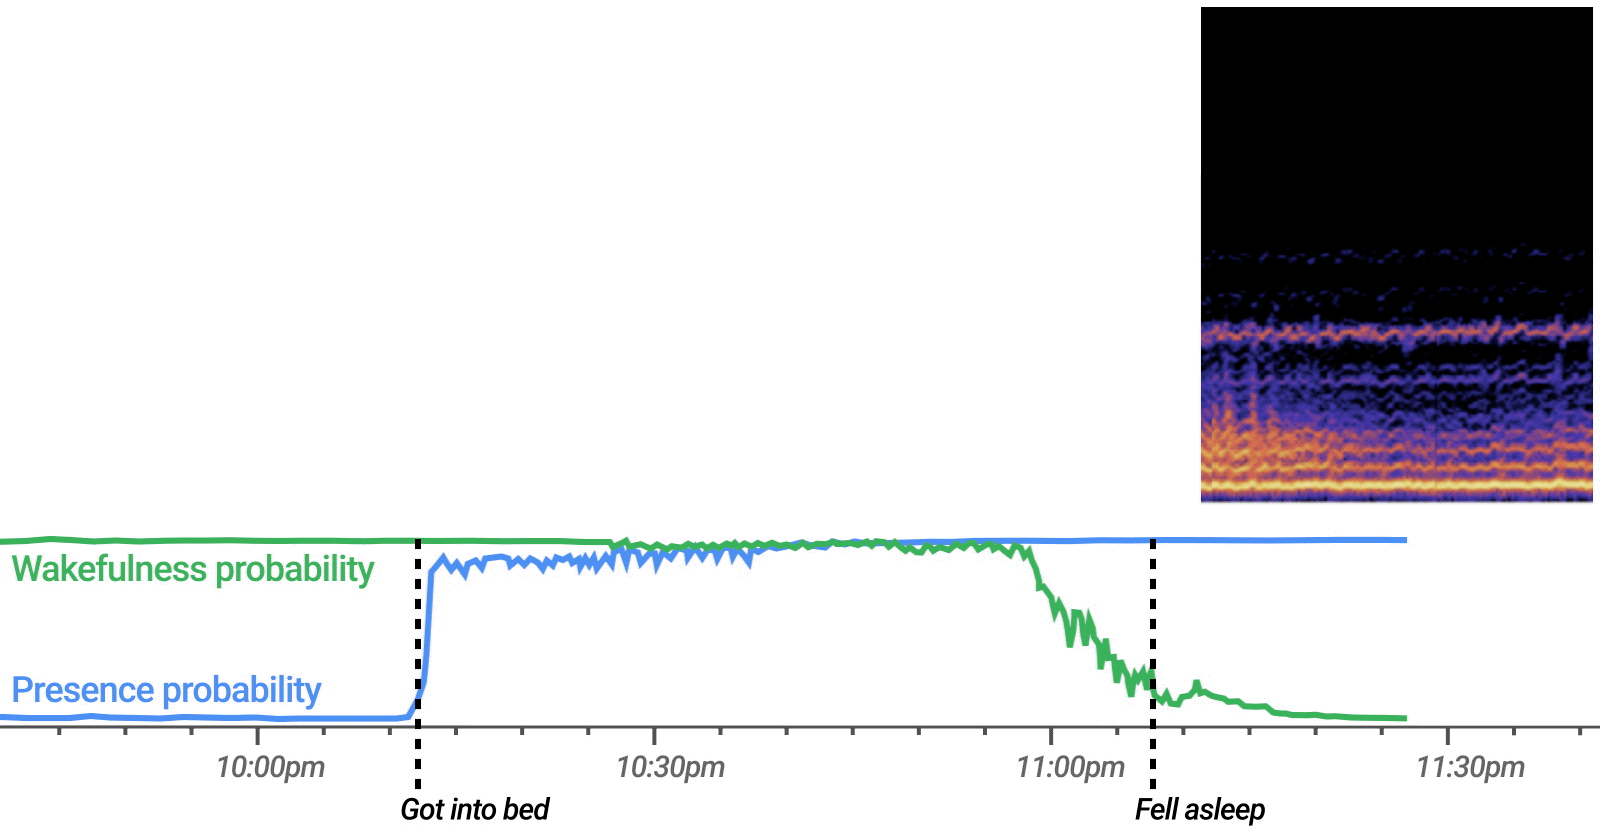
The {custom} ML mannequin for contactless sleep sensing effectively processes a steady stream of 3D radar tensors (summarizing exercise over a spread of distances, frequencies, and time) to mechanically compute chances for the chance of person presence and wakefulness (awake or asleep).
ML Functions for the Local weather Disaster
One other realm of paramount significance is local weather change, which is an extremely pressing risk for humanity. We have to all work collectively to bend the curve of dangerous emissions to make sure a protected and affluent future. Higher details about the local weather affect of various selections might help us deal with this problem in a variety of alternative ways.
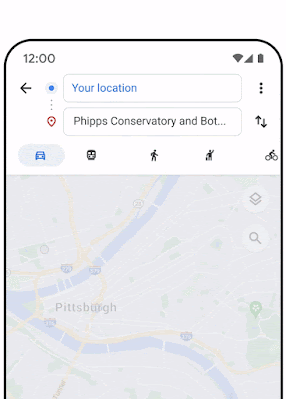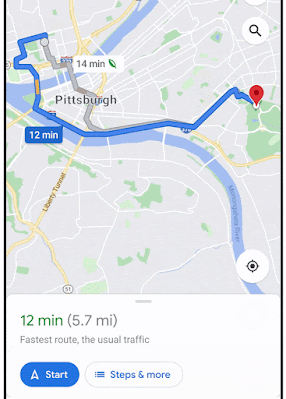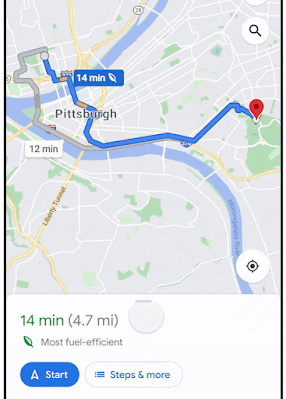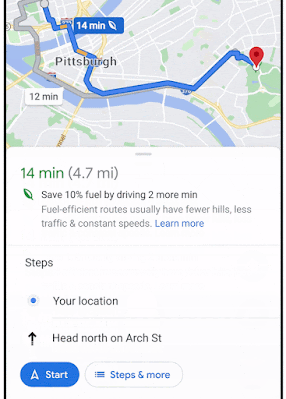
To this finish, we lately rolled out eco-friendly routing in Google Maps, which we estimate will save about 1 million tons of CO2 emissions per 12 months (the equal of eradicating greater than 200,000 vehicles from the highway). A current case research exhibits that utilizing Google Maps instructions in Salt Lake Metropolis ends in each quicker and extra emissions-friendly routing, which saves 1.7% of CO2 emissions and 6.5% journey time. As well as, making our Maps merchandise smarter about electrical autos might help alleviate vary nervousness, encouraging folks to change to emissions-free autos. We’re additionally working with a number of municipalities all over the world to make use of aggregated historic site visitors information to assist counsel improved site visitors mild timing settings, with an early pilot research in Israel and Brazil exhibiting a 10-20% discount in gas consumption and delay time on the examined intersections.
With eco-friendly routing, Google Maps will present you the quickest route and the one which’s most fuel-efficient — so you possibly can select whichever one works finest for you. On an extended time scale, fusion holds promise as a game-changing renewable power supply. In a long-standing collaboration with TAE Applied sciences, we’ve used ML to assist preserve steady plasmas of their fusion reactor by suggesting settings of the greater than 1000 related management parameters. With our collaboration, TAE achieved their main targets for his or her Norman reactor, which brings us a step nearer to the objective of breakeven fusion. The machine maintains a steady plasma at 30 million Kelvin (don’t contact!) for 30 milliseconds, which is the extent of obtainable energy to its programs. They’ve accomplished a design for an much more highly effective machine, which they hope will exhibit the situations needed for breakeven fusion earlier than the top of the last decade.
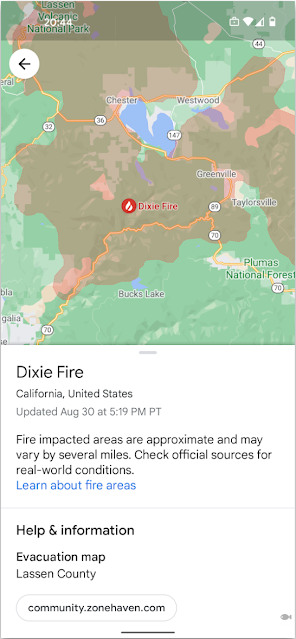
We’re additionally increasing our efforts to handle wildfires and floods, which have gotten extra widespread (like tens of millions of Californians, I’m having to adapt to having a daily “hearth season”). Final 12 months, we launched a wildfire boundary map powered by satellite tv for pc information to assist folks within the U.S. simply perceive the approximate measurement and placement of a hearth — proper from their machine. Constructing on this, we’re now bringing all of Google’s wildfire info collectively and launching it globally with a brand new layer on Google Maps. Now we have been making use of graph optimization algorithms to assist optimize hearth evacuation routes to assist maintain folks protected within the presence of quickly advancing fires. In 2021, our Flood Forecasting Initiative expanded its operational warning programs to cowl 360 million folks, and despatched greater than 115 million notifications on to the cellular gadgets of individuals in danger from flooding, greater than triple our outreach within the earlier 12 months. We additionally deployed our LSTM-based forecast fashions and the brand new Manifold inundation mannequin in real-world programs for the primary time, and shared a detailed description of all elements of our programs.
The wildfire layer in Google Maps offers folks with crucial, up-to-date info in an emergency. We’re additionally working exhausting on our personal set of sustainability initiatives. Google was the primary main firm to develop into carbon impartial in 2007. We had been additionally the primary main firm to match our power use with one hundred pc renewable power in 2017. We function the cleanest world cloud within the trade, and we’re the world’s largest company purchaser of renewable power. Additional, in 2020 we turned the primary main firm to make a dedication to function on 24/7 carbon-free power in all our information facilities and campuses worldwide. That is far tougher than the normal strategy of matching power utilization with renewable power, however we’re working to get this executed by 2030. Carbon emission from ML mannequin coaching is a priority for the ML neighborhood, and we’ve proven that making good selections about mannequin structure, datacenter, and ML accelerator sort can scale back the carbon footprint of coaching by ~100-1000x.
Development 5: Deeper and Broader Understanding of ML
As ML is used extra broadly throughout expertise merchandise and society extra typically, it’s crucial that we proceed to develop new methods to make sure that it’s utilized pretty and equitably, and that it advantages all folks and never simply choose subsets. It is a main focus for our Accountable AI and Human-Centered Know-how analysis group and an space during which we conduct analysis on a wide range of responsibility-related matters.
One space of focus is advice programs which can be based mostly on person exercise in on-line merchandise. As a result of these advice programs are sometimes composed of a number of distinct elements, understanding their equity properties typically requires perception into particular person elements in addition to how the person elements behave when mixed collectively. Current work has helped to higher perceive these relationships, revealing methods to enhance the equity of each particular person elements and the general advice system. As well as, when studying from implicit person exercise, it’s also necessary for advice programs to study in an unbiased method, because the easy strategy of studying from objects that had been proven to earlier customers reveals well-known types of bias. With out correcting for such biases, for instance, objects that had been proven in additional outstanding positions to customers are likely to get advisable to future customers extra typically.
As in advice programs, surrounding context is necessary in machine translation. As a result of most machine translation programs translate particular person sentences in isolation, with out extra surrounding context, they will typically reinforce biases associated to gender, age or different areas. In an effort to handle a few of these points, we’ve a long-standing line of analysis on decreasing gender bias in our translation programs, and to assist your entire translation neighborhood, final 12 months we launched a dataset to check gender bias in translation based mostly on translations of Wikipedia biographies.
One other widespread drawback in deploying machine studying fashions is distributional shift: if the statistical distribution of knowledge on which the mannequin was skilled just isn’t the identical as that of the info the mannequin is given as enter, the mannequin’s habits can generally be unpredictable. In current work, we make use of the Deep Bootstrap framework to match the actual world, the place there may be finite coaching information, to an “superb world”, the place there may be infinite information. Higher understanding of how a mannequin behaves in these two regimes (actual vs. superb) might help us develop fashions that generalize higher to new settings and exhibit much less bias in direction of fastened coaching datasets.
Though work on ML algorithms and mannequin growth will get vital consideration, information assortment and dataset curation typically will get much less. However this is a crucial space, as a result of the info on which an ML mannequin is skilled could be a potential supply of bias and equity points in downstream functions. Analyzing such information cascades in ML might help determine the various locations within the lifecycle of an ML challenge that may have substantial affect on the outcomes. This analysis on information cascades has led to evidence-backed tips for information assortment and analysis within the revised PAIR Guidebook, geared toward ML builders and designers.
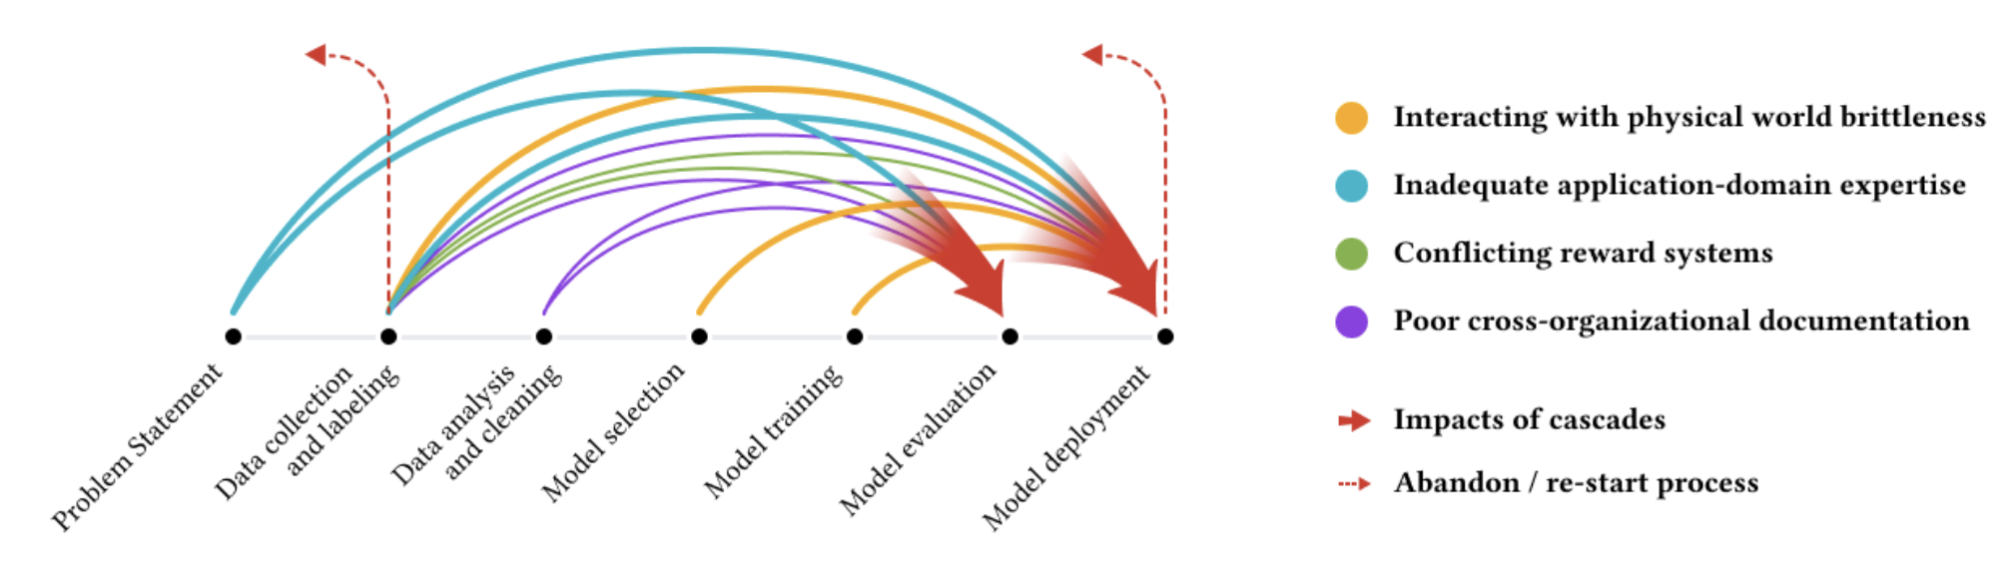 |
| Arrows of various coloration point out varied varieties of information cascades, every of which usually originate upstream, compound over the ML growth course of, and manifest downstream. |
The final objective of higher understanding information is a crucial a part of ML analysis. One factor that may assistance is discovering and investigating anomalous information. Now we have developed strategies to higher perceive the affect that individual coaching examples can have on an ML mannequin, since mislabeled information or different comparable points can have outsized affect on the general mannequin habits. Now we have additionally constructed the Know Your Information device to assist ML researchers and practitioners higher perceive properties of their datasets, and final 12 months we created a case research of the right way to use the Know Your Information device to discover points like gender bias and age bias in a dataset.
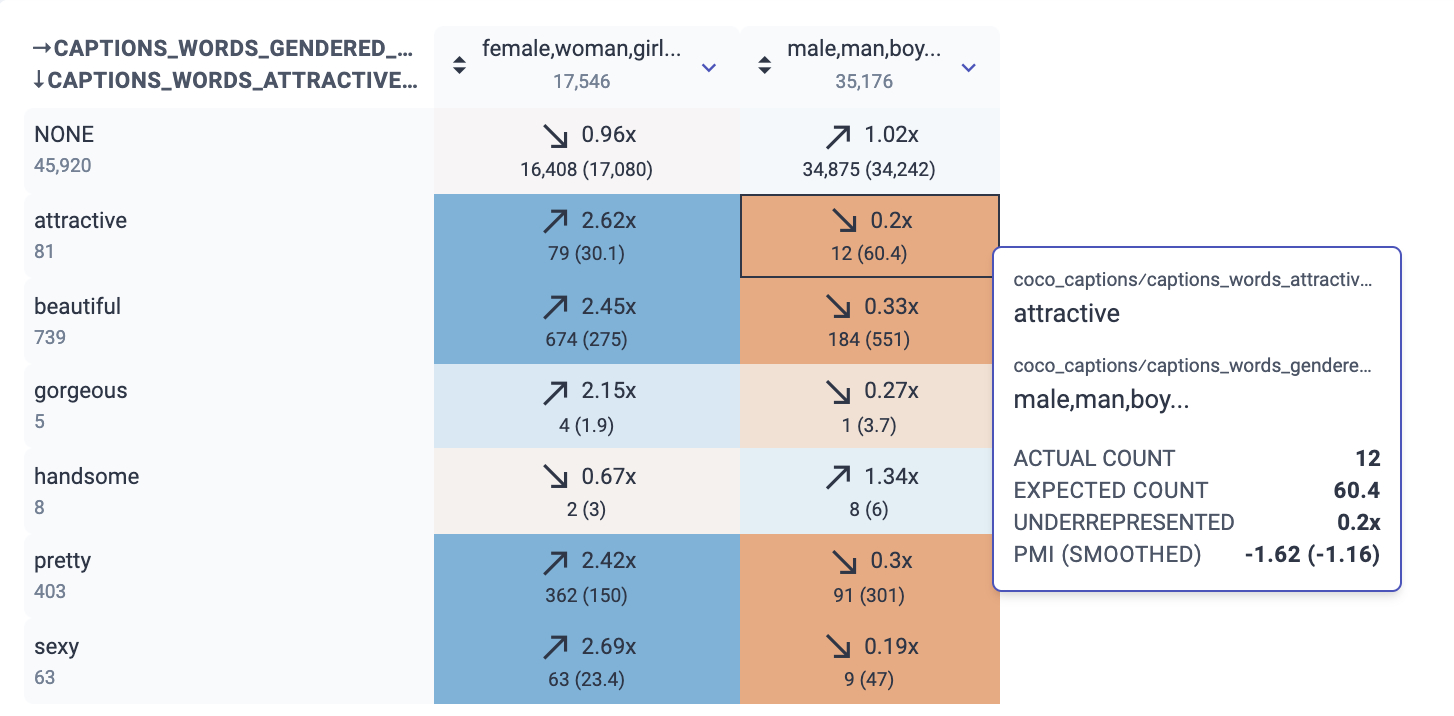 |
| A screenshot from Know Your Information exhibiting the connection between phrases that describe attractiveness and gendered phrases. For instance, “engaging” and “male/man/boy” co-occur 12 occasions, however we count on ~60 occasions by likelihood (the ratio is 0.2x). Then again, “engaging” and “feminine/girl/lady” co-occur 2.62 occasions greater than likelihood. |
Understanding dynamics of benchmark dataset utilization can be necessary, given the central function they play within the group of ML as a subject. Though research of particular person datasets have develop into more and more widespread, the dynamics of dataset utilization throughout the sphere have remained underexplored. In current work, we revealed the primary massive scale empirical evaluation of dynamics of dataset creation, adoption, and reuse. This work presents insights into pathways to allow extra rigorous evaluations, in addition to extra equitable and socially knowledgeable analysis.
Creating public datasets which can be extra inclusive and fewer biased is a crucial manner to assist enhance the sphere of ML for everybody. In 2016, we launched the Open Pictures dataset, a group of ~9 million photographs annotated with picture labels spanning 1000’s of object classes and bounding field annotations for 600 lessons. Final 12 months, we launched the Extra Inclusive Annotations for Folks (MIAP) dataset within the Open Pictures Prolonged assortment. The gathering accommodates extra full bounding field annotations for the individual class hierarchy, and every annotation is labeled with fairness-related attributes, together with perceived gender presentation and perceived age vary. With the rising give attention to decreasing unfair bias as a part of accountable AI analysis, we hope these annotations will encourage researchers already leveraging the Open Pictures dataset to include equity evaluation of their analysis.
As a result of we additionally know that our groups are usually not the one ones creating datasets that may enhance machine studying, we’ve constructed Dataset Search to assist customers uncover new and helpful datasets, wherever they is perhaps on the Net.
Tackling varied types of abusive habits on-line, comparable to poisonous language, hate speech, and misinformation, is a core precedence for Google. Having the ability to detect such types of abuse reliably, effectively, and at scale is of crucial significance each to make sure that our platforms are protected and likewise to keep away from the danger of reproducing such unfavourable traits via language applied sciences that study from on-line discourse in an unsupervised vogue. Google has pioneered work on this area via the Perspective API device, however the nuances concerned in detecting toxicity at scale stays a posh drawback. In current work, in collaboration with varied tutorial companions, we launched a complete taxonomy to cause about the altering panorama of on-line hate and harassment. We additionally investigated the right way to detect covert types of toxicity, comparable to microaggressions, which can be typically ignored in on-line abuse interventions, studied how standard approaches to take care of disagreements in information annotations of such subjective ideas would possibly marginalize minority views, and proposed a brand new disaggregated modeling strategy that makes use of a multi-task framework to deal with this subject. Moreover, via qualitative analysis and network-level content material evaluation, Google’s Jigsaw group, in collaboration with researchers at George Washington College, studied how hate clusters unfold disinformation throughout social media platforms.
One other potential concern is that ML language understanding and technology fashions can generally additionally produce outcomes that aren’t correctly supported by proof. To confront this drawback in query answering, summarization, and dialog, we developed a brand new framework for measuring whether or not outcomes might be attributed to particular sources. We launched annotation tips and demonstrated that they are often reliably utilized in evaluating candidate fashions.
Interactive evaluation and debugging of fashions stays key to accountable use of ML. Now we have up to date our Language Interpretability Device with new capabilities and methods to advance this line of labor, together with assist for picture and tabular information, a wide range of options carried over from our earlier work on the What-If Device, and built-in assist for equity evaluation via the strategy of Testing with Idea Activation Vectors. Interpretability and explainability of ML programs extra typically can be a key a part of our Accountable AI imaginative and prescient; in collaboration with DeepMind, we made headway in understanding the acquisition of human chess ideas within the self-trained AlphaZero chess system.
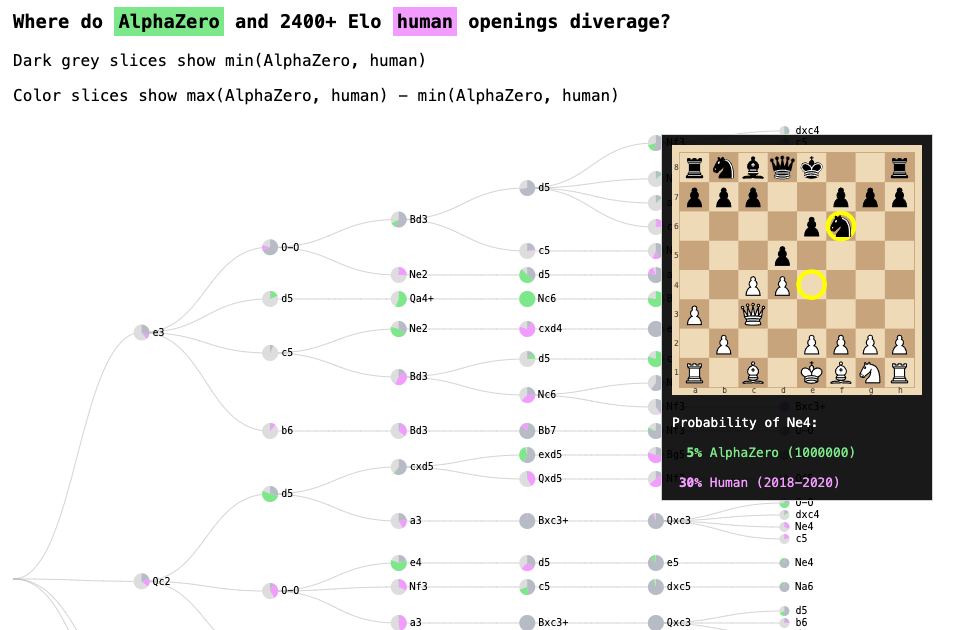 |
| Discover what AlphaZero might need discovered about taking part in chess utilizing this on-line device. |
We’re additionally working exhausting to broaden the angle of Accountable AI past western contexts. Our current analysis examines how varied assumptions of standard algorithmic equity frameworks based mostly on Western establishments and infrastructures might fail in non-Western contexts and presents a pathway for recontextualizing equity analysis in India alongside a number of instructions. We’re actively conducting survey analysis throughout a number of continents to higher perceive perceptions of and preferences concerning AI. Western framing of algorithmic equity analysis tends to give attention to solely a handful of attributes, thus biases regarding non-Western contexts are largely ignored and empirically under-studied. To deal with this hole, in collaboration with the College of Michigan, we developed a weakly supervised technique to robustly detect lexical biases in broader geo-cultural contexts in NLP fashions that replicate human judgments of offensive and inoffensive language in these geographic contexts.
Moreover, we’ve explored functions of ML to contexts valued within the International South, together with growing a proposal for farmer-centered ML analysis. Via this work, we hope to encourage the sphere to be considerate about the right way to deliver ML-enabled options to smallholder farmers in methods that may enhance their lives and their communities.
Involving neighborhood stakeholders in any respect phases of the ML pipeline is vital to our efforts to develop and deploy ML responsibly and maintain us centered on tackling the issues that matter most. On this vein, we held a Well being Fairness Analysis Summit amongst exterior college, non-profit group leads, authorities and NGO representatives, and different material specialists to debate the right way to deliver extra fairness into your entire ML ecosystem, from the way in which we strategy problem-solving to how we assess the affect of our efforts.
Neighborhood-based analysis strategies have additionally knowledgeable our strategy to designing for digital wellbeing and addressing racial fairness points in ML programs, together with enhancing our understanding of the expertise of Black Individuals utilizing ASR programs. We’re additionally listening to the general public extra broadly to learn the way sociotechnical ML programs might assist throughout main life occasions, comparable to by supporting household caregiving.
As ML fashions develop into extra succesful and have affect in lots of domains, the safety of the personal info utilized in ML continues to be an necessary focus for analysis. Alongside these traces, a few of our current work addresses privateness in massive fashions, each highlighting that coaching information can generally be extracted from massive fashions and pointing to how privateness might be achieved in massive fashions, e.g., as in differentially personal BERT. Along with the work on federated studying and analytics, talked about above, we’ve additionally been enhancing our toolbox with different principled and sensible ML methods for guaranteeing differential privateness, for instance personal clustering, personal personalization, personal matrix completion, personal weighted sampling, personal quantiles, personal strong studying of halfspaces, and basically, sample-efficient personal PAC studying. Furthermore, we’ve been increasing the set of privateness notions that may be tailor-made to completely different functions and risk fashions, together with label privateness and person versus merchandise degree privateness.
Datasets
Recognizing the worth of open datasets to the final development of ML and associated fields of analysis, we proceed to develop our assortment of open supply datasets and assets and develop our world index of open datasets in Google Dataset Search. This 12 months, we’ve launched a lot of datasets and instruments throughout a spread of analysis areas:
| Datasets & Instruments | Description |
| AIST++ | 3D keypoints with corresponding photographs for dance motions masking 10 dance genres |
| AutoFlow | 40k picture pairs with floor fact optical circulation |
| C4_200M | A 200 million sentence artificial dataset for grammatical error correction |
| CIFAR-5M | Dataset of ~6 million artificial CIFAR-10–like photographs (RGB 32 x 32 pix) |
| Crisscrossed Captions | Set of semantic similarity rankings for the MS-COCO dataset |
| Disfl-QA | Dataset of contextual disfluencies for info looking for |
| Distilled Datasets | Distilled datasets from CIFAR-10, CIFAR-100, MNIST, Style-MNIST, and SVHN |
| EvolvingRL | 1000 high performing RL algorithms found via algorithm evolution |
| GoEmotions | A human-annotated dataset of 58k Reddit feedback labeled with 27 emotion classes |
| H01 Dataset | 1.4 petabyte browsable reconstruction of the human cortex |
| Know Your Information | Device for understanding biases in a dataset |
| Lens Flare | 5000 high-quality RGB photographs of typical lens flare |
| Extra Inclusive Annotations for Folks (MIAP) | Improved bounding field annotations for a subset of the individual class within the Open Pictures dataset |
| Principally Primary Python Issues | 1000 Python programming issues, incl. job description, code answer & check instances |
| NIH ChestX-ray14 dataset labels | Knowledgeable labels for a subset of the NIH ChestX-ray14 dataset |
| Open Buildings | Places and footprints of 516 million buildings with protection throughout most of Africa |
| Optical Polarization from Curie | 5GB of optical polarization information from the Curie submarine cable |
| Readability Scroll | Scroll interactions of ~600 individuals studying texts from the OneStopEnglish corpus |
| RLDS | Instruments to retailer, retrieve & manipulate episodic information for reinforcement studying |
| Room-Throughout-Room (RxR) | Multilingual dataset for vision-and-language navigation in English, Hindi and Telugu |
| Mushy Attributes | ~6k units of film titles annotated with single English tender attributes |
| TimeDial | Dataset of a number of selection span-filling duties for temporal commonsense reasoning in dialog |
| ToTTo | English table-to-text technology dataset with a managed textual content technology job |
| Translated Wikipedia Biographies | Dataset for evaluation of widespread gender errors in NMT for English, Spanish and German |
| UI Understanding Information for UIBert | Datasets for 2 UI understanding duties, AppSim & RefExp |
| WikiFact | Wikipedia & WikiData–based mostly dataset to coach relationship classifiers and reality extraction fashions |
| WIT | Wikipedia-based Picture Textual content dataset for multimodal multilingual ML |
Analysis Neighborhood Interplay
To comprehend our objective for a extra strong and complete understanding of ML and associated applied sciences, we actively have interaction with the broader analysis neighborhood. In 2021, we revealed over 750 papers, almost 600 of which had been offered at main analysis conferences. Google Analysis sponsored over 150 conferences, and Google researchers contributed instantly by serving on program committees and organizing workshops, tutorials and quite a few different actions geared toward collectively advancing the sphere. To study extra about our contributions to a few of the bigger analysis conferences this 12 months, please see our current convention weblog posts. As well as, we hosted 19 digital workshops (just like the 2021 Quantum Summer season Symposium), which allowed us to additional have interaction with the educational neighborhood by producing new concepts and instructions for the analysis subject and advancing analysis initiatives.
In 2021, Google Analysis additionally instantly supported exterior analysis with $59M in funding, together with $23M via Analysis packages to college and college students, and $20M in college partnerships and outreach. This previous 12 months, we launched new funding and collaboration packages that assist teachers all around the world who’re doing excessive affect analysis. We funded 86 early profession college via our Analysis Scholar Program to assist common developments in science, and funded 34 college via our Award for Inclusion Analysis Program who’re doing analysis in areas like accessibility, algorithmic equity, greater schooling and collaboration, and participatory ML. Along with the analysis we’re funding, we welcomed 85 college and post-docs, globally, via our Visiting Researcher program, to return to Google and accomplice with us on thrilling concepts and shared analysis challenges. We additionally chosen a bunch of 74 extremely proficient PhD pupil researchers to obtain Google PhD Fellowships and mentorship as they conduct their analysis.
As a part of our ongoing racial fairness commitments, making pc science (CS) analysis extra inclusive continues to be a high precedence for us. In 2021, we continued increasing our efforts to extend the variety of Ph.D. graduates in computing. For instance, the CS Analysis Mentorship Program (CSRMP), an initiative by Google Analysis to assist college students from traditionally marginalized teams (HMGs) in computing analysis pathways, graduated 590 mentees, 83% of whom self-identified as a part of an HMG, who had been supported by 194 Google mentors — our largest group up to now! In October, we welcomed 35 establishments globally main the way in which to interact 3,400+ college students in computing analysis as a part of the 2021 exploreCSR cohort. Since 2018, this program has supplied college with funding, neighborhood, analysis and connections to Google researchers as a way to introduce college students from HMGs to the world of CS analysis. We’re excited to develop this program to extra worldwide places in 2022.
We additionally continued our efforts to fund and accomplice with organizations to develop and assist new pathways and approaches to broadening participation in computing analysis at scale. From working with alliances just like the Computing Alliance of Hispanic-Serving Establishments (CAHSI) and CMD-IT Diversifying LEAdership within the Professoriate (LEAP) Alliance to partnering with college initiatives like UMBC’s Meyerhoff Students, Cornell College’s CSMore, Northeastern College’s Heart for Inclusive Computing, and MIT’s MEnTorEd Alternatives in Analysis (METEOR), we’re taking a community-based strategy to materially improve the illustration of marginalized teams in computing analysis.
Different Work
In writing these retrospectives, I attempt to give attention to new analysis work that has occurred (largely) previously 12 months whereas additionally trying forward. In previous years’ retrospectives, I’ve tried to be extra complete, however this time I believed it could possibly be extra attention-grabbing to give attention to just some themes. We’ve additionally executed nice work in lots of different analysis areas that don’t match neatly into these themes. Should you’re , I encourage you to take a look at our analysis publications by space beneath or by 12 months (and in the event you’re all in favour of quantum computing, our Quantum group lately wrote a retrospective of their work in 2021):
Conclusion
Analysis is usually a multi-year journey to real-world affect. Early stage analysis work that occurred just a few years in the past is now having a dramatic affect on Google’s merchandise and the world over. Investments in ML {hardware} accelerators like TPUs and in software program frameworks like TensorFlow and JAX have borne fruit. ML fashions are more and more prevalent in many various merchandise and options at Google as a result of their energy and ease of expression streamline experimentation and productionization of ML fashions in performance-critical environments. Analysis into mannequin architectures to create Seq2Seq, Inception, EfficientNet, and Transformer or algorithmic analysis like batch normalization and distillation is driving progress within the fields of language understanding, imaginative and prescient, speech, and others. Primary capabilities like higher language and visible understanding and speech recognition might be transformational, and consequently, these kinds of fashions are extensively deployed for all kinds of issues in a lot of our merchandise together with Search, Assistant, Advertisements, Cloud, Gmail, Maps, YouTube, Workspace, Android, Pixel, Nest, and Translate.
These are actually thrilling occasions in machine studying and pc science. Continued enchancment in computer systems’ potential to know and work together with the world round them via language, imaginative and prescient, and sound opens up whole new frontiers of how computer systems might help folks accomplish issues on this planet. The numerous examples of progress alongside the 5 themes outlined on this submit are waypoints in a long-term journey!
Acknowledgements
Due to Alison Carroll, Alison Lentz, Andrew Carroll, Andrew Tomkins, Avinatan Hassidim, Azalia Mirhoseini, Barak Turovsky, Been Kim, Blaise Aguera y Arcas, Brennan Saeta, Brian Rakowski, Charina Chou, Christian Howard, Claire Cui, Corinna Cortes, Courtney Heldreth, David Patterson, Dipanjan Das, Ed Chi, Eli Collins, Emily Denton, Fernando Pereira, Genevieve Park, Greg Corrado, Ian Tenney, Iz Conroy, James Wexler, Jason Freidenfelds, John Platt, Katherine Chou, Kathy Meier-Hellstern, Kyle Vandenberg, Lauren Wilcox, Lizzie Dorfman, Marian Croak, Martin Abadi, Matthew Flegal, Meredith Morris, Natasha Noy, Negar Saei, Neha Arora, Paul Muret, Paul Natsev, Quoc Le, Ravi Kumar, Rina Panigrahy, Sanjiv Kumar, Sella Nevo, Slav Petrov, Sreenivas Gollapudi, Tom Duerig, Tom Small, Vidhya Navalpakkam, Vincent Vanhoucke, Vinodkumar Prabhakaran, Viren Jain, Yonghui Wu, Yossi Matias, and Zoubin Ghahramani for useful suggestions and contributions to this submit, and to your entire Analysis and Well being communities at Google for everybody’s contributions in direction of this work.
[ad_2]


