



[ad_1]
Earlier this week, footage was launched displaying a Tesla autopilot system crashing instantly into the aspect of a stalled car on a motorway in June of 2021. The truth that the automotive was darkish and tough to discern has prompted dialogue on the constraints of counting on pc imaginative and prescient in autonomous driving situations.
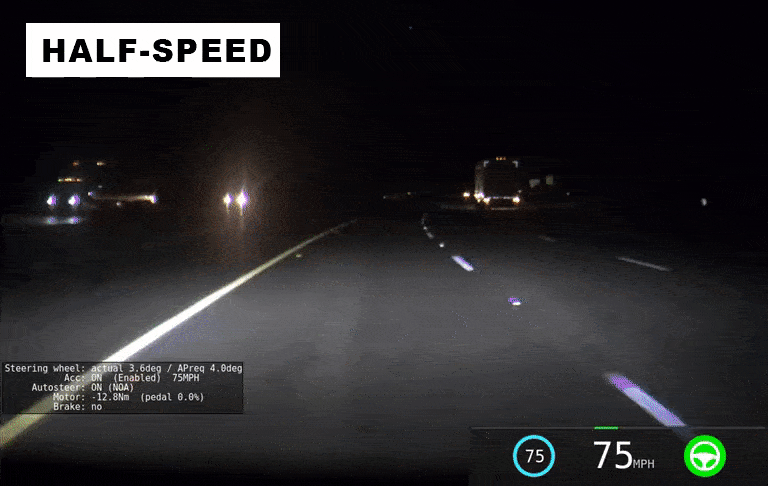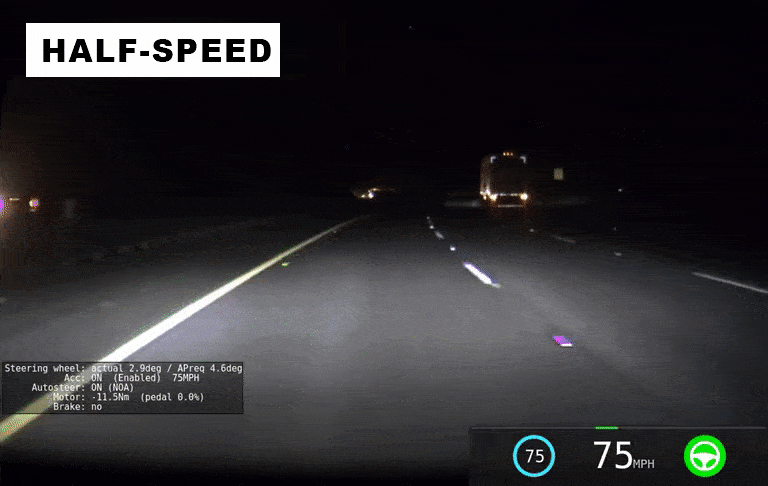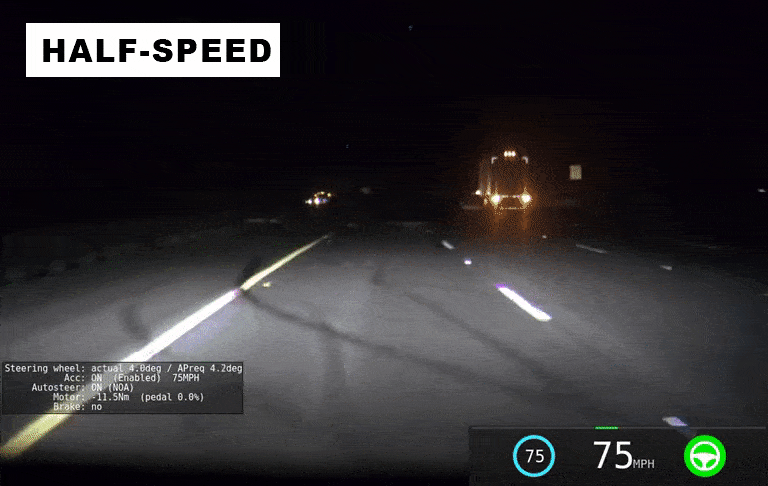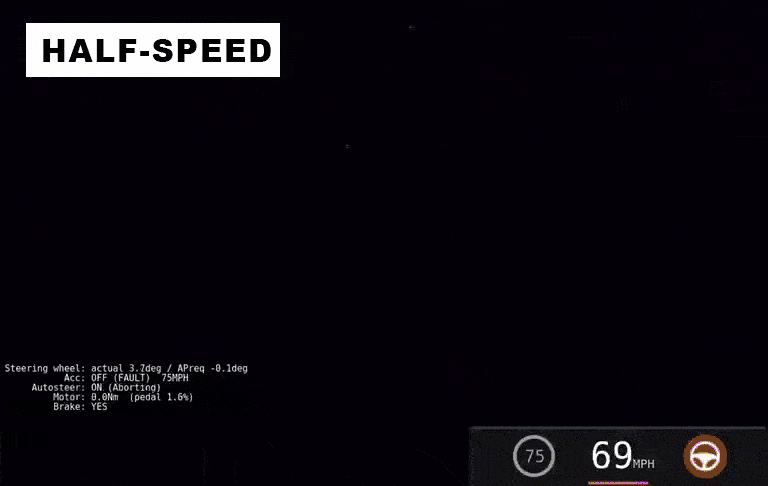
Footage launched in December 2021 depicts the second of influence. Supply: https://twitter.com/greentheonly/standing/1473307236952940548
Although video compression within the widely-shared footage provides a barely exaggerated impression of how rapidly the immobilized truck ‘snuck up’ on the driving force on this case, a higher-quality video of the identical occasion demonstrates {that a} fully-alert driver would even have struggled to reply with something however a tardy swerve or semi-effective braking.
The footage provides to the controversy round Tesla’s choice to take away radar sensors for Autopilot, introduced in Might 2021, and its stance on favoring vision-based techniques over different echo-location applied sciences such, as LiDAR.
By coincidence, a brand new analysis paper from Israel this week provides an method to straddle the LiDAR and pc imaginative and prescient domains, by changing LiDAR level clouds to photo-real imagery with using a Generative Adversarial Community (GAN).

Within the new undertaking from Israel, Black automobiles recognized in LiDAR footage are transformed to a ‘daylight’ state of affairs for pc vision-based analyses, much like the tack that Tesla is pursuing for the event of its Autopilot system. Supply: https://arxiv.org/pdf/2112.11245.pdf
The authors state:
‘Our fashions discovered tips on how to predict realistically wanting photographs from simply level cloud information, even photographs with black automobiles.
‘Black automobiles are tough to detect instantly from level clouds due to their low degree of reflectivity. This method may be used sooner or later to carry out visible object recognition on photo-realistic photographs generated from LiDAR level clouds.’
Photograph-Actual, LiDAR-Based mostly Picture Streams
The new paper is titled Producing Photograph-realistic Photographs from LiDAR Level Clouds with Generative Adversarial Networks, and comes from seven researchers at three Israeli educational schools, along with six researchers from Israel-based Innoviz Applied sciences.
The researchers got down to uncover if GAN-based artificial imagery may very well be produced at an acceptable fee from the purpose clouds generated by LiDAR techniques, in order that the following stream of photographs may very well be utilized in object recognition and semantic segmentation workflows.
Information
The central thought, as in so many novel [x]>[x] picture transliteration initiatives, is to coach an algorithm on paired information, the place LiDAR level cloud photographs (which depend on device-emitted mild) are skilled towards an identical body from a front-facing digicam.
Because the footage was taken within the daytime, the place a pc imaginative and prescient system can extra simply individuate an otherwise-elusive all-black car (such because the one which the Tesla crashed into in June), this coaching ought to present a central floor reality that’s extra immune to darkish situations.
The info was gathered with an InnovizOne LiDAR sensor, which provides a 10fps or 15fps seize fee, relying on mannequin.
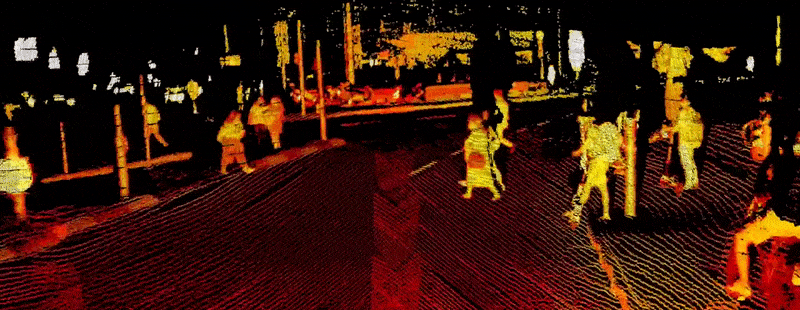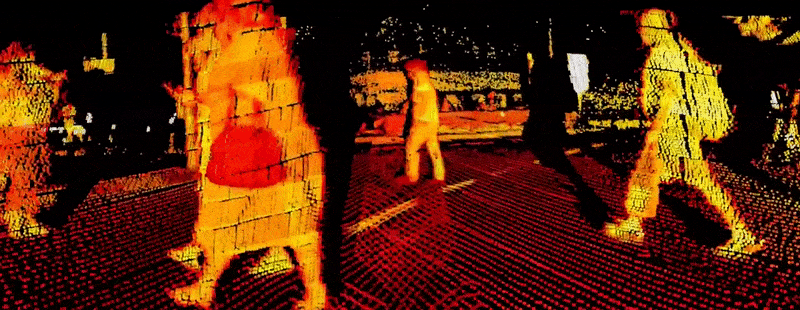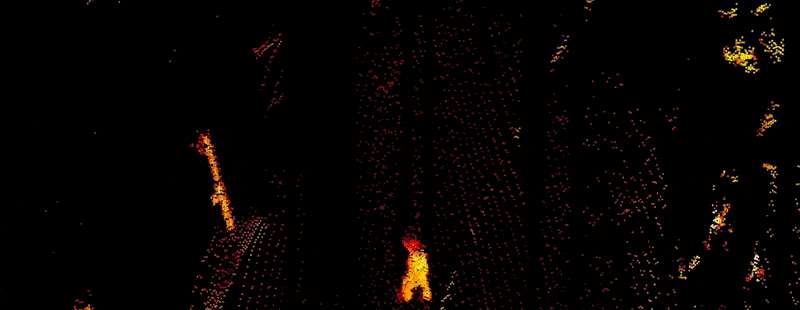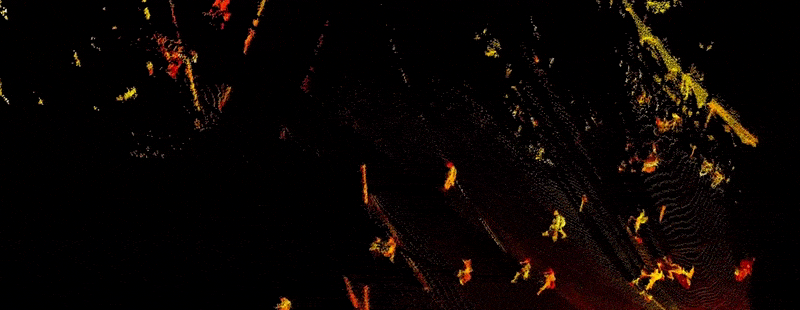
LiDAR information captured by an Innoviz gadget. Supply: https://www.youtube.com/watch?v=wmcaf_VpsQI
The ensuing dataset contained round 30,000 photographs and 200,000 collected 3D factors. The researchers carried out two exams: one wherein the purpose cloud information carried solely reflectivity info; and a second, wherein the purpose cloud information had two channels, one every for reflectivity and distance.
For the primary experiment, the GAN was skilled to 50 epochs, past which overfitting was seen to be a problem.

GAN-created photographs from the primary experiment. On the left, level cloud information; within the center, precise frames from captured footage, used as floor reality; proper, the artificial representations created by the Generative Adversarial Community.
The authors remark:
‘The take a look at set is a very new recording that the GANs have by no means seen earlier than the take a look at. This was predicted utilizing solely reflectivity info from the purpose cloud.
‘We chosen to indicate frames with black automobiles as a result of black automobiles are often tough to detect from LiDAR. We are able to see that the generator discovered to generate black automobiles, in all probability from contextual info, due to the truth that the colours and the precise shapes of objects in predicted photographs usually are not similar as in the true photographs.’
For the second experiment, the authors skilled the GAN to 40 epochs at a batch measurement of 1, leading to the same presentation of ‘consultant’ black automobiles obtained largely from context. This configuration was additionally used to generate a video that reveals the GAN-generated footage (pictured higher, within the pattern picture beneath) along with the bottom reality footage.

Analysis
The customary technique of analysis and comparability to present state-of-the-art was not potential with this undertaking, as a result of its distinctive nature. As an alternative the researchers devised a customized metric relating to the extent to which automobiles (minor and fleeting elements of the supply footage) are represented within the output footage.
They chose 100 pairs of LiDAR/Generated photographs from every set and successfully divided the variety of automotive photographs current within the supply footage to the quantity current within the artificial information produced, producing a metric scale of 0 to 1.
The authors state:
‘The rating in each experiments was between 0.7 and 0.8. Contemplating the truth that the overall high quality of the anticipated photographs is decrease than the true photographs (it’s harder generally to detect objects in decrease high quality photographs), this rating signifies that the overwhelming majority of automobiles that current within the floor reality current within the predicted photographs.’
The researchers concluded that the detection of black automobiles, which is an issue for each pc vision-based techniques and for LiDAR, might be effected by figuring out a lack of information for sections of the picture:
‘The truth that in predicted photographs, coloration info and precise shapes usually are not similar to floor reality, means that that prediction of black automobiles is generally derived from contextual info and never from the LiDAR reflectivity of the factors themselves.
‘We recommend that, along with the traditional LiDAR system, a second system that generates photo-realistic photographs from LiDAR level clouds would run concurrently for visible object recognition in real-time.’
The researchers intend to develop the work sooner or later, with bigger datasets.
Latency, and the Crowded SDV Processing Stack
One commenter on the much-shared Twitter publish of the Autopilot crash estimated that, touring at round 75mph (110 toes a second), a video feed working at 20fps would solely cowl 5.5 toes per body. Nevertheless, if the car was working Tesla’s newest {hardware} and software program, the body fee would have been 36fps (for the principle digicam), which units the analysis fee at 110 toes per second (three toes per body).
In addition to value and ergonomics, the issue with utilizing LiDAR as a supplementary information stream is the sheer scale of the informational ‘site visitors jam’ of sensor enter to the SDV processing framework. Mixed with the essential nature of the duty, this appears to have compelled radar and LiDAR out of the Autopilot stack in favor of image-based analysis strategies.
Due to this fact it appears unlikely {that a} system utilizing LiDAR – which in itself would add to a processing bottleneck on Autopilot – to deduce photo-real imagery is possible from Tesla’s viewpoint.
Tesla founder Elon Musk is not any blanket critic of LiDAR, which he factors out is utilized by SpaceX for docking procedures, however considers that the expertise is ‘pointless’ for self-driving automobiles. Musk means that an occlusion-penetrating wavelength, such because the ~4mm of precision radar, can be extra helpful.
Nevertheless, as of June 2021, Tesla automobiles are not outfitted with radar both. There don’t presently appear to be many initiatives designed to generate picture streams from radar in the identical means as the present Israeli undertaking makes an attempt (although the US Division of Vitality sponsored one try for radar-sourced GAN imagery in 2018).
First printed twenty third December 2021.
[ad_2]

