


[ad_1]
How can we make a robotic be taught in the actual world whereas guaranteeing security? In this work, we present the way it’s doable to face this drawback. The important thing concept to use area information and use the constraint definition to our benefit. Following our strategy, it’s doable to implement studying robotic brokers that may discover and be taught in an arbitrary atmosphere whereas guaranteeing security on the identical time.
Security and studying in robots
Security is a elementary function in real-world robotics purposes: robots shouldn’t trigger harm to the atmosphere, to themselves, they usually should guarantee the protection of individuals working round them. To make sure security after we deploy a brand new utility, we need to keep away from constraint violation at any time. These stringent security constraints are tough to implement in a reinforcement studying setting. That is the rationale why it’s laborious to deploy studying brokers in the actual world. Classical reinforcement studying brokers use random exploration, equivalent to Gaussian insurance policies, to behave within the atmosphere and extract helpful information to enhance job efficiency. Nonetheless, random exploration could trigger constraint violations. These constraint violations should be averted in any respect prices in robotic platforms, as they usually lead to a serious system failure.
Whereas the robotic framework is difficult, it’s also a really well-known and well-studied drawback: thus, we will exploit some key outcomes and information from the sector. Certainly, usually a robotic’s kinematics and dynamics are identified and may be exploited by the training techniques. Additionally, bodily constraints e.g., avoiding collisions and implementing joint limits, may be written in analytical kind. All this info may be exploited by the training robotic.
Our strategy
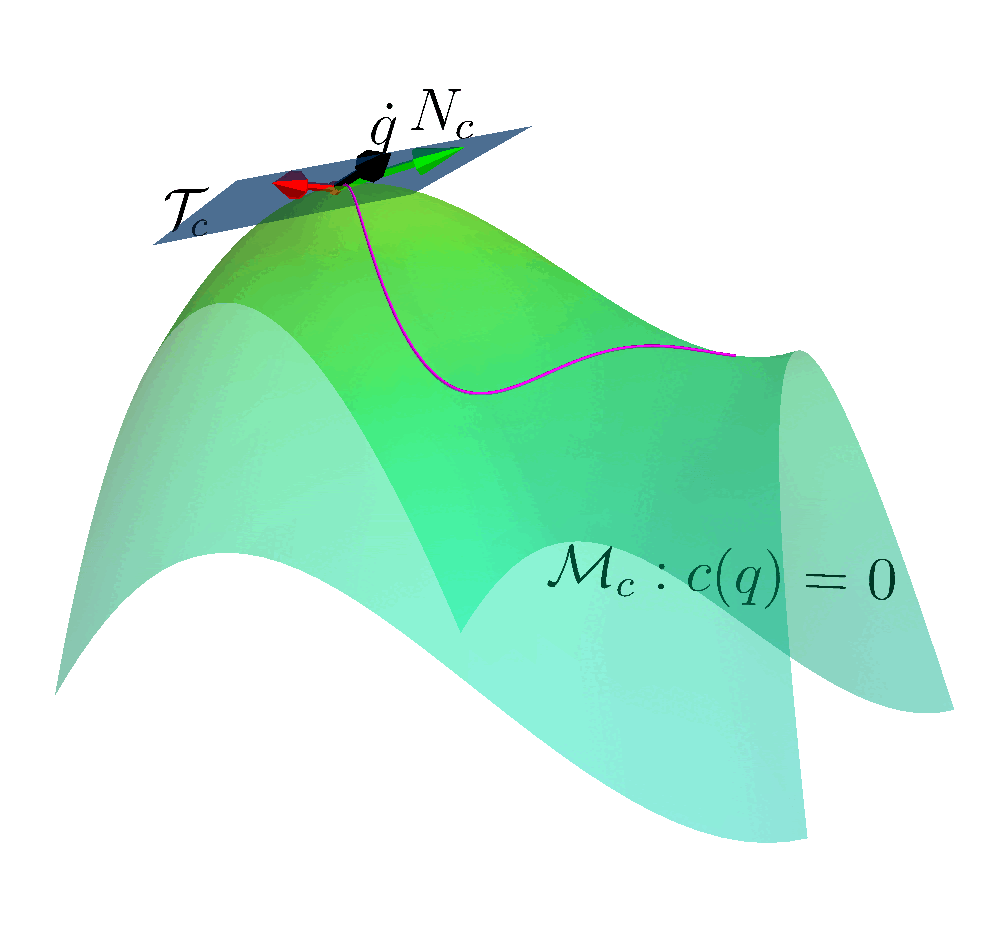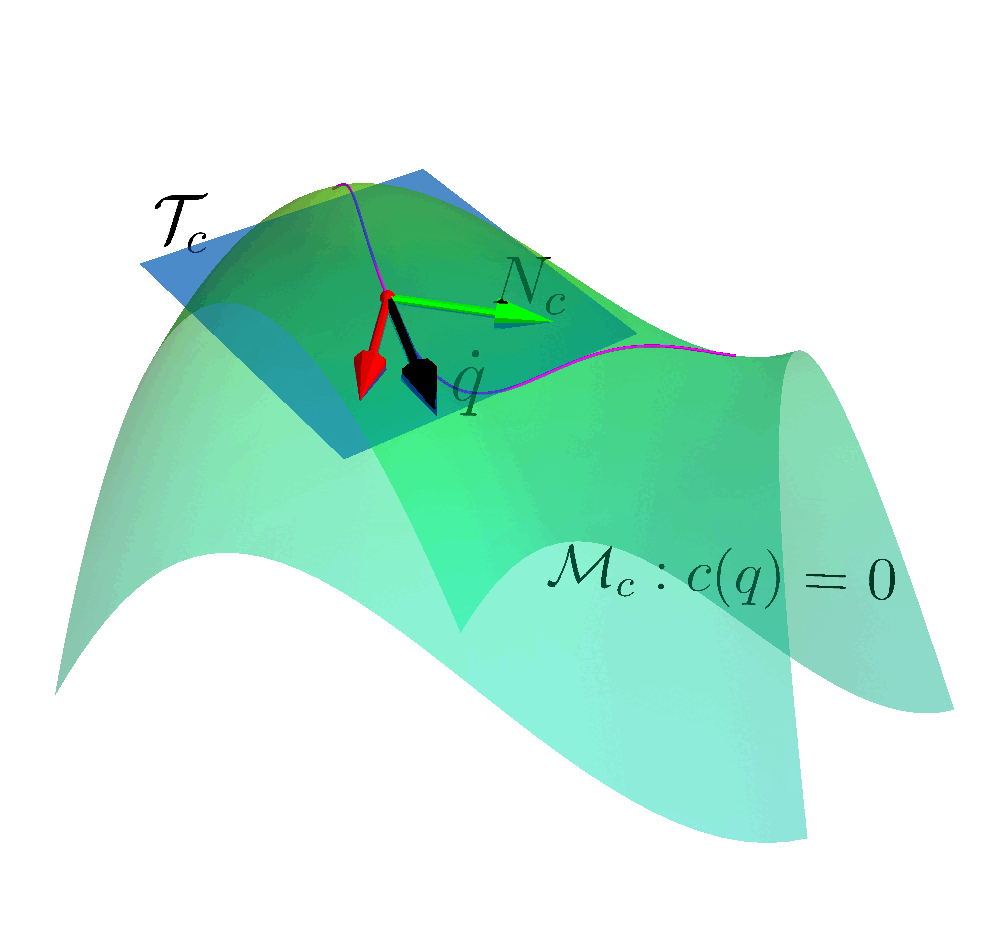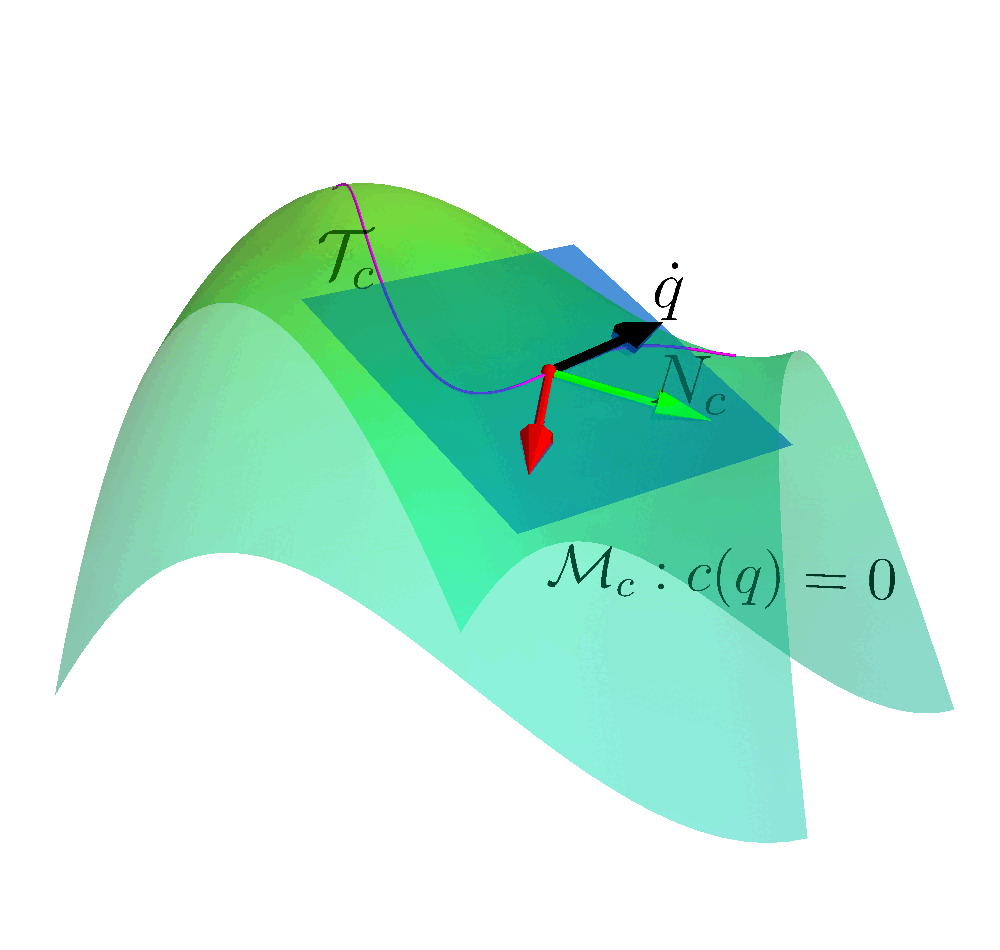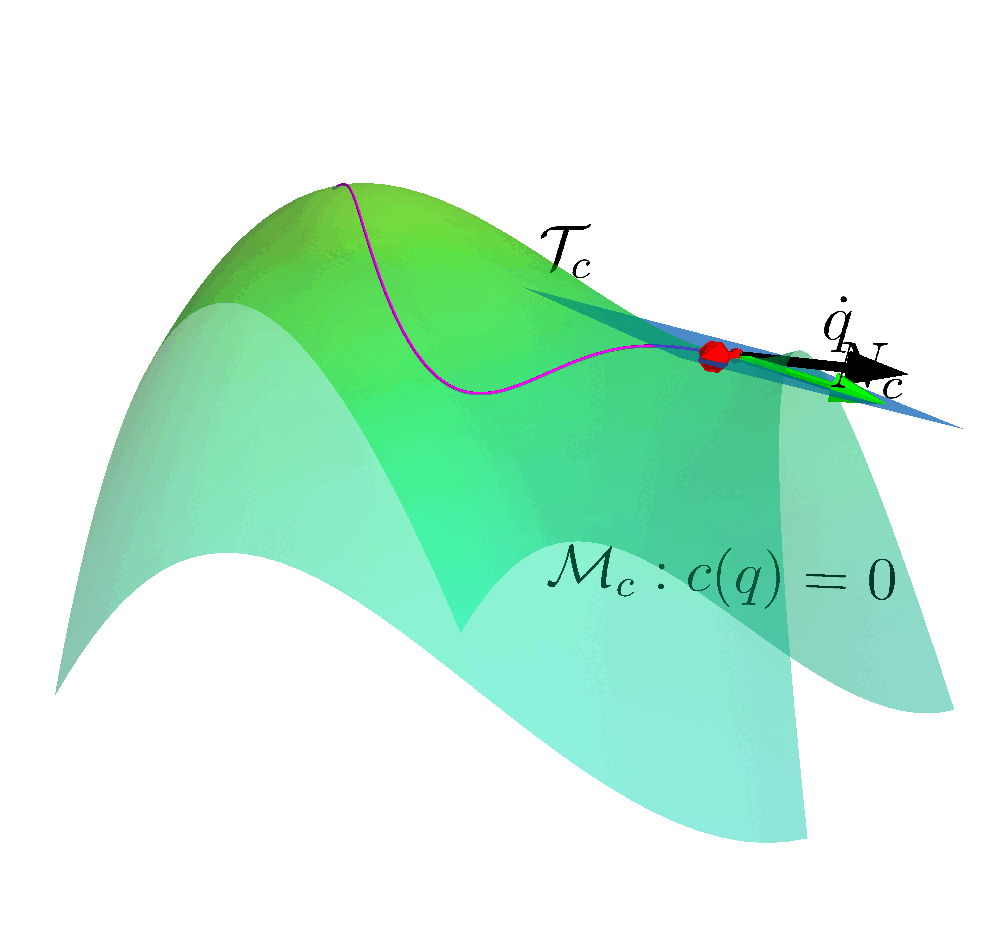
Many reinforcement studying approaches attempt to clear up the protection drawback by incorporating the constraint info within the studying course of. This strategy usually leads to slower studying performances, whereas not with the ability to guarantee security throughout the entire studying course of. As an alternative, we current a novel viewpoint to the issue, introducing ATACOM (Performing on the TAngent house of the COnstraint Manifold). Completely different from different state-of-the-art approaches, ATACOM tries to create a secure motion house during which each motion is inherently secure. To take action, we have to assemble the constraint manifold and exploit the essential area information of the agent. As soon as we now have the constraint manifold, we outline our motion house because the tangent house to the constraint manifold.
We are able to assemble the constraint manifold utilizing arbitrary differentiable constraints. The one requirement is that the constraint perform should rely solely on controllable variables i.e. the variables that we will straight management with our management motion. An instance might be the robotic joint positions and velocities.
We are able to assist each equality and inequality constraints. Inequality constraints are notably vital as they can be utilized to keep away from particular areas of the state house or to implement the joint limits. Nonetheless, they don’t outline a manifold. To acquire a manifold, we rework the inequality constraints into equality constraints by introducing slack variables.
With ATACOM, we will guarantee security by taking motion on the tangent house of the constraint manifold. An intuitive method to see why that is true is to think about the movement on the floor of a sphere: any level with a velocity tangent to the sphere itself will maintain transferring on the floor of the sphere. The identical concept may be prolonged to extra complicated robotic techniques, contemplating the acceleration of system variables (or the generalized coordinates, when contemplating a mechanical system) as an alternative of velocities.
The above-mentioned framework solely works if we take into account continuous-time techniques, when the management motion is the instantaneous velocity or acceleration. Sadly, the overwhelming majority of robotic controllers and reinforcement studying approaches are discrete-time digital controllers. Thus, even taking the tangent route of the constraint manifold will lead to a constraint violation. It’s at all times doable to cut back the violations by rising the management frequency. Nonetheless, error accumulates over time, inflicting a drift from the constraint manifold. To resolve this subject, we introduce an error correction time period that ensures that the system stays on the reward manifold. In our work, we implement this time period as a easy proportional controller.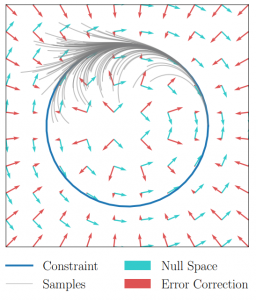
Lastly, many robotics techniques can’t be managed straight by velocity or accelerations. Nonetheless, if an inverse dynamics mannequin or a monitoring controller is out there, we will use it and compute the right management motion.
Outcomes
We tried ATACOM on a simulated air hockey job. We use two various kinds of robots. The primary one is a planar robotic. On this job, we implement joint velocities and we keep away from the collision of the end-effector with desk boundaries.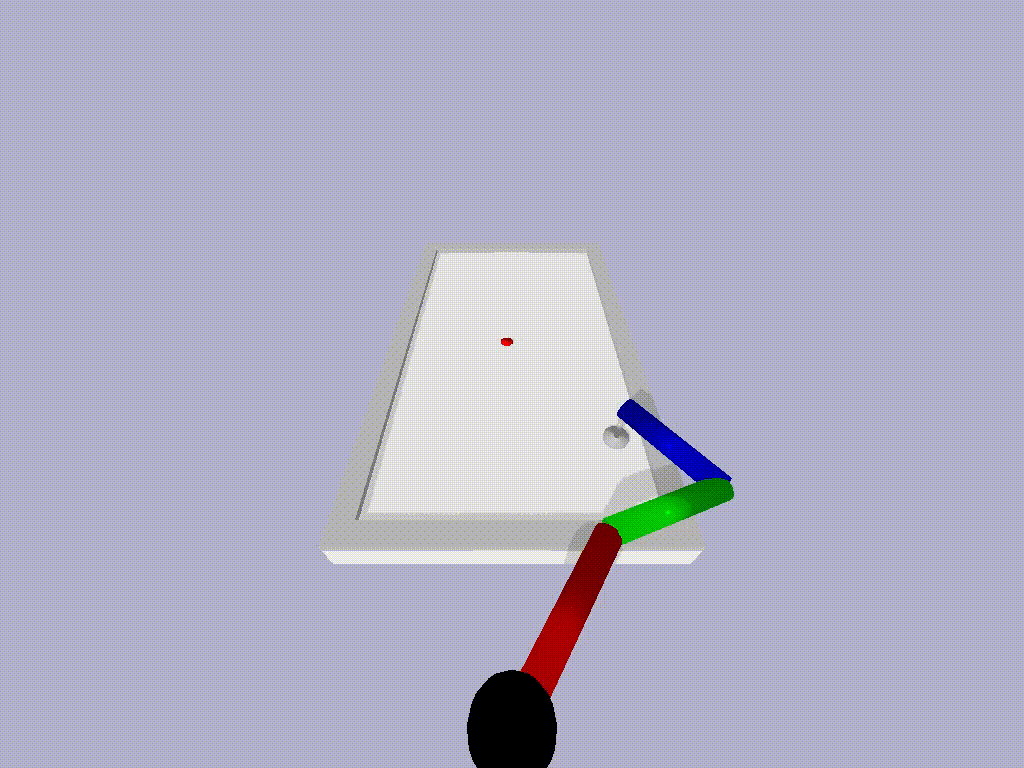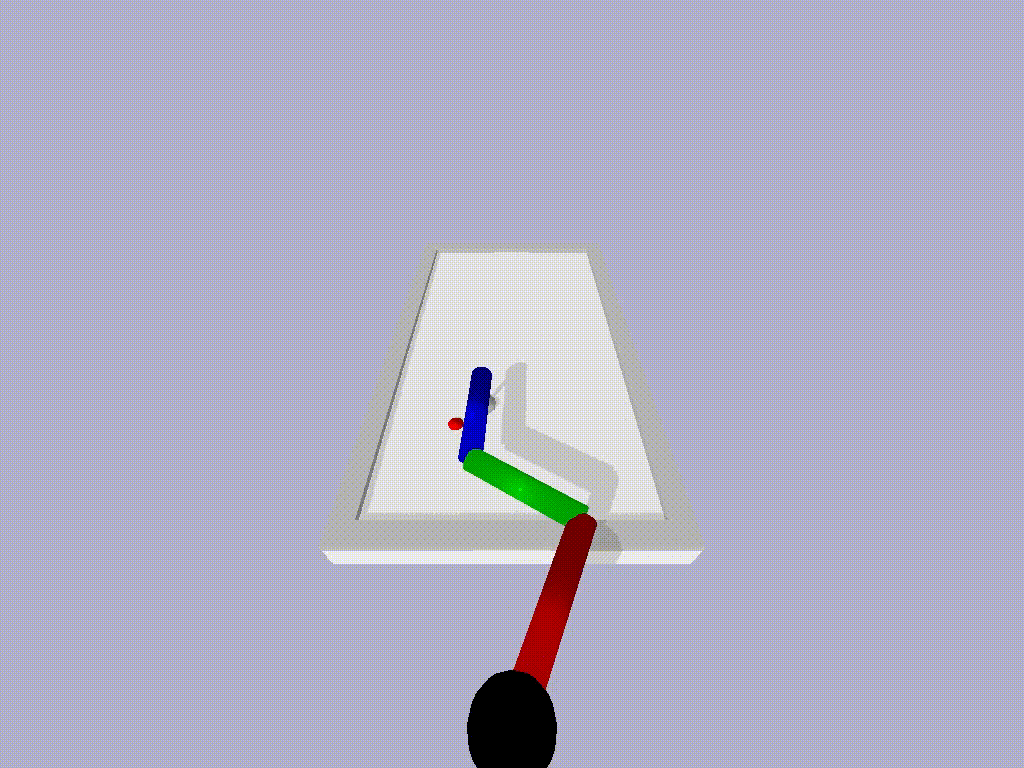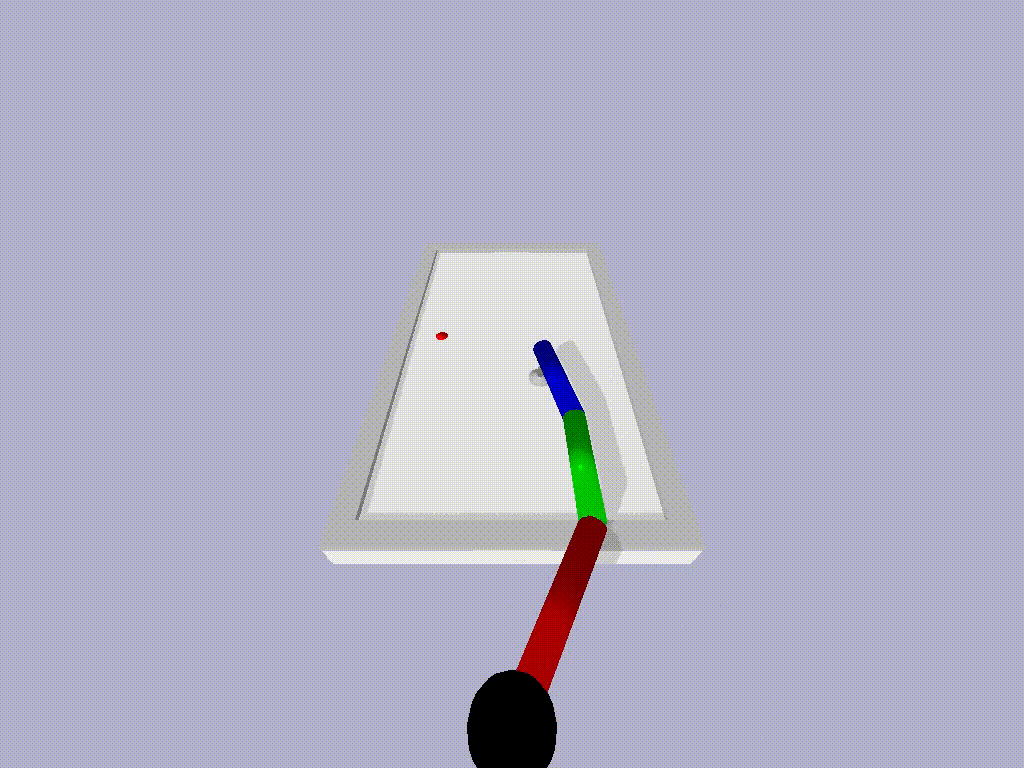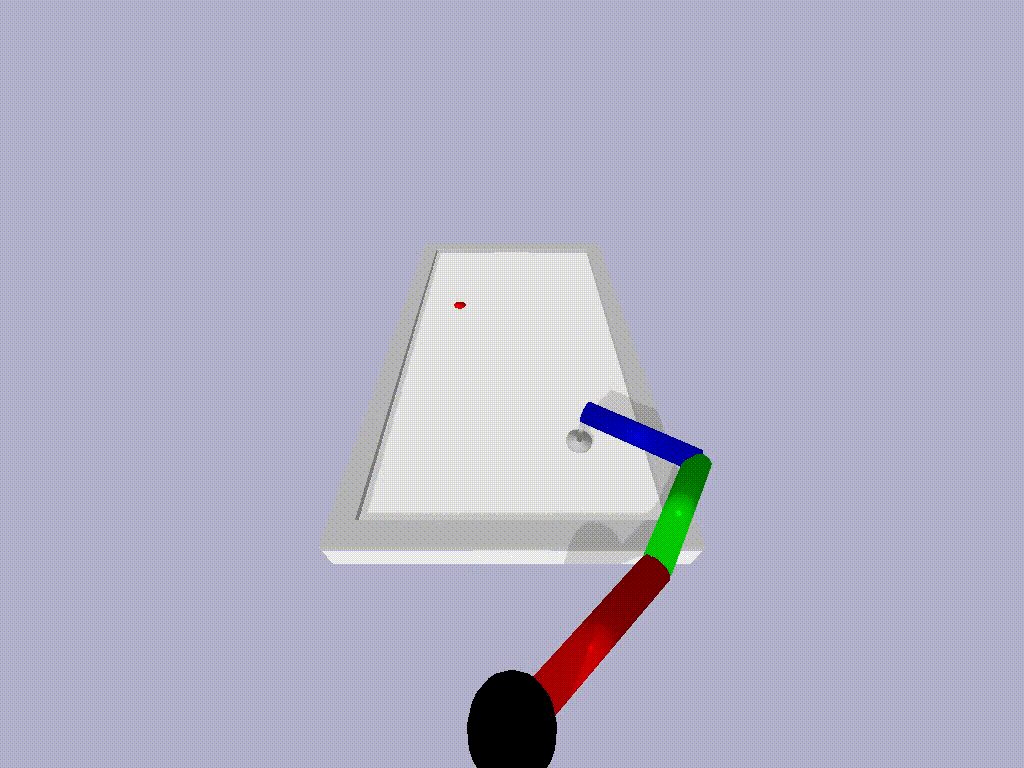
The second robotic is a Kuka Iiwa 14 arm. On this situation, we constrained the end-effector to maneuver on the planar floor and we guarantee no collision will happen between the robotic arm and the desk.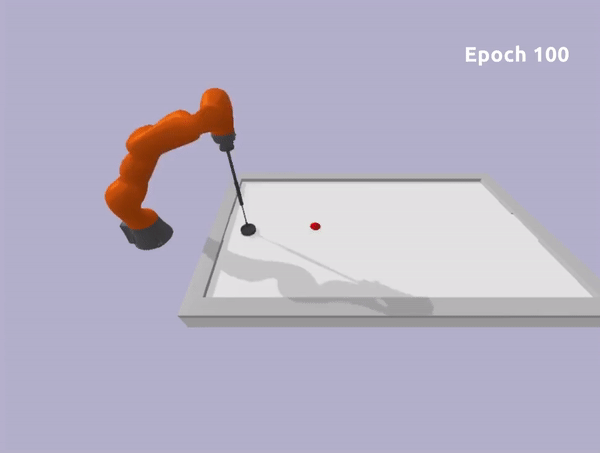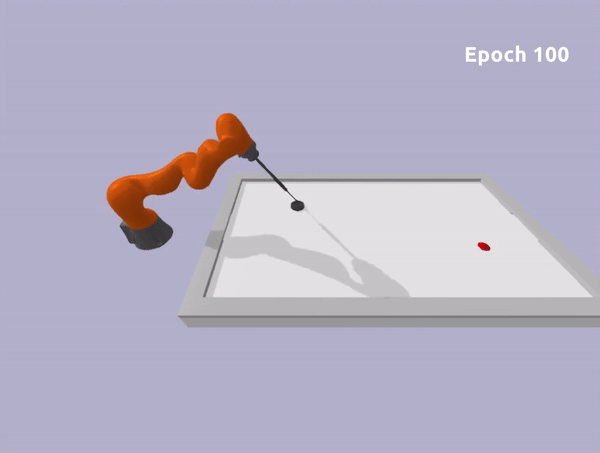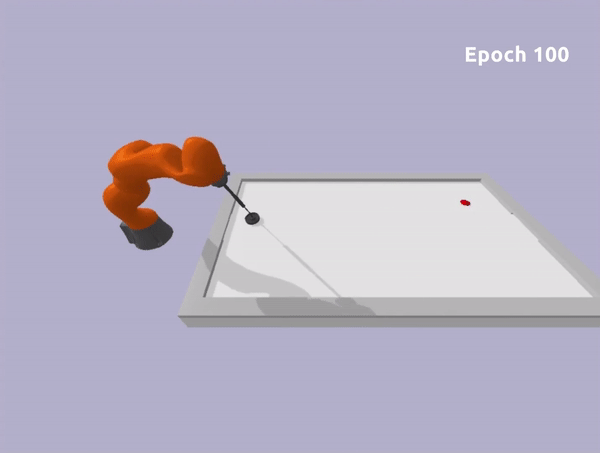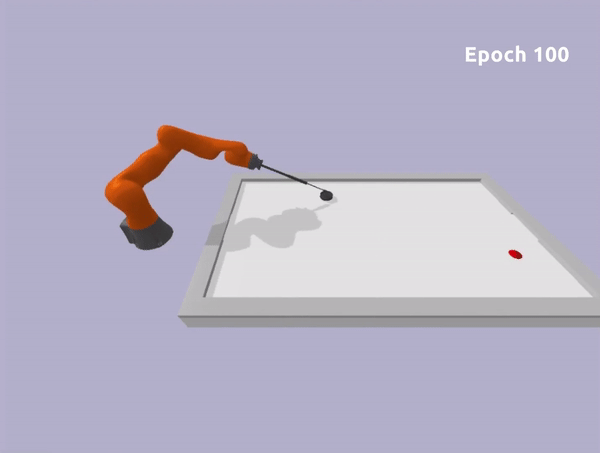
In each experiments, we will be taught a secure coverage utilizing the Tender Actor-Critic algorithm as a studying algorithm together with the ATACOM framework. With our strategy, we’re capable of be taught good insurance policies quick and we will guarantee low constraint violations at any timestep. Sadly, the constraint violation can’t be zero because of discretization, however it may be lowered to be arbitrarily small. This isn’t a serious subject in real-world techniques, as they’re affected by noisy measurements and non-ideal actuation.
Is the protection drawback solved now?
The important thing query to ask is that if we will guarantee any security ensures with ATACOM. Sadly, this isn’t true generally. What we will implement are state constraints at every timestep. This features a broad class of constraints, equivalent to fastened impediment avoidance, joint limits, floor constraints. We are able to prolong our methodology to constraints contemplating not (straight) controllable variables. Whereas we will guarantee security to a sure extent additionally on this situation, we can not be certain that the constraint violation is not going to be violated throughout the entire trajectory. Certainly, if the not controllable variables act in an adversarial approach, they could discover a long-term technique to trigger constraint violation in the long run. A simple instance is a prey-predator situation: even when we be certain that the prey avoids every predator, a gaggle of predators can carry out a high-level technique and entice the agent in the long run.
Thus, with ATACOM we will guarantee security at a step stage, however we’re not ready to make sure long-term security, which requires reasoning at trajectory stage. To make sure this sort of security, extra superior strategies might be wanted.
Discover out extra
The authors have been finest paper award finalists at CoRL this 12 months, for his or her work: Robotic reinforcement studying on the constraint manifold.
- Learn the paper.
- The GitHub web page for the work is right here.
- Learn extra concerning the profitable and shortlisted papers for the CoRL awards right here.
tags: c-Analysis-Innovation
Puze Liu
is a PhD scholar within the Clever Autonomous Programs Group, Technical College Darmstadt
Puze Liu
is a PhD scholar within the Clever Autonomous Programs Group, Technical College Darmstadt
Davide Tateo
is a Postdoctoral Researcher on the Clever Autonomous Programs Laboratory within the Pc Science Division of the Technical College of Darmstadt
Davide Tateo
is a Postdoctoral Researcher on the Clever Autonomous Programs Laboratory within the Pc Science Division of the Technical College of Darmstadt
Haitham Bou-Ammar
leads the reinforcement studying workforce at Huawei applied sciences Analysis & Improvement UK and is an Honorary Lecturer at UCL
Haitham Bou-Ammar
leads the reinforcement studying workforce at Huawei applied sciences Analysis & Improvement UK and is an Honorary Lecturer at UCL
Jan Peters
is a full professor for Clever Autonomous Programs on the Technische Universitaet Darmstadt and a senior analysis scientist on the MPI for Clever Programs
Jan Peters
is a full professor for Clever Autonomous Programs on the Technische Universitaet Darmstadt and a senior analysis scientist on the MPI for Clever Programs
[ad_2]

