



[ad_1]
A brand new analysis collaboration between Carnegie Mellon and autonomous driving expertise firm Argo AI has developed a cheap technique for producing dynamic fly-through environments primarily based on Neural Radiance Fields (NeRF), utilizing footage captured by drones.
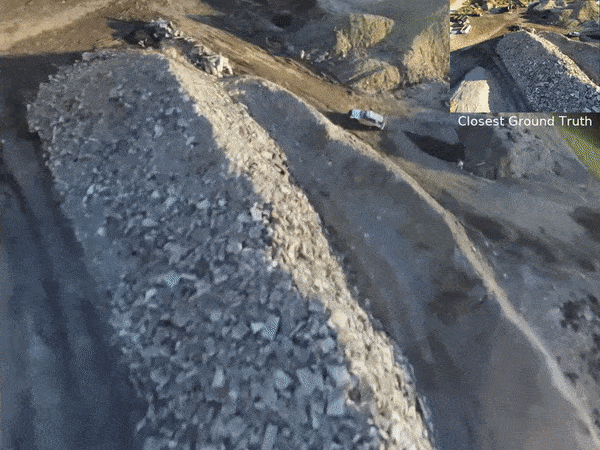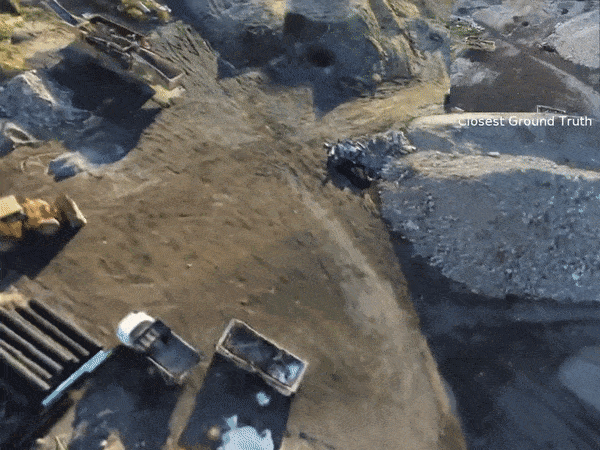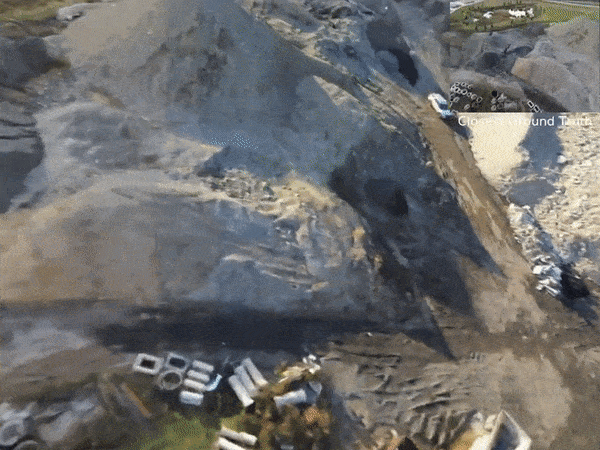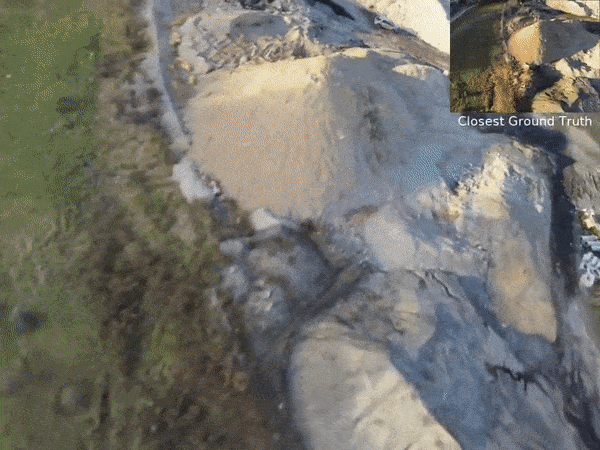
Mega-NeRF presents interactive fly-bys primarily based on drone footage, with on-demand LOD. For extra element (at higher decision), try the video embedded on the finish of this text. Supply: Mega-NeRF-Full – Rubble Flythrough – https://www.youtube.com/watch?v=t_xfRmZtR7k
The brand new strategy, known as Mega-NeRF, obtains a 40x speed-up in comparison with the typical Neural Radiance Fields rendering commonplace, in addition to providing one thing notably completely different from the usual tanks and temples that recur in new NeRF papers.
The new paper is titled Mega-NeRF: Scalable Development of Massive-Scale NeRFs for Digital Fly-Throughs, and comes from three researchers at Carnegie Mellon, certainly one of whom additionally represents Argo AI.
Modeling NeRF Panorama for Search and Rescue
The authors contemplate that search-and-rescue (SAR) is a probable optimum use case for his or her method. When evaluating an SAR panorama, drones are at the moment constrained each by bandwidth and battery life restrictions, and are subsequently not normally ready to acquire detailed or complete protection earlier than needing to return to base, at which level their collected knowledge is transformed to static 2D aerial view maps.
The authors state:
‘We think about a future during which neural rendering lifts this evaluation into 3D, enabling response groups to examine the sphere as in the event that they have been flying a drone in real-time at a degree of element far past the achievable with basic Construction-from-Movement (SfM).’
Tasked with this use-case, the authors have sought to create a fancy NeRF-based mannequin that may be skilled inside a day, provided that the life-expectancy of survivors in search-and-rescue operations decreases by as much as 80% through the first 24 hours.
The authors be aware that the drone seize datasets needed to coach a Mega-NeRF mannequin are ‘orders of magnitude’ bigger than a regular dataset for NeRF, and that mannequin capability should be notably increased than in a default fork or spinoff of NeRF. Moreover, interactivity and explorability is crucial in a search and rescue terrain map, whereas commonplace real-time NeRF renders predict a way more restricted vary of pre-calculated doable motion.
Divide and Conquer
To handle these points the authors created a geometrical clustering algorithm that divides the duty up into submodules, and successfully creates a matrix of sub-NeRFs which can be skilled contemporaneously.
On the level of rendering, the authors additionally implement a just-in-time visualization algorithm that’s responsive sufficient to facilitate full interactivity with out extreme pre-processing, just like the best way that video video games will ramp up element on objects as they strategy the person’s viewpoint, however which stay at an energy-saving and extra rudimentary scale when within the distance.
These economies, the authors contend, result in higher element than earlier strategies that try to deal with very large topic areas in an interactive context. By way of extrapolating element from restricted decision video footage, the authors additionally be aware Mega-NeRF’s visible enchancment over the equal performance in UC Berkeley’s PlenOctrees.

The challenge’s use of chained sub-NeRFs relies on KiloNeRF’s real-time rendering capabilities, the authors acknowledge. Nevertheless, Mega-NeRF departs from this strategy by truly performing ‘sharding’ (discrete shunting of aspects of a scene) throughout coaching, fairly than KiloNeRF’s post-processing strategy, which takes an already-calculated NeRF scene and subsequently transforms it into an explorable area.

A discrete coaching set is created for submodules, comprised of coaching picture pixels whose trajectory would possibly span the cell that it represents. Consequently, every module is skilled completely individually from adjoining cells. Supply: https://arxiv.org/pdf/2112.10703.pdf
The authors characterize Mega-NeRF as ‘a reformulation of the NeRF structure that sparsifies layer connections in a spatially-aware method, facilitating effectivity enhancements at coaching and rendering time’.

Conceptual comparability of coaching and knowledge discretization in NeRF, NeRF++, and Mega-NeRF. Supply: https://meganerf.cmusatyalab.org/
The authors declare that Mega-NeRF’s use of novel temporal coherence methods avoids the necessity for extreme pre-processing, overcomes intrinsic limits on scale, and enacts the next degree of element than prior comparable works, with out sacrificing interactivity, or necessitating a number of days of coaching.
The researchers are additionally making obtainable large-scale datasets containing 1000’s of high-definition photos obtained from drone footage captured over 100,000 sq. meters of land round an industrial advanced. The 2 obtainable datasets are ‘Constructing’ and ‘Rubble’.
Bettering on Prior Work
The paper notes that earlier efforts in the same vein, together with SneRG, PlenOctree, and FastNeRF, all depend on some sort of caching or pre-processing that provides compute and/or time overheads which can be unsuitable for the creation of digital search-and-rescue environments.
Whereas KiloNeRF derives sub-NeRFs from an current assortment of multilayer perceptrons (MLPs), it’s architecturally constrained to inside scenes with restricted extensibility or capability to deal with higher-scale environments. FastNeRF, in the meantime, shops a ‘baked’, pre-computed model of the NeRF mannequin right into a devoted knowledge construction and permits the end-user to navigate by means of it through a devoted MLP, or by means of spherical foundation computation.
Within the KiloNeRF situation, the utmost decision of every side within the scene is already calculated, and no better decision will develop into obtainable if the person decides to ‘zoom in’.
Against this, NeRF++ can natively deal with non-limited, exterior environments by sectioning the potential explorable area into foreground and background areas, every of which is overseen by a devoted MLP mannequin, which performs ray-casting previous to closing composition.
Lastly, NeRF within the Wild, which doesn’t immediately handle limitless areas, nonetheless improves picture high quality within the Phototourism dataset, and its look embeddings have been adopted within the structure for Mega-NeRF.
The authors concede additionally that Mega-NeRF is impressed by Construction-from-Movement (SfM) tasks, notably Washington College’s Constructing Rome in a Day challenge.
Temporal Coherence
Like PlenOctree, Mega-NeRF precomputes a tough cache of coloration and opacity within the area of present person focus. Nevertheless, as an alternative of computing paths every time which can be within the neighborhood of the calculated path, as PlenOctree does, Mega-NeRF ‘saves’ and reuses this data by subdividing the calculated tree, following a rising pattern to disentangle NeRF’s tightly-bound processing etiquette.

On the left, PlenOctree’s single-use calculation. Center, Mega-NeRF’s dynamic growth of the octree, relative to the present place of the fly-through. Proper, the octree is reused for subsequent navigation.
This economic system of calculation, based on the authors, notably reduces the processing burden through the use of on-the-fly calculations as a neighborhood cache, fairly than estimating and caching all of them pre-emptively, based on current apply.
Guided Sampling
After preliminary sampling, in accord with commonplace fashions thus far, Mega-NeRF enacts a second spherical of guided ray-sampling after octree refinement, with the intention to enhance picture high quality. For this, Mega-NeRF makes use of solely a single cross primarily based on the prevailing weights within the octree knowledge construction.


As might be seen within the picture above, from the brand new paper, commonplace sampling wastes calculation sources by evaluating an extreme quantity of the goal space whereas Mega-NeRF limits the calculations primarily based on a information of the place geometry is current, throttling calculations above a pre-set threshold.
Information and Coaching
The researchers examined Mega-NeRF on numerous datasets, together with the 2 aforementioned, hand-crafted units taken from drone footage over industrial floor. The primary dataset, Mill 19 – Constructing, options footage taken throughout an space of 500 x 250 sq. meters. The second, Mill 19 – Rubble, represents comparable footage taken over an adjoining building website, during which the researchers positioned dummies representing potential survivors in a search-and-rescue situation.

From the paper’s supplemental materials: Left, the quadrants to be coated by the Parrot Anafi drone (pictured heart, and within the distance within the right-hand picture).
Moreover, the structure was examined towards a number of scenes from UrbanScene3D, from the Visible Computing Analysis Heart at Shenzhen College in China, which consists of HD drone-captured footage of enormous city environments; and the Quad 6k dataset, from Indiana College’s IU Laptop Imaginative and prescient Lab.
Coaching came about over 8 submodules, every with 8 layers of 256 hidden items, and a subsequent 128 channel ReLU layer. Not like NeRF, the identical MLP was used to question coarse and refined samples, decreasing the general mannequin measurement and allowing the reuse of coarse community outputs on the subsequent rendering stage. The authors estimate that this protects 25% of mannequin queries for every ray.
1024 rays have been sampled per batch beneath Adam at a beginning be taught fee of 5×10⁴, decaying to 5×10⁻⁵. The looks embeddings have been dealt with in the identical method because the aforementioned NeRF within the Wild. Blended precision sampling (coaching at decrease precision than 32-bit floating level) was used, and the MLP width mounted at 2048 hidden items.
Testing and Outcomes
Within the researchers’ checks, Mega-NeRF was in a position to robustly outperform NeRF, NeRF++ and DeepView after coaching for 500,000 iterations throughout the aforementioned datasets. For the reason that Mega-NeRF goal situation is time-constrained, the researchers allowed the slower prior frameworks further time past the 24-hour restrict, and report that Mega-NeRF nonetheless outperformed them, even given these benefits.


The metrics used have been Peak signal-to-noise ratio (PSNR), the VGG model of LPIPS, and SSIM. Coaching came about on a single machine outfitted with eight V100 GPUs – successfully, on 256GB of VRAM, and 5120 Tensor cores.

Pattern outcomes from the Mega-NeRF experiments (please see the paper for extra prolonged outcomes throughout all frameworks and datasets) present that PlenOctree causes notable voxelization, whereas KiloNeRF produces artifacts and customarily extra blurry outcomes.
You may try the challenge’s related video beneath, whereas the challenge web page is at https://meganerf.cmusatyalab.org/, and the launched code is at https://github.com/cmusatyalab/mega-nerf.
First revealed twenty first December 2021.
[ad_2]

