



[ad_1]
Federated studying permits customers to coach a mannequin with out sending uncooked information to a central server, thus avoiding the gathering of privacy-sensitive information. Typically that is carried out by studying a single world mannequin for all customers, regardless that the customers could differ of their information distributions. For instance, customers of a cell keyboard utility could collaborate to coach a suggestion mannequin however have completely different preferences for the strategies. This heterogeneity has motivated algorithms that may personalize a world mannequin for every consumer.
Nonetheless, in some settings privateness issues could prohibit studying a totally world mannequin. Think about fashions with user-specific embeddings, similar to matrix factorization fashions for recommender techniques. Coaching a totally world federated mannequin would contain sending consumer embedding updates to a central server, which may doubtlessly reveal the preferences encoded within the embeddings. Even for fashions with out user-specific embeddings, having some parameters be fully native to consumer units would cut back server-client communication and responsibly personalize these parameters to every consumer.
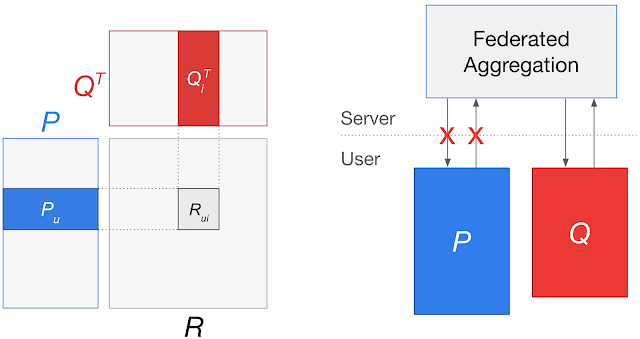 |
| Left: A matrix factorization mannequin with a consumer matrix P and objects matrix Q. The consumer embedding for a consumer u (Pu) and merchandise embedding for merchandise i (Qi) are educated to foretell the consumer’s ranking for that merchandise (Rui). Proper: Making use of federated studying approaches to study a world mannequin can contain sending updates for Pu to a central server, doubtlessly leaking particular person consumer preferences. |
In “Federated Reconstruction: Partially Native Federated Studying”, offered at NeurIPS 2021, we introduce an method that permits scalable partially native federated studying, the place some mannequin parameters are by no means aggregated on the server. For matrix factorization, this method trains a recommender mannequin whereas maintaining consumer embeddings native to every consumer system. For different fashions, this method trains a portion of the mannequin to be fully private for every consumer whereas avoiding communication of those parameters. We efficiently deployed partially native federated studying to Gboard, leading to higher suggestions for a whole lot of tens of millions of keyboard customers. We’re additionally releasing a TensorFlow Federated tutorial demonstrating learn how to use Federated Reconstruction.
Federated Reconstruction
Earlier approaches for partially native federated studying used stateful algorithms, which require consumer units to retailer a state throughout rounds of federated coaching. Particularly, these approaches required units to retailer native parameters throughout rounds. Nonetheless, these algorithms are inclined to degrade in large-scale federated studying settings. In these instances, the vast majority of customers don’t take part in coaching, and customers who do take part doubtless solely achieve this as soon as, leading to a state that’s hardly ever accessible and might get stale throughout rounds. Additionally, all customers who don’t take part are left with out educated native parameters, stopping sensible purposes.
Federated Reconstruction is stateless and avoids the necessity for consumer units to retailer native parameters by reconstructing them every time wanted. When a consumer participates in coaching, earlier than updating any globally aggregated mannequin parameters, they randomly initialize and prepare their native parameters utilizing gradient descent on native information with world parameters frozen. They’ll then calculate updates to world parameters with native parameters frozen. A spherical of Federated Reconstruction coaching is depicted beneath.
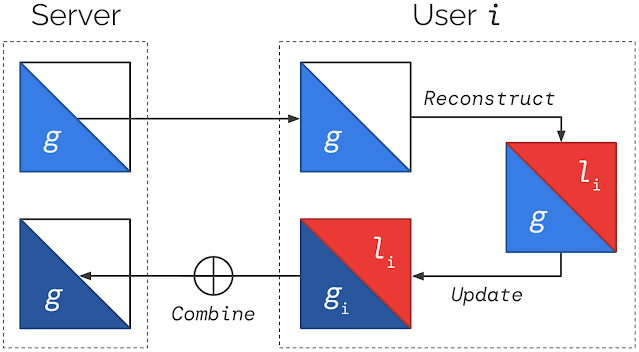 |
| Fashions are partitioned into world and native parameters. For every spherical of Federated Reconstruction coaching: (1) The server sends the present world parameters g to every consumer i; (2) Every consumer i freezes g and reconstructs their native parameters li; (3) Every consumer i freezes li and updates g to provide gi; (4) Customers’ gi are averaged to provide the worldwide parameters for the subsequent spherical. Steps (2) and (3) typically use distinct elements of the native information. |
This straightforward method avoids the challenges of earlier strategies. It doesn’t assume customers have a state from earlier rounds of coaching, enabling large-scale coaching, and native parameters are all the time freshly reconstructed, stopping staleness. Customers unseen throughout coaching can nonetheless get educated fashions and carry out inference by merely reconstructing native parameters utilizing native information.
Federated Reconstruction trains higher performing fashions for unseen customers in comparison with different approaches. For a matrix factorization job with unseen customers, the method considerably outperforms each centralized coaching and baseline Federated Averaging.
| RMSE ↓ | Accuracy ↑ | |
| Centralized | 1.36 | 40.8% |
| FedAvg | .934 | 40.0% |
| FedRecon (this work) | .907 | 43.3% |
| Root-mean-square-error (decrease is healthier) and accuracy for a matrix factorization job with unseen customers. Centralized coaching and Federated Averaging (FedAvg) each reveal privacy-sensitive consumer embeddings to a central server, whereas Federated Reconstruction (FedRecon) avoids this. |
These outcomes may be defined by way of a connection to meta studying (i.e., studying to study); Federated Reconstruction trains world parameters that result in quick and correct reconstruction of native parameters for unseen customers. That’s, Federated Reconstruction is studying to study native parameters. In observe, we observe that only one gradient descent step can yield profitable reconstruction, even for fashions with about a million native parameters.
Federated Reconstruction additionally gives a solution to personalize fashions for heterogeneous customers whereas decreasing communication of mannequin parameters — even for fashions with out user-specific embeddings. To guage this, we apply Federated Reconstruction to personalize a subsequent phrase prediction language mannequin and observe a considerable improve in efficiency, attaining accuracy on par with different personalization strategies regardless of lowered communication. Federated Reconstruction additionally outperforms different personalization strategies when executed at a hard and fast communication degree.
| Accuracy ↑ | Communication ↓ | |
| FedYogi | 24.3% | Entire Mannequin |
| FedYogi + Finetuning | 30.8% | Entire Mannequin |
| FedRecon (this work) | 30.7% | Partial Mannequin |
| Accuracy and server-client communication for a subsequent phrase prediction job with out user-specific embeddings. FedYogi communicates all mannequin parameters, whereas FedRecon avoids this. |
Actual-World Deployment in Gboard
To validate the practicality of Federated Reconstruction in large-scale settings, we deployed the algorithm to Gboard, a cell keyboard utility with a whole lot of tens of millions of customers. Gboard customers use expressions (e.g., GIFs, stickers) to speak with others. Customers have extremely heterogeneous preferences for these expressions, making the setting a superb match for utilizing matrix factorization to foretell new expressions a consumer may wish to share.
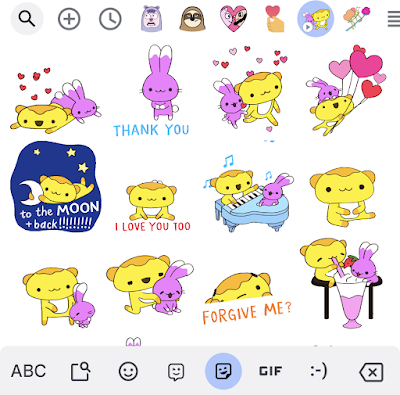 |
| Gboard customers can talk with expressions, preferences for that are extremely private. |
We educated a matrix factorization mannequin over user-expression co-occurrences utilizing Federated Reconstruction, maintaining consumer embeddings native to every Gboard consumer. We then deployed the mannequin to Gboard customers, resulting in a 29.3% improve in click-through-rate for expression suggestions. Since most Gboard customers have been unseen throughout federated coaching, Federated Reconstruction performed a key function on this deployment.
Additional Explorations
We’ve offered Federated Reconstruction, a way for partially native federated studying. Federated Reconstruction permits personalization to heterogeneous customers whereas decreasing communication of privacy-sensitive parameters. We scaled the method to Gboard in alignment with our AI Rules, bettering suggestions for a whole lot of tens of millions of customers.
For a technical walkthrough of Federated Reconstruction for matrix factorization, take a look at the TensorFlow Federated tutorial. We’ve additionally launched general-purpose TensorFlow Federated libraries and open-source code for operating experiments.
Acknowledgements
Karan Singhal, Hakim Sidahmed, Zachary Garrett, Shanshan Wu, Keith Rush, and Sushant Prakash co-authored the paper. Because of Wei Li, Matt Newton, and Yang Lu for his or her partnership on Gboard deployment. We’d additionally prefer to thank Brendan McMahan, Lin Ning, Zachary Charles, Warren Morningstar, Daniel Ramage, Jakub Konecný, Alex Ingerman, Blaise Agüera y Arcas, Jay Yagnik, Bradley Inexperienced, and Ewa Dominowska for his or her useful feedback and assist.
[ad_2]

