



[ad_1]
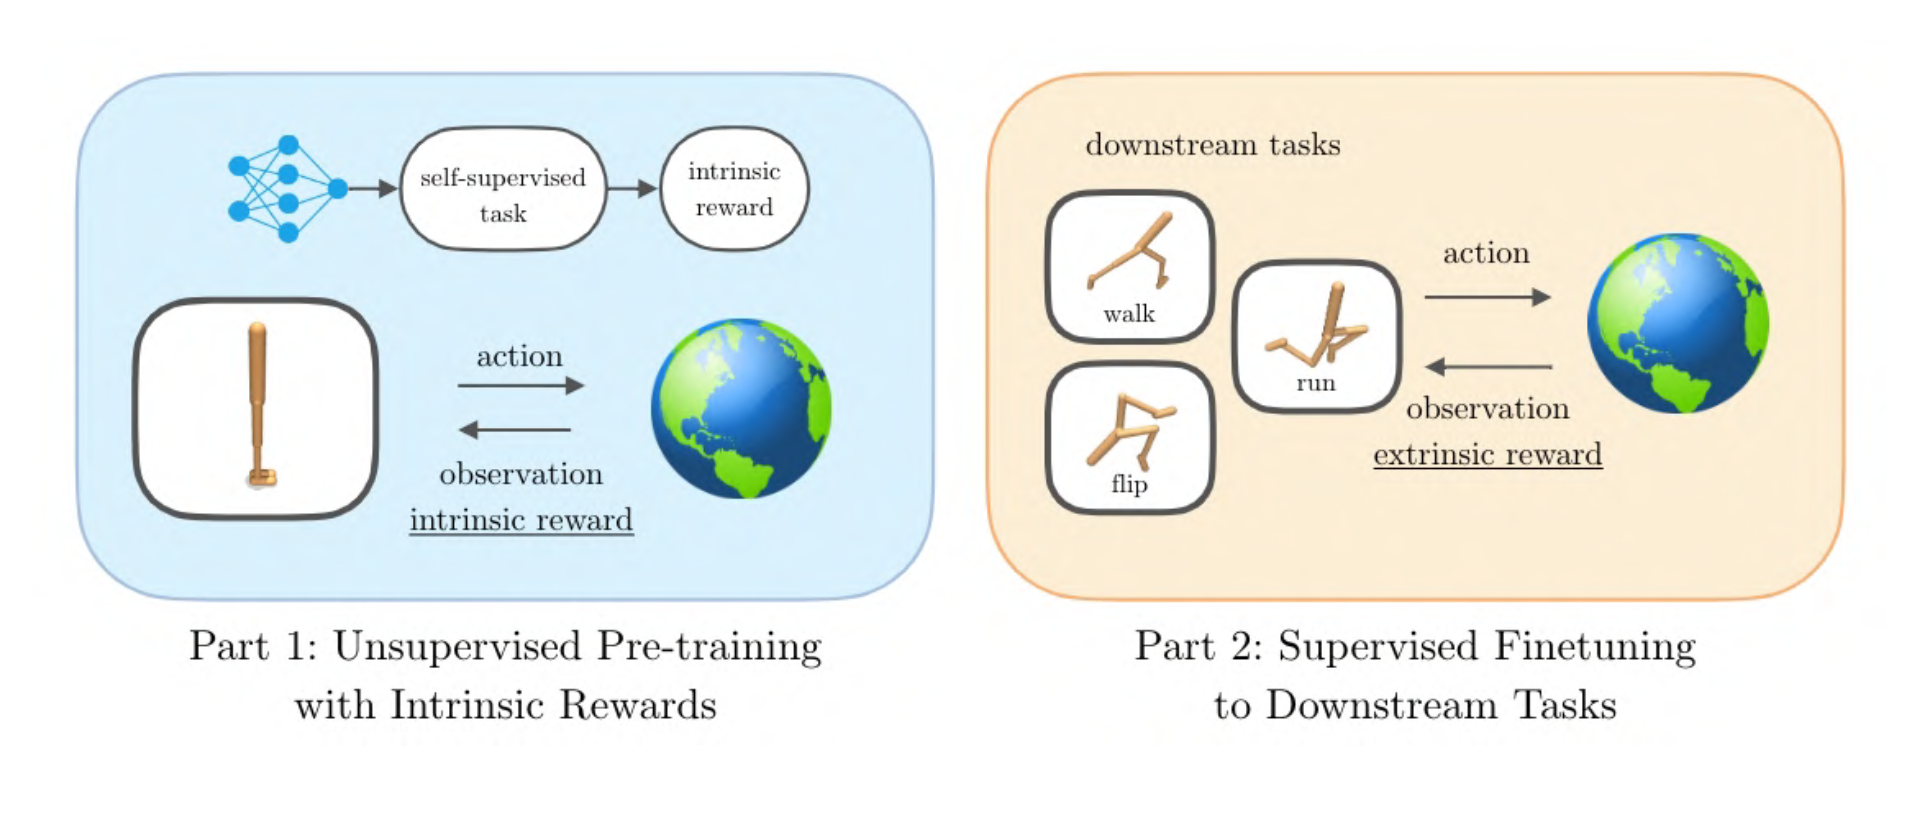
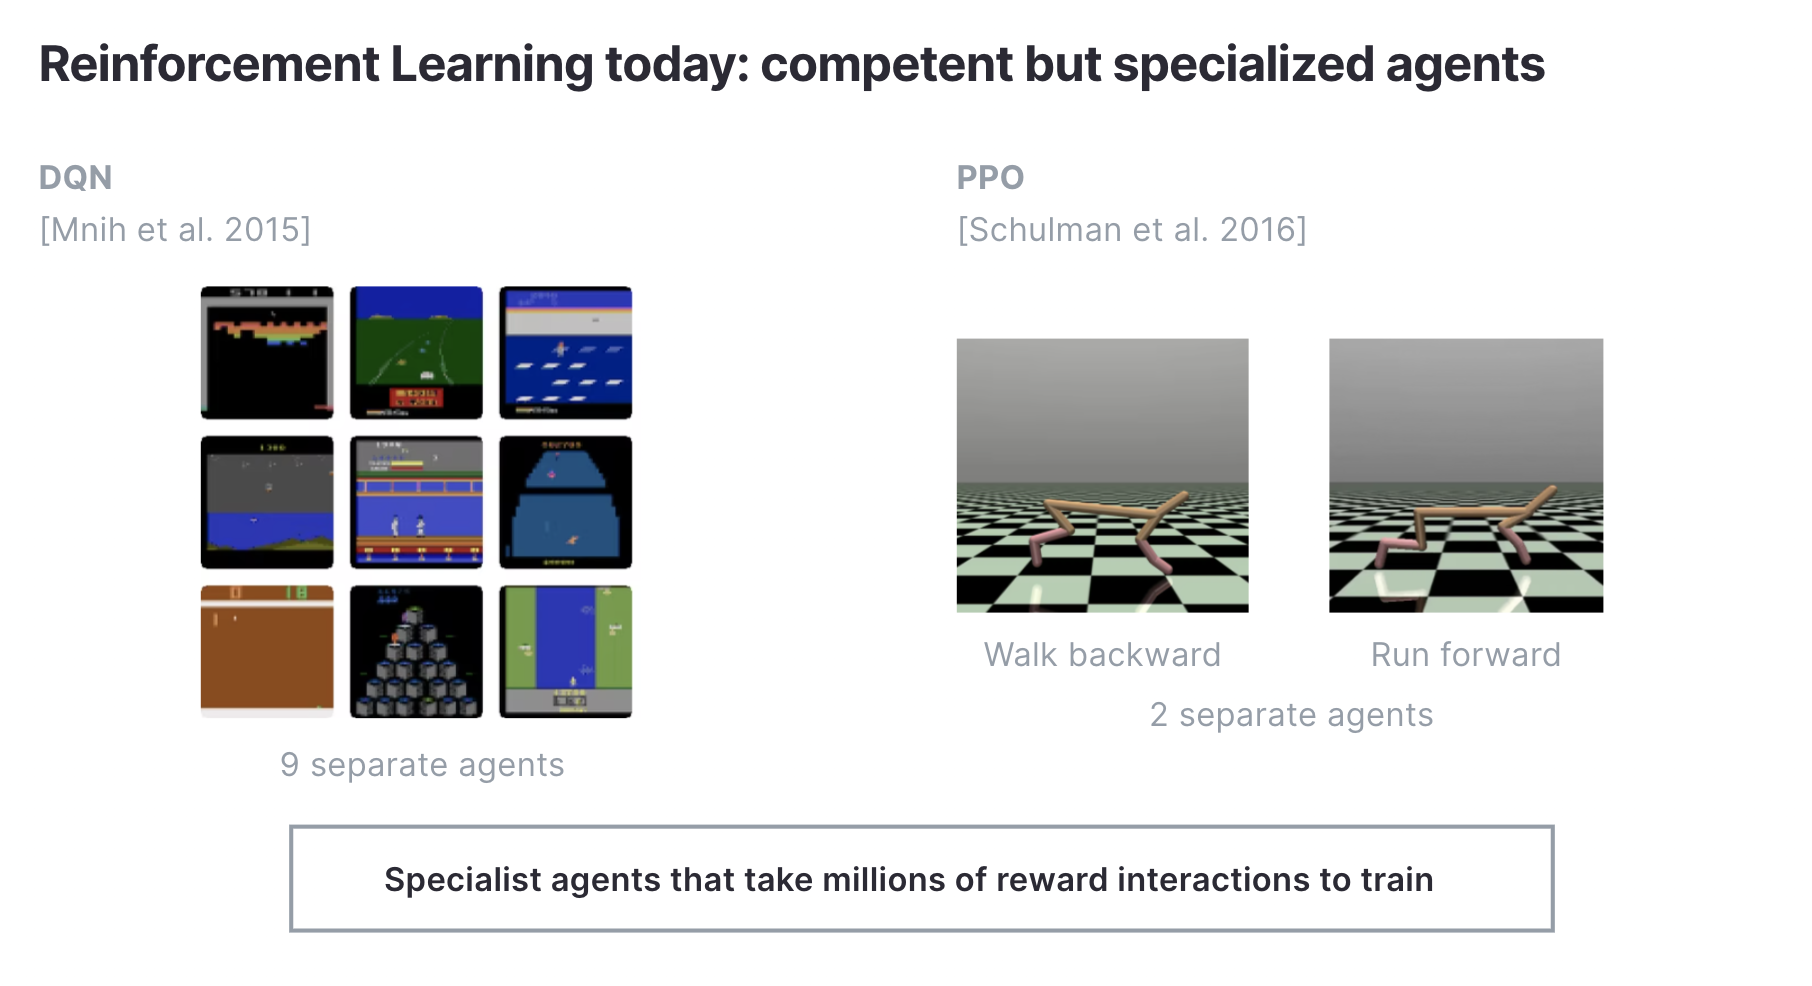
Reinforcement Studying (RL) is a strong paradigm for fixing many issues of curiosity in AI, corresponding to controlling autonomous autos, digital assistants, and useful resource allocation to call just a few. We’ve seen during the last 5 years that, when supplied with an extrinsic reward operate, RL brokers can grasp very advanced duties like taking part in Go, Starcraft, and dextrous robotic manipulation. Whereas large-scale RL brokers can obtain gorgeous outcomes, even the very best RL brokers at present are slender. Most RL algorithms at present can solely resolve the one process they had been skilled on and don’t exhibit cross-task or cross-domain generalization capabilities.
A side-effect of the narrowness of at present’s RL methods is that at present’s RL brokers are additionally very information inefficient. If we had been to coach AlphaGo-like brokers on many duties every agent would doubtless require billions of coaching steps as a result of at present’s RL brokers don’t have the capabilities to reuse prior information to resolve new duties extra effectively. RL as we all know it’s supervised – brokers overfit to a selected extrinsic reward which limits their capability to generalize.
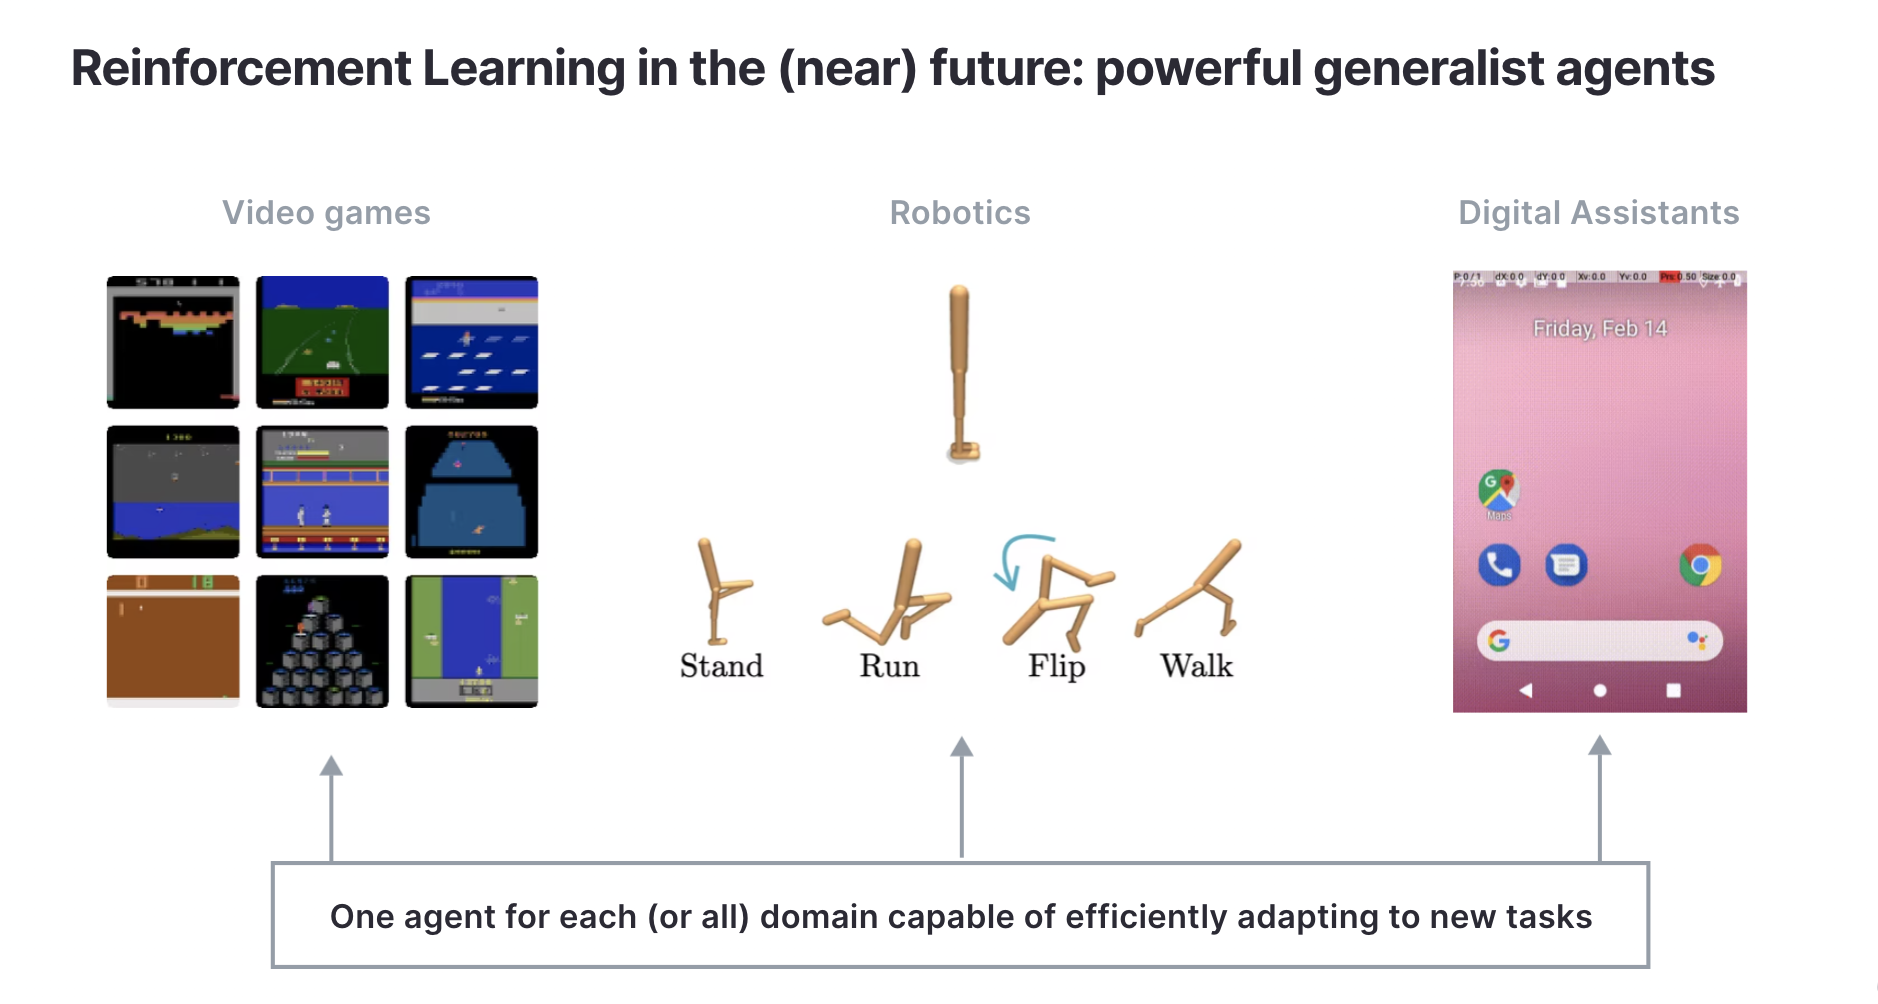
To this point, probably the most promising path towards generalist AI methods in language and imaginative and prescient has been by means of unsupervised pre-training. Masked informal and bi-directional transformers have emerged as scalable strategies for pre-training language fashions which have proven unprecedented generalization capabilities. Siamese architectures and extra not too long ago masked auto-encoders have additionally develop into state-of-the-art strategies for reaching quick downstream process adaptation in imaginative and prescient.
If we consider that pre-training is a strong method in direction of growing generalist AI brokers, then it’s pure to ask whether or not there exist self-supervised goals that will enable us to pre-train RL brokers. Not like imaginative and prescient and language fashions which act on static information, RL algorithms actively affect their very own information distribution. Like in imaginative and prescient and language, illustration studying is a vital side for RL as properly however the unsupervised downside that’s distinctive to RL is how brokers can themselves generate fascinating and various information trough self-supervised goals. That is the unsupervised RL downside – how will we be taught helpful behaviors with out supervision after which adapt them to resolve downstream duties rapidly?
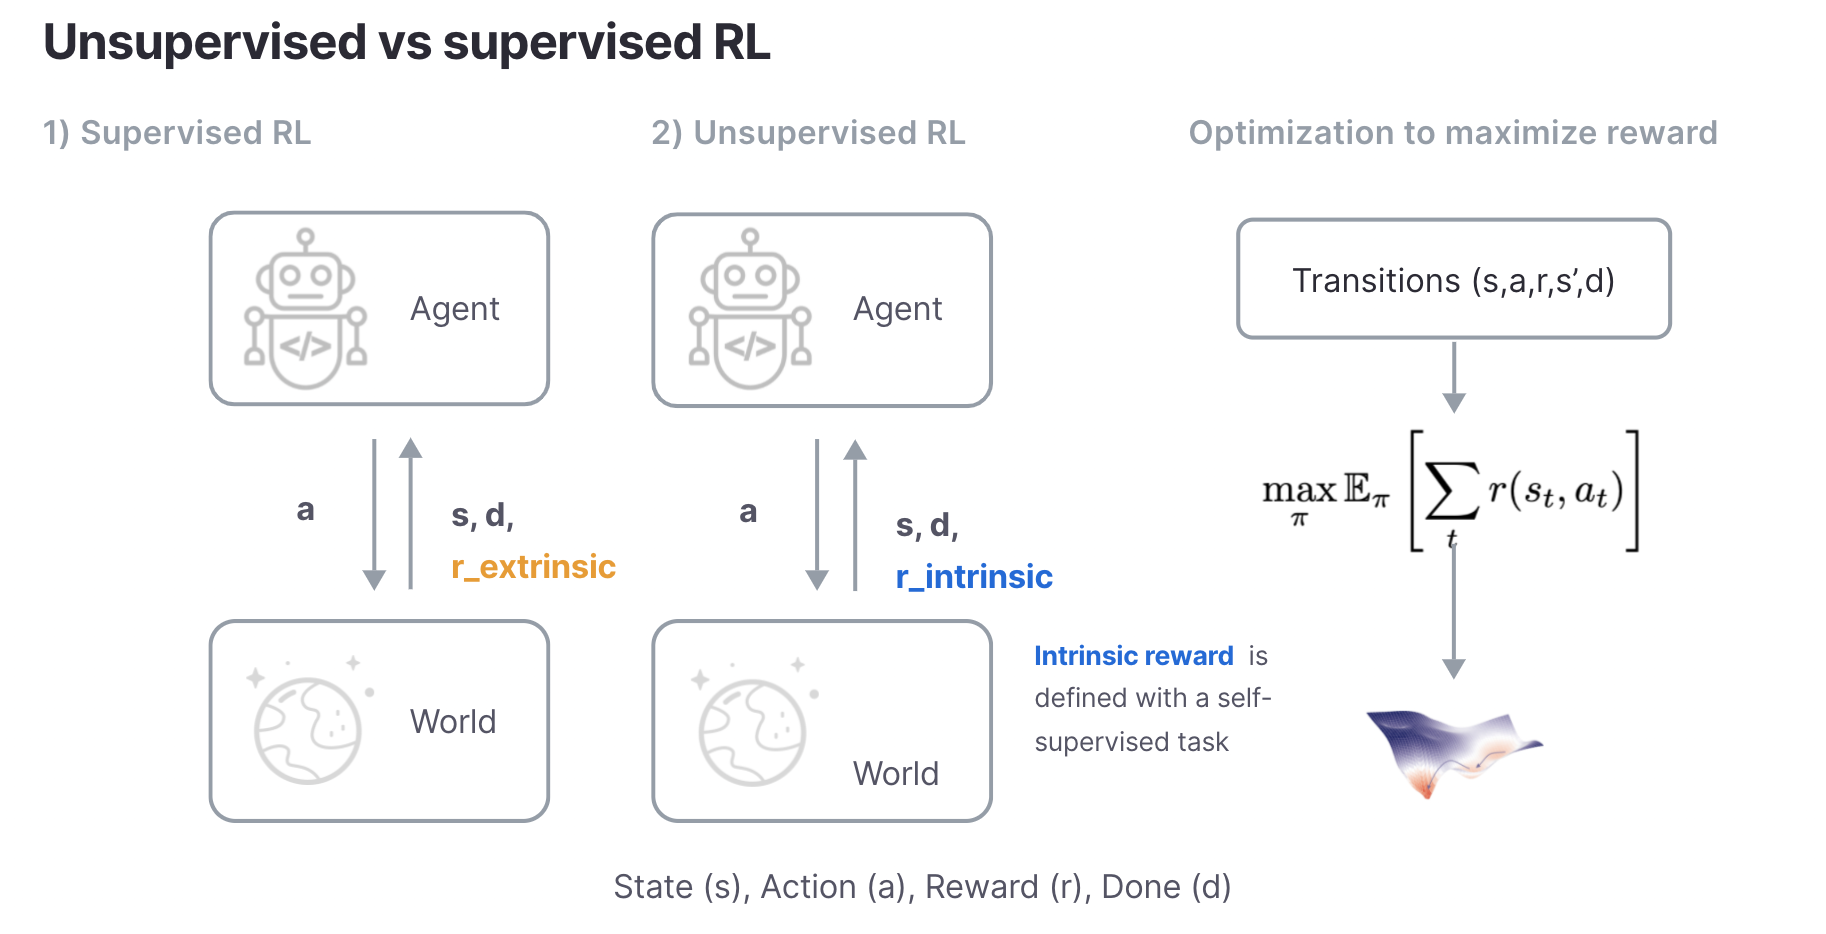
Unsupervised RL is similar to supervised RL. Each assume that the underlying setting is described by a Markov Determination Course of (MDP) or a Partially Noticed MDP, and each intention to maximise rewards. The primary distinction is that supervised RL assumes that supervision is offered by the setting by means of an extrinsic reward whereas unsupervised RL defines an intrinsic reward by means of a self-supervised process. Like supervision in NLP and imaginative and prescient, supervised rewards are both engineered or offered as labels by human operators that are exhausting to scale and restrict the generalization of RL algorithms to particular duties.
On the Robotic Studying Lab (RLL), we’ve been taking steps towards making unsupervised RL a believable method towards growing RL brokers able to generalization. To this finish, we developed and launched a benchmark for unsupervised RL with open-sourced PyTorch code for 8 main or fashionable baselines.
The Unsupervised Reinforcement Studying Benchmark (URLB)
Whereas quite a lot of unsupervised RL algorithms have been proposed over the previous few years, it has been unattainable to match them pretty attributable to variations in analysis, environments, and optimization. Because of this, we constructed URLB which supplies standardized analysis procedures, domains, downstream duties, and optimization for unsupervised RL algorithms
URLB splits coaching into two phases – an extended unsupervised pre-training section adopted by a brief supervised fine-tuning section. The preliminary launch consists of three domains with 4 duties every for a complete of twelve downstream duties for analysis.
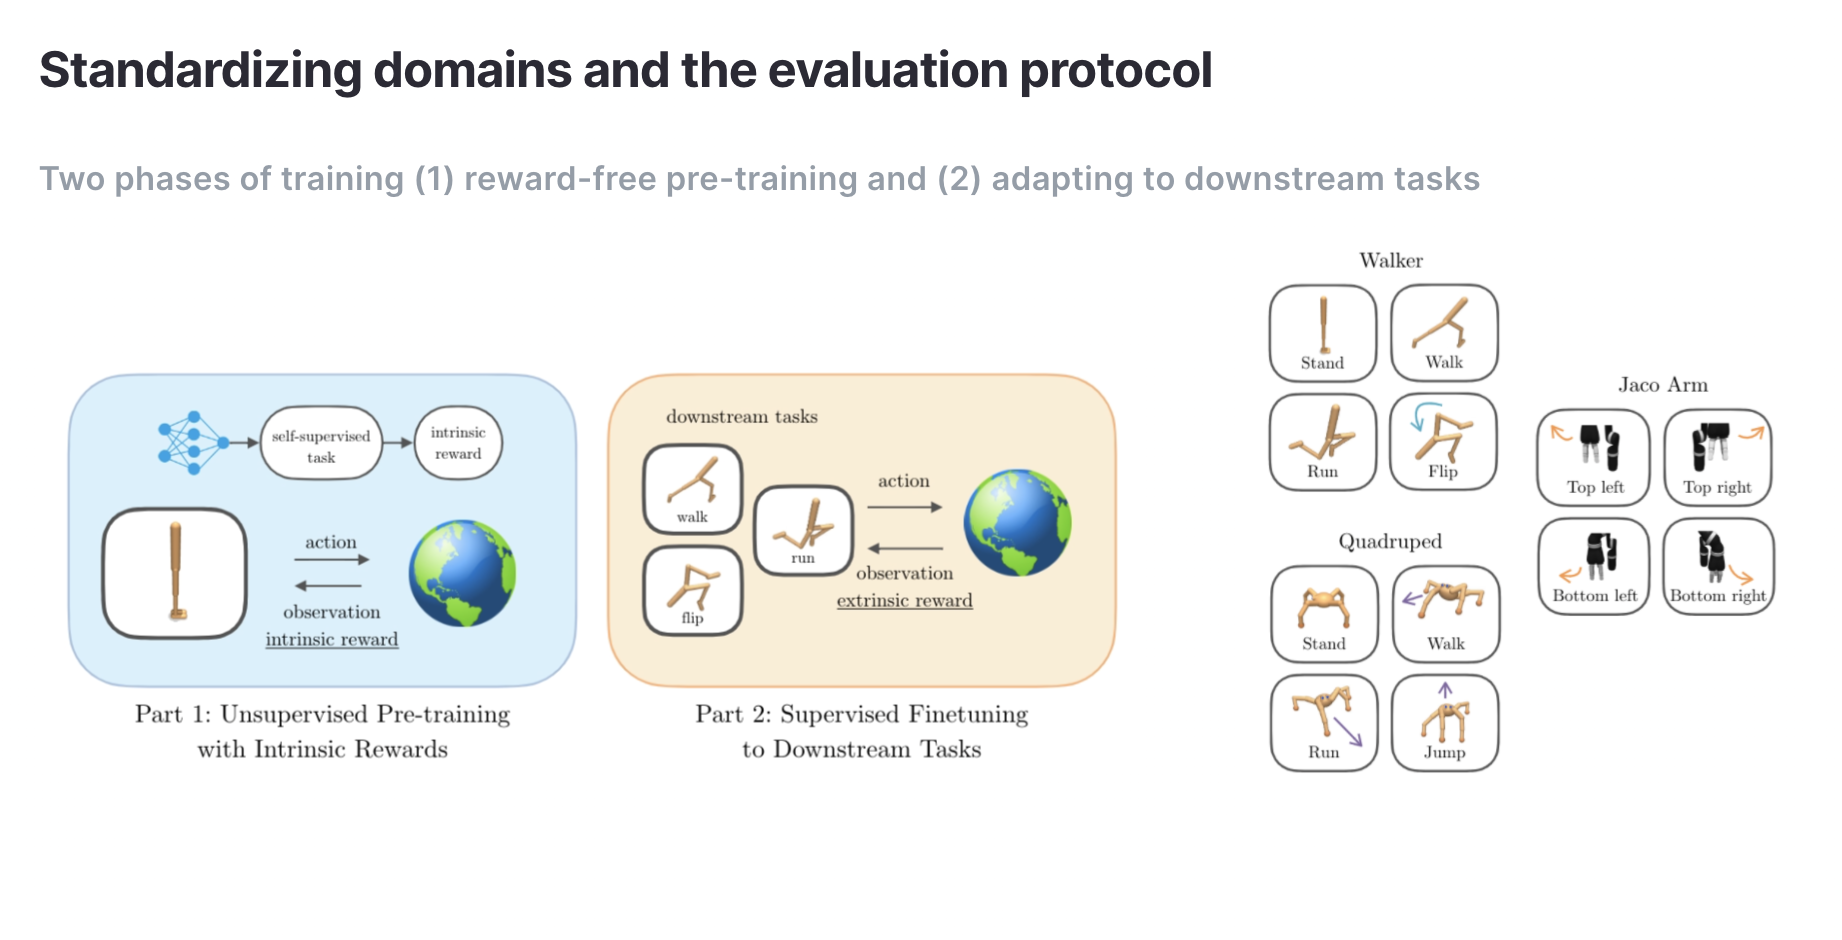
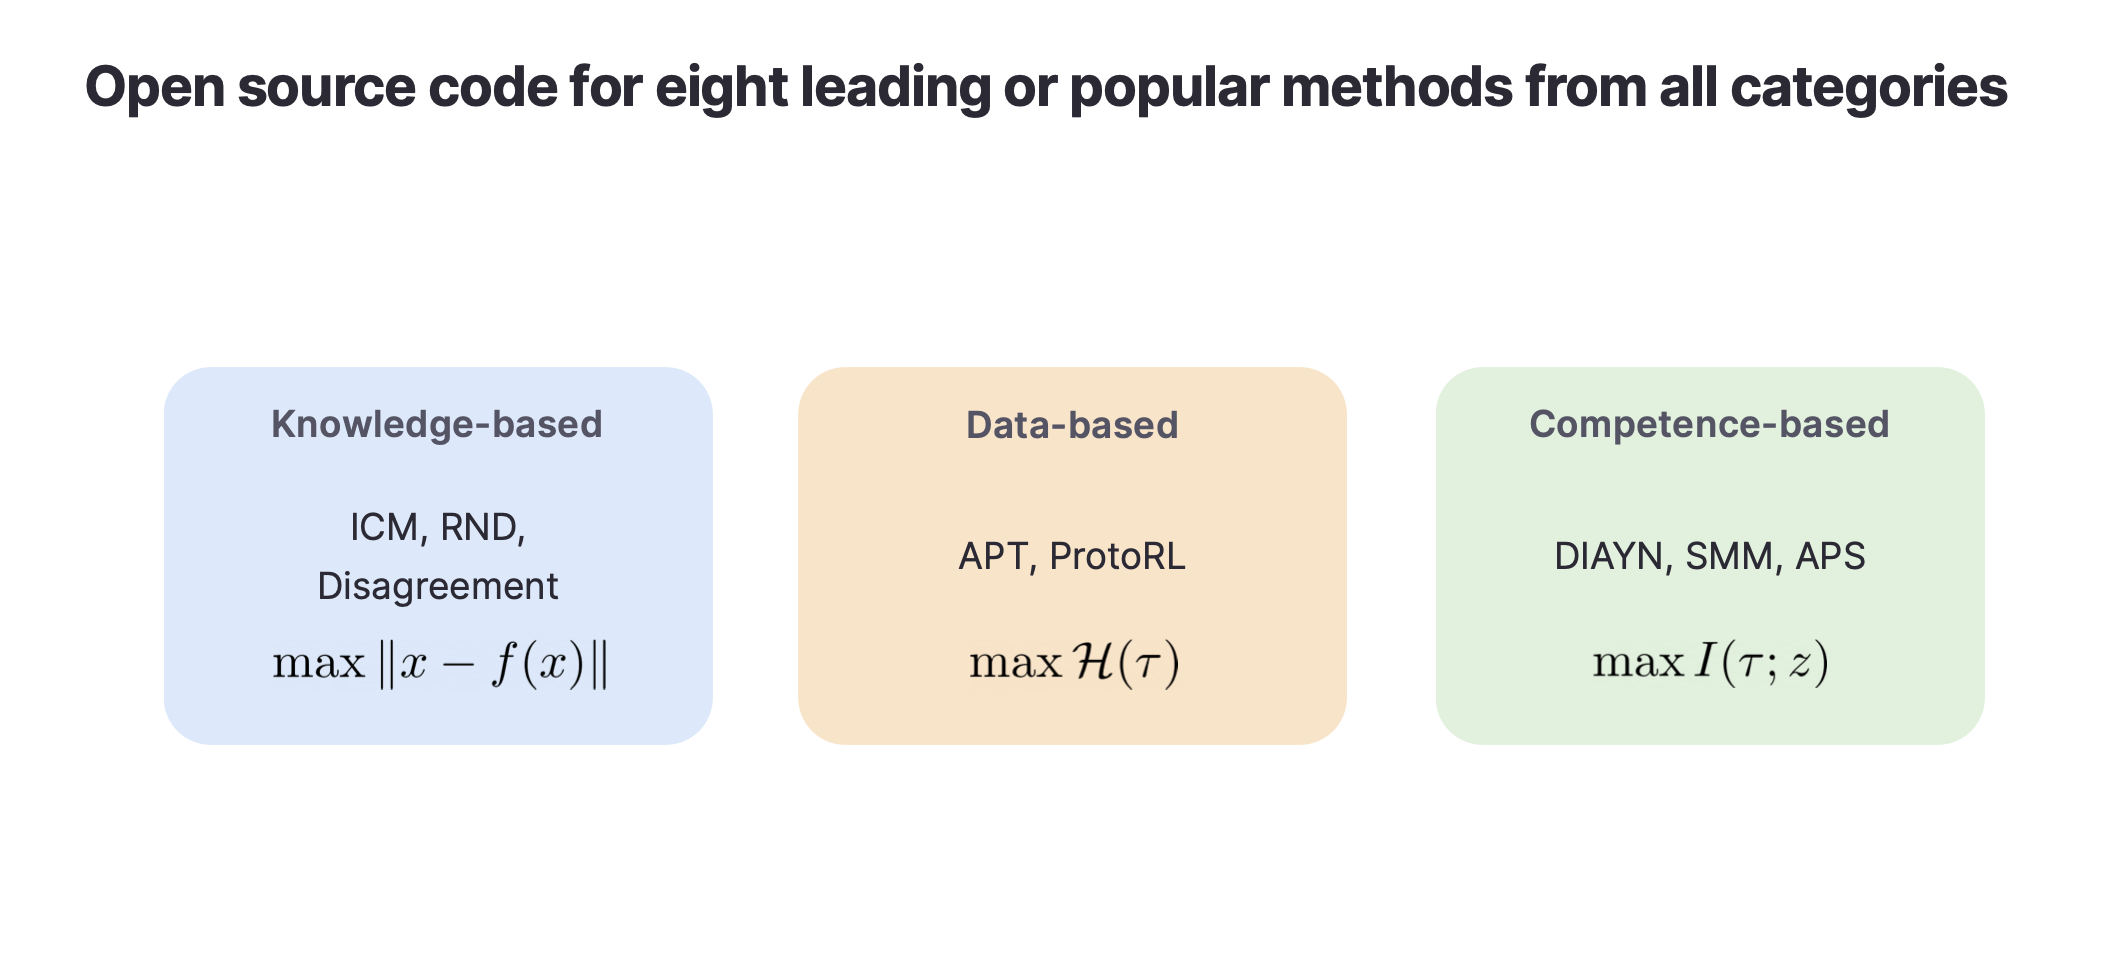
Most unsupervised RL algorithms identified so far could be categorized into three classes – knowledge-based, data-based, and competence-based. Information-based strategies maximize the prediction error or uncertainty of a predictive mannequin (e.g. Curiosity, Disagreement, RND), data-based strategies maximize the range of noticed information (e.g. APT, ProtoRL), competence-based strategies maximize the mutual data between states and a few latent vector sometimes called the “ability” or “process” vector (e.g. DIAYN, SMM, APS).
Beforehand these algorithms had been applied utilizing totally different optimization algorithms (Rainbow DQN, DDPG, PPO, SAC, and so forth). Because of this, unsupervised RL algorithms have been exhausting to match. In our implementations we standardize the optimization algorithm such that the one distinction between numerous baselines is the self-supervised goal.
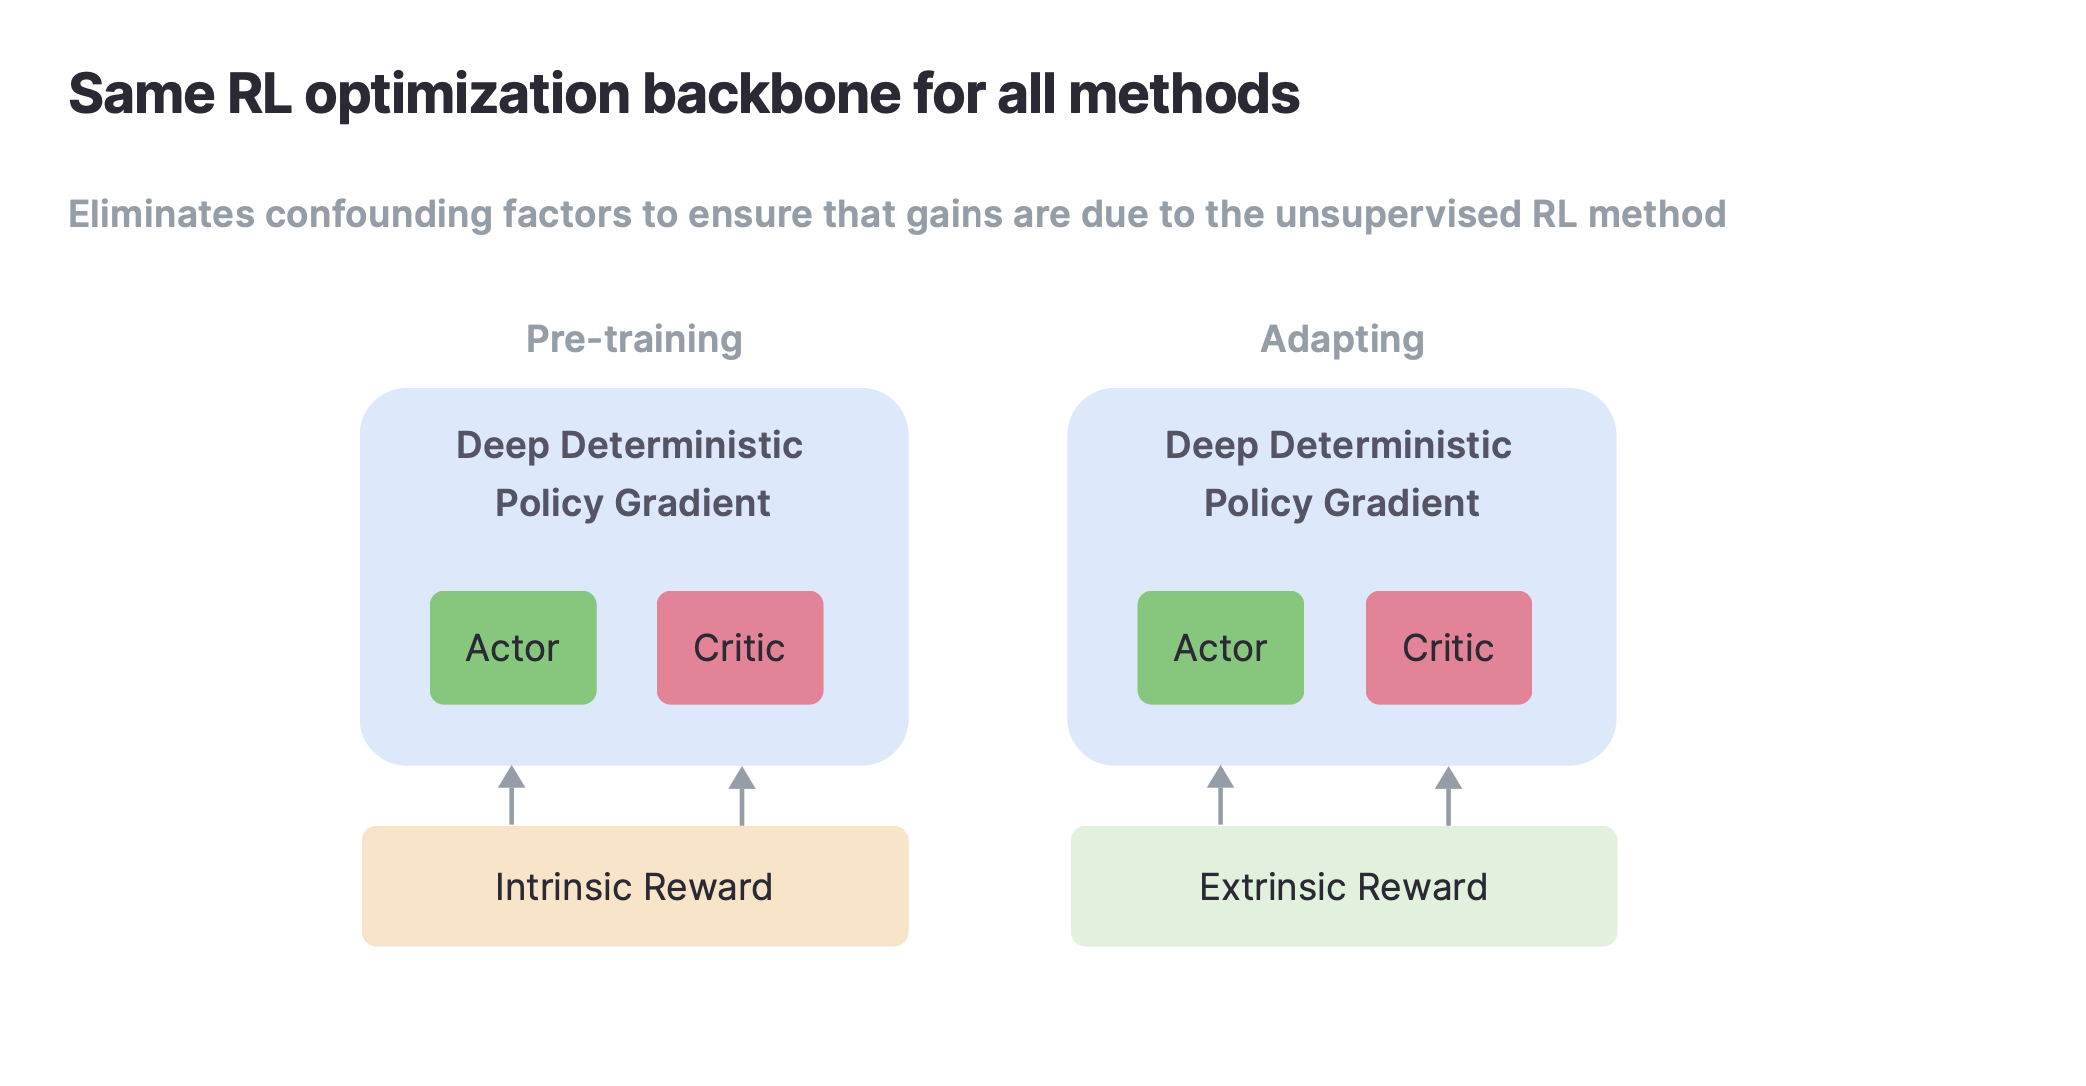
We applied and launched code for eight main algorithms supporting each state and pixel-based observations on domains based mostly on the DeepMind Management Suite.
By standardizing domains, analysis, and optimization throughout all applied baselines in URLB, the result’s a primary direct and truthful comparability between these three several types of algorithms.
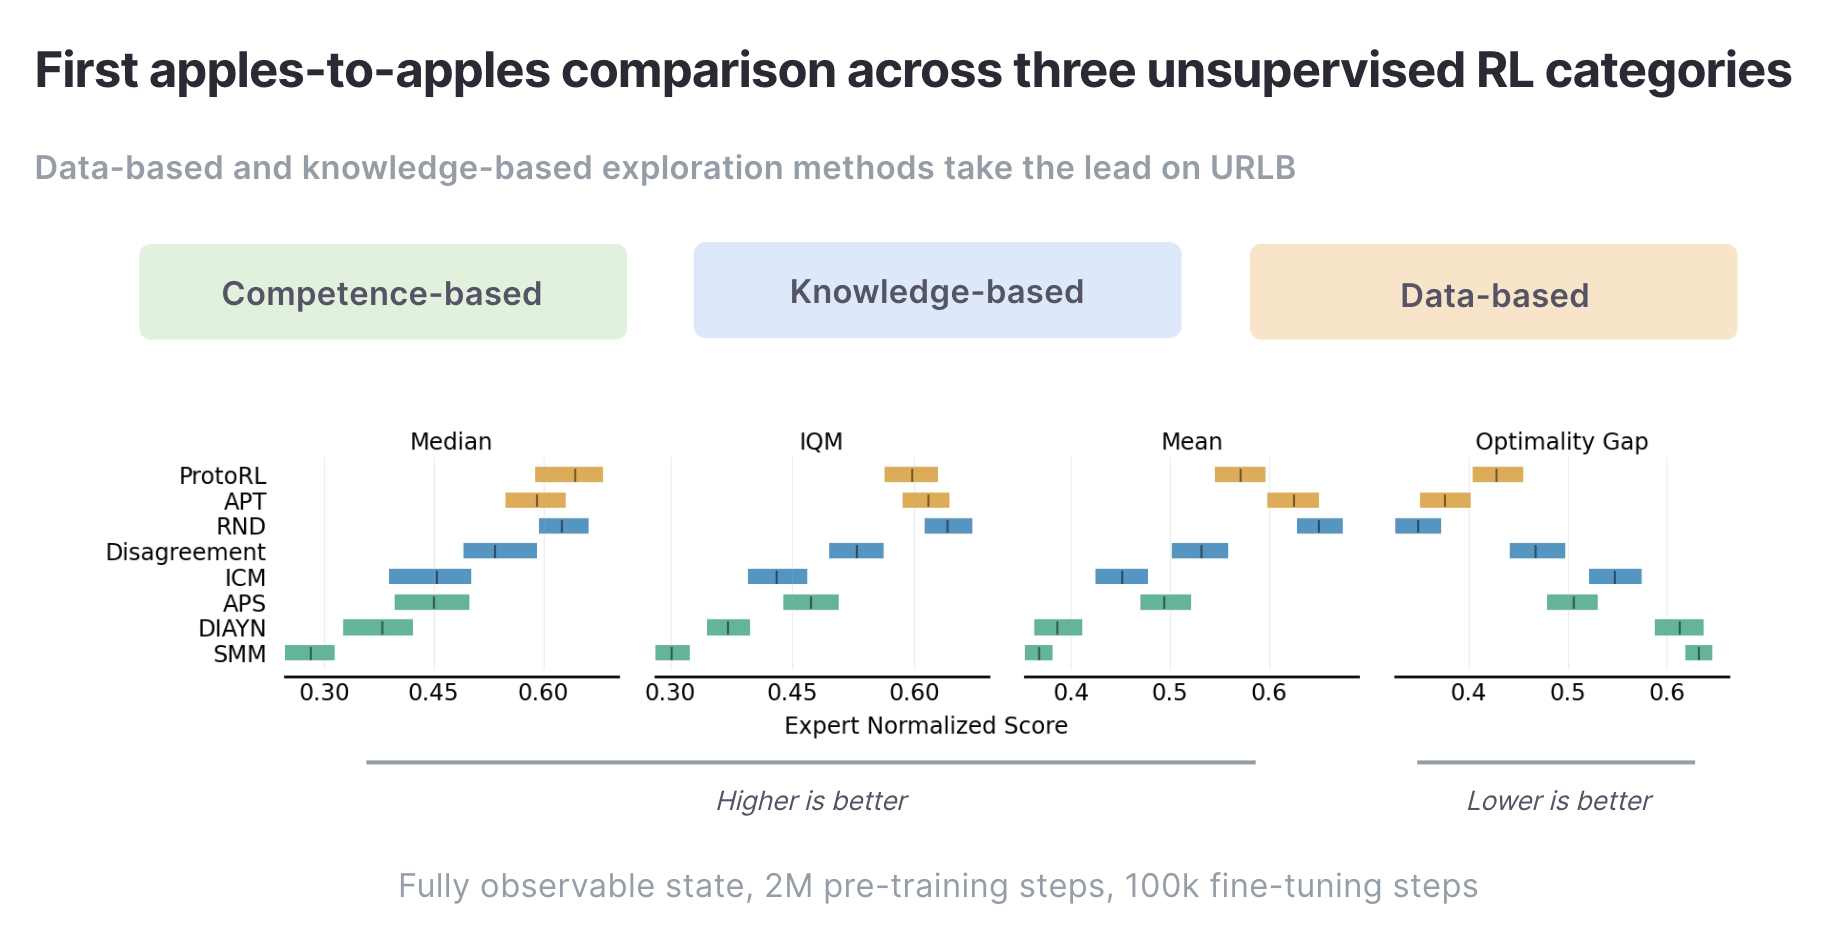
Above, we present mixture statistics of fine-tuning runs throughout all 12 downstream duties with 10 seeds every after pre-training on the goal area for 2M steps. We discover that at present data-based strategies (APT, ProtoRL) and RND are the main approaches on URLB.
We’ve additionally recognized a variety of promising instructions for future analysis based mostly on benchmarking present strategies. For instance, competence-based exploration as an entire underperforms information and knowledge-based exploration. Understanding why that is the case is an fascinating line for additional analysis. For added insights and instructions for future analysis in unsupervised RL, we refer the reader to the URLB paper.
Unsupervised RL is a promising path towards growing generalist RL brokers. We’ve launched a benchmark (URLB) for evaluating the efficiency of such brokers. We’ve open-sourced code for each URLB and hope this permits different researchers to rapidly prototype and consider unsupervised RL algorithms.
Hyperlinks
Paper: URLB: Unsupervised Reinforcement Studying Benchmark
Michael Laskin*, Denis Yarats*, Hao Liu, Kimin Lee, Albert Zhan, Kevin Lu, Catherine Cang, Lerrel Pinto, Pieter Abbeel, NeurIPS, 2021, these authors contributed equally
[ad_2]

