



[ad_1]
Scaling neural networks, whether or not or not it’s the quantity of coaching knowledge used, the mannequin dimension or the computation being utilized, has been important for enhancing mannequin high quality in lots of real-world machine studying functions, reminiscent of laptop imaginative and prescient, language understanding and neural machine translation. This, in flip, has motivated current research to scrutinize the elements that play a important position within the success of scaling a neural mannequin. Though rising mannequin capability generally is a sound method to enhance mannequin high quality, doing so presents various methods and software program engineering challenges that have to be overcome. For example, so as to prepare massive fashions that exceed the reminiscence capability of an accelerator, it turns into essential to partition the weights and the computation of the mannequin throughout a number of accelerators. This technique of parallelization will increase the community communication overhead and may end up in machine under-utilization. Furthermore, a given algorithm for parallelization, which generally requires a big quantity of engineering effort, could not work with totally different mannequin architectures.
To handle these scaling challenges, we current “GSPMD: Common and Scalable Parallelization for ML Computation Graphs”, by which we describe an open-source automated parallelization system based mostly on the XLA compiler. GSPMD is able to scaling most deep studying community architectures and has already been utilized to many deep studying fashions, reminiscent of GShard-M4, LaMDA, BigSSL, ViT, and MetNet-2, resulting in state-of-the-art-results throughout a number of domains. GSPMD has additionally been built-in into a number of ML frameworks, together with TensorFlow and JAX, which use XLA as a shared compiler.
Overview
GSPMD separates the duty of programming an ML mannequin from the problem of parallelization. It permits mannequin builders to jot down packages as in the event that they had been run on a single machine with very excessive reminiscence and computation capability — the consumer merely wants so as to add just a few traces of annotation code to a subset of important tensors within the mannequin code to point methods to partition the tensors. For instance, to coach a big model-parallel Transformer, one could solely have to annotate fewer than 10 tensors (lower than 1% of all tensors in all the computation graph), one line of extra code per tensor. Then GSPMD runs a compiler go that determines all the graph’s parallelization plan, and transforms it right into a mathematically equal, parallelized computation that may be executed on every machine. This permits customers to give attention to mannequin constructing as an alternative of parallelization implementation, and permits straightforward porting of current single-device packages to run at a a lot bigger scale.
The separation of mannequin programming and parallelism additionally permits builders to reduce code duplication. With GSPMD, builders could make use of totally different parallelism algorithms for various use circumstances with out the necessity to reimplement the mannequin. For instance, the mannequin code that powered the GShard-M4 and LaMDA fashions can apply a wide range of parallelization methods applicable for various fashions and cluster sizes with the identical mannequin implementation. Equally, by making use of GSPMD, the BigSSL massive speech fashions can share the identical implementation with earlier smaller fashions.
Generality and Flexibility
As a result of totally different mannequin architectures could also be higher suited to totally different parallelization methods, GSPMD is designed to assist a big number of parallelism algorithms applicable for various use circumstances. For instance, with smaller fashions that match inside the reminiscence of a single accelerator, knowledge parallelism is most well-liked, by which units prepare the identical mannequin utilizing totally different enter knowledge. In distinction, fashions which might be bigger than a single accelerator’s reminiscence capability are higher suited to a pipelining algorithm (like that employed by GPipe) that partitions the mannequin into a number of, sequential levels, or operator-level parallelism (e.g., Mesh-TensorFlow), by which particular person computation operators within the mannequin are cut up into smaller, parallel operators.
GSPMD helps all of the above parallelization algorithms with a uniform abstraction and implementation. Furthermore, GSPMD helps nested patterns of parallelism. For instance, it may be used to partition fashions into particular person pipeline levels, every of which might be additional partitioned utilizing operator-level parallelism.
GSPMD additionally facilitates innovation on parallelism algorithms by permitting efficiency specialists to give attention to algorithms that greatest make the most of the {hardware}, as an alternative of the implementation that entails plenty of cross-device communications. For instance, for giant Transformer fashions, we discovered a novel operator-level parallelism algorithm that partitions a number of dimensions of tensors on a 2D mesh of units. It reduces peak accelerator reminiscence utilization linearly with the variety of coaching units, whereas sustaining a excessive utilization of accelerator compute on account of its balanced knowledge distribution over a number of dimensions.
As an example this, take into account a simplified feedforward layer in a Transformer mannequin that has been annotated within the above means. To execute the primary matrix multiply on totally partitioned enter knowledge, GSPMD applies an MPI-style AllGather communication operator to partially merge with partitioned knowledge from one other machine. It then executes the matrix multiply domestically and produces a partitioned consequence. Earlier than the second matrix multiply, GSPMD provides one other AllGather on the right-hand facet enter, and executes the matrix multiply domestically, yielding intermediate outcomes that may then should be mixed and partitioned. For this, GSPMD provides an MPI-style ReduceScatter communication operator that accumulates and partitions these intermediate outcomes. Whereas the tensors generated with the AllGather operator at every stage are bigger than the unique partition dimension, they’re short-lived and the corresponding reminiscence buffers shall be freed after use, which doesn’t have an effect on peak reminiscence utilization in coaching.
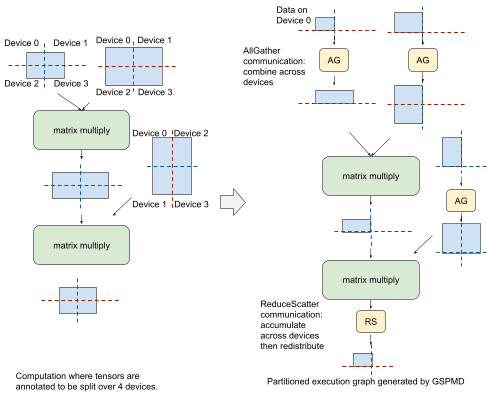 |
| Left: A simplified feedforward layer of a Transformer mannequin. Blue rectangles symbolize tensors with dashed purple & blue traces overlaid representing the specified partitioning throughout a 2×2 mesh of units. Proper: A single partition, after GSPMD has been utilized. |
A Transformer Instance with Nested Parallelism
As a shared, strong mechanism for various parallelism modes, GSPMD permits customers to conveniently change between modes in numerous components of a mannequin. That is notably priceless for fashions that will have totally different elements with distinct efficiency traits, for instance, multimodal fashions that deal with each pictures and audio. Take into account a mannequin with the Transformer encoder-decoder structure, which has an embedding layer, an encoder stack with Combination-of-Professional layers, a decoder stack with dense feedforward layers, and a closing softmax layer. In GSPMD, a posh mixture of a number of parallelism modes that treats every layer individually might be achieved with easy configurations.
Within the determine under, we present a partitioning technique over 16 units organized as a logical 4×4 mesh. Blue represents partitioning alongside the primary mesh dimension X, and yellow represents partitioning alongside the second mesh dimension Y. X and Y are repurposed for various mannequin elements to realize totally different parallelism modes. For instance, the X dimension is used for knowledge parallelism within the embedding and softmax layers, however used for pipeline parallelism within the encoder and decoder. The Y dimension can also be utilized in other ways to partition the vocabulary, batch or mannequin professional dimensions.
 |
Computation Effectivity
GSPMD gives industry-leading efficiency in massive mannequin coaching. Parallel fashions require further communication to coordinate a number of units to do the computation. So parallel mannequin effectivity might be estimated by inspecting the fraction of time spent on communication overhead — the upper share utilization and the much less time spent on communication, the higher. Within the current MLPerf set of efficiency benchmarks, a BERT-like encoder-only mannequin with ~500 billion parameters to which we utilized GSPMD for parallelization over 2048 TPU-V4 chips yielded extremely aggressive outcomes (see desk under), using as much as 63% of the height FLOPS that the TPU-V4s supply. We additionally present effectivity benchmarks for some consultant massive fashions within the desk under. These instance mannequin configs are open sourced within the Lingvo framework together with directions to run them on Google Cloud. Extra benchmark outcomes might be discovered within the experiment part of our paper.
| Mannequin Household | Parameter Depend | % of mannequin activated* | No. of Specialists** | No. of Layers | No. of TPU | FLOPS utilization |
| Dense Decoder (LaMDA) | 137B | 100% | 1 | 64 | 1024 TPUv3 | 56.5% |
| Dense Encoder (MLPerf-Bert) | 480B | 100% | 1 | 64 | 2048 TPUv4 | 63% |
| Sparsely Activated Encoder-Decoder (GShard-M4) | 577B | 0.25% | 2048 | 32 | 1024 TPUv3 | 46.8% |
| Sparsely Activated Decoder | 1.2T | 8% | 64 | 64 | 1024 TPUv3 | 53.8% |
| *The fraction of the mannequin activated throughout inference, which is a measure of mannequin sparsity. **Variety of specialists included within the Combination of Specialists layer. A price of 1 corresponds to a regular Transformer, with out a Combination of Specialists layer. |
Conclusion
The continued improvement and success of many helpful machine studying functions, reminiscent of NLP, speech recognition, machine translation, and autonomous driving, depend upon reaching the best accuracy doable. As this typically requires constructing bigger and much more complicated fashions, we’re happy to share the GSPMD paper and the corresponding open-source library to the broader analysis group, and we hope it’s helpful for environment friendly coaching of large-scale deep neural networks.
Acknowledgements
We want to thank Claire Cui, Zhifeng Chen, Yonghui Wu, Naveen Kumar, Macduff Hughes, Zoubin Ghahramani and Jeff Dean for his or her assist and invaluable enter. Particular because of our collaborators Dmitry Lepikhin, HyoukJoong Lee, Dehao Chen, Orhan Firat, Maxim Krikun, Blake Hechtman, Rahul Joshi, Andy Li, Tao Wang, Marcello Maggioni, David Majnemer, Noam Shazeer, Ankur Bapna, Sneha Kudugunta, Quoc Le, Mia Chen, Shibo Wang, Jinliang Wei, Ruoming Pang, Zongwei Zhou, David So, Yanqi Zhou, Ben Lee, Jonathan Shen, James Qin, Yu Zhang, Wei Han, Anmol Gulati, Laurent El Shafey, Andrew Dai, Kun Zhang, Nan Du, James Bradbury, Matthew Johnson, Anselm Levskaya, Skye Wanderman-Milne, and Qiao Zhang for useful discussions and inspirations.
[ad_2]

