



[ad_1]
The issue with inventing human faces with a Generative Adversarial Community (GAN) is that the real-world knowledge that fuels the pretend photographs comes with unwelcome and inseparable accoutrements, akin to hair on the top (and/or face), backgrounds, and varied sorts of face furnishings, akin to glasses, hats, and ear-rings; and that these peripheral facets of character inevitably turn into certain up in a ‘fused’ id.
Beneath the most typical GAN architectures, these components aren’t addressable in their very own devoted area, however reasonably are fairly tightly related to the face in (or round) which they’re embedded.
Neither is it often potential to dictate or have an effect on the looks of sub-sections of a face created by a GAN, akin to narrowing the eyes, lengthening the nostril, or altering hair-color in the best way {that a} police sketch artist might.
Nonetheless, the picture synthesis analysis sector is engaged on it:

New analysis into GAN-based face technology has separated the varied sections of a face into distinct areas, every with their very own ‘generator’, working in live performance with different mills for the picture. Within the center row, we see the orchestrating ‘function map’ increase further areas of the face. Supply: https://arxiv.org/pdf/2112.02236.pdf
In a brand new paper, researchers from the US arm of Chinese language multinational tech big ByteDance have used semantic segmentation to interrupt up the constituent elements of the face into discrete sections, every of which is allotted its personal generator, in order that it’s potential to realize a better diploma of disentanglement. Or, at the least, perceptual disentanglement.
The paper is titled SemanticStyleGAN: Studying Compositional Generative Priors for Controllable Picture Synthesis and Enhancing, and is accompanied by a media-rich undertaking web page that includes a number of examples of the varied fine-grained transformations that may be achieved when facial and head components are remoted on this method.
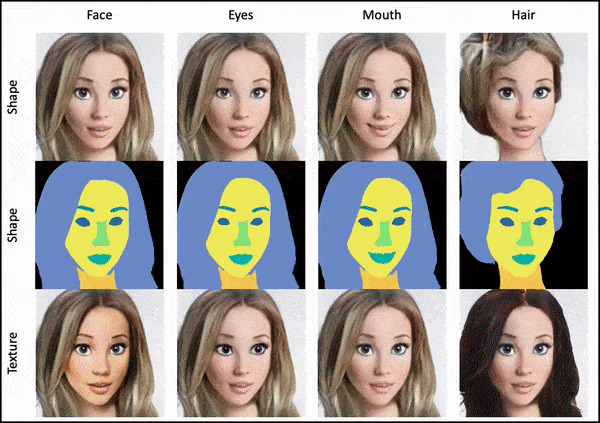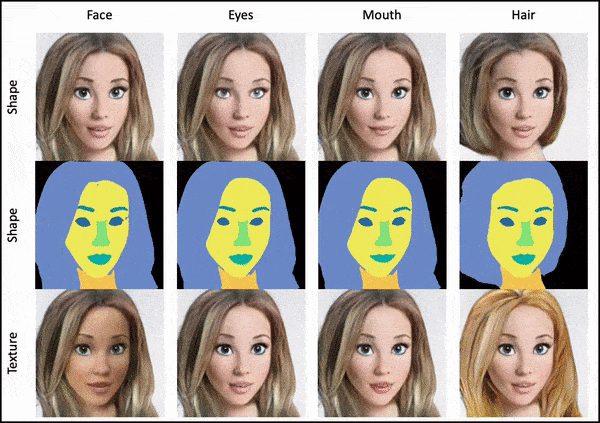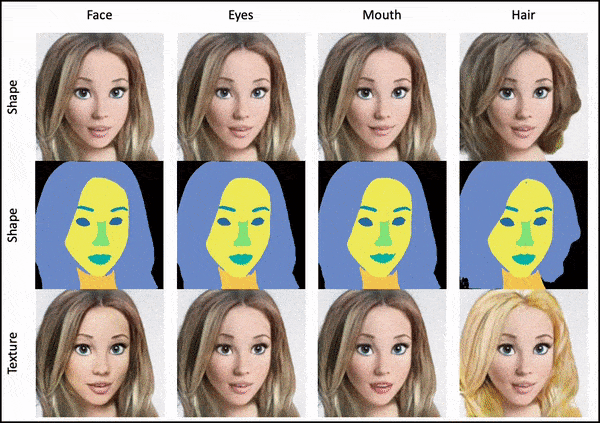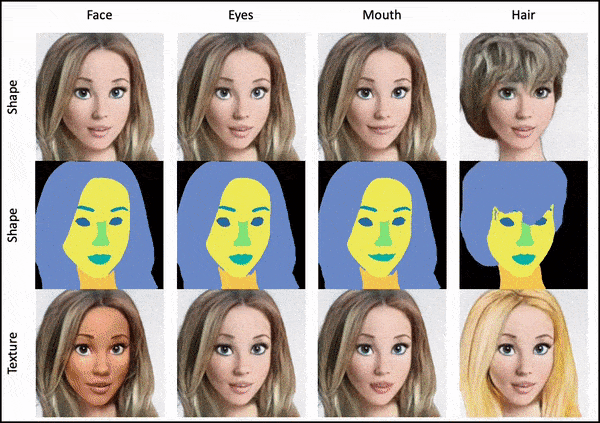
Facial texture, hair color and style, eye form and colour, and plenty of different facets of once-indissoluble GAN-generated options can now be de facto disentangled, although the standard of separation and degree of instrumentality is prone to fluctuate throughout instances. Supply: https://semanticstylegan.github.io/
The Ungovernable Latent House
A Generative Adversarial Community skilled to generate faces – such because the StyleGan2 generator that powers the favored web site thispersondoesnotexist.com – kinds complicated interrelationships between the ‘options’ (not within the facial sense) that it derives from analyzing hundreds of real-world faces, to be able to discover ways to make lifelike human faces itself.
These clandestine processes are ‘latent codes’, collectively the latent area. They’re tough to research, and consequently tough to instrumentalize.
Final week a unique new picture synthesis undertaking emerged that makes an attempt to ‘map’ this near-occult area in the course of the coaching course of itself, after which to use these maps to interactively navigate it, and varied different options have been proposed to achieve deeper management of GAN-synthesized content material.
Some progress has been made, with a various providing of GAN architectures that try and ‘attain into’ the latent area not directly and management the facial generations from there. Such efforts embody InterFaceGAN, StyleFlow, GANSpace, and StyleRig, amongst different choices in a constantly-productive stream of latest papers.
What all of them have in frequent is proscribed levels of disentanglement; the ingenious GUI sliders for varied aspects (akin to ‘hair’ or ‘expression’) have a tendency to pull the background and/or different components into the transformation course of, and none of them (together with the paper mentioned right here) have solved the issue of temporal neural hair.
Dividing and Conquering the Latent House
In any case, the ByteDance analysis takes a unique method: as a substitute of making an attempt to discern the mysteries of a single GAN working over a whole generated face picture, SemanticStyleGAN formulates a layout-based method, the place faces are ‘composed’ by separate generator processes.
As a way to obtain this distinction of (facial) options, SemanticStyleGAN makes use of Fourier Options to generate a semantic segmentation map (crudely coloured distinctions of facial topography, proven in the direction of the lower-right of the picture beneath) to isolate the facial areas which is able to obtain particular person, devoted consideration.

Structure of the brand new method, which imposes an interstitial layer of semantic segmentation onto the face, successfully turning the framework into an orchestrator of a number of mills for various aspects of a picture.
The segmentation maps are generated for the pretend photographs which can be systematically offered to the GAN’s discriminator for analysis because the mannequin improves, and to the (non-fake) supply photographs used for coaching.
In the beginning of the method, a Multi-Layer Perceptron (MLP) initially maps randomly-chosen latent codes, which is able to then be used to manage the weights of the a number of mills that may every take management of a piece of the face picture to be produced.
Every generator creates a function map and a simulated depth-map from the Fourier options which can be fed to it upstream. This output is the premise for the segmentation masks.
The downstream render community is barely conditioned by the sooner function maps, and now is aware of how you can generate a higher-resolution segmentation masks, facilitating the ultimate manufacturing of the picture.
Lastly, a bifurcated discriminator oversees the concatenated distribution of each the RGB photographs (that are, for us, the ultimate end result) and the segmentation masks which have allowed them to be separated.
With SemanticStyleGAN, there aren’t any unwelcome visible perturbations when ‘dialing in’ facial function modifications, as a result of every facial function has been individually skilled throughout the orchestration framework.
Substituting Backgrounds
As a result of the intention of the undertaking is to achieve better management of the generated setting, the rendering/composition course of features a background generator skilled on actual photographs.

One compelling motive why the backgrounds don’t get dragged into facial manipulations in SemanticStyleGAN is that they’re sitting on a extra distant layer, and are full, if partially hidden by the superimposed faces.
For the reason that segmentation maps will end in faces with out backgrounds, these ‘drop-in’ backgrounds not solely present context, however are additionally configured to be apposite, when it comes to lighting, for the superimposed faces.
Coaching and Knowledge
The ‘lifelike’ fashions have been skilled on the preliminary 28,000 photographs in CelebAMask-HQ, resized to 256×256 pixels to accommodate the coaching area (i.e. the out there VRAM, which dictates a most batch dimension per iteration).
Various fashions have been skilled, and various instruments, datasets and architectures experimented with in the course of the growth course of and varied ablation assessments. The undertaking’s largest productive mannequin featured 512×512 decision, skilled over 2.5 days on eight NVIDIA Tesla V100 GPUs. After coaching, technology of a single picture takes 0.137s on a lobe GPU with out parallelization.
The extra cartoon/anime-style experiments demonstrated within the many movies on the undertaking’s web page (see hyperlink above) are derived from varied in style face-based datasets, together with Toonify, MetFaces, and Bitmoji.
A Stopgap Resolution?
The authors contend that there isn’t any motive why SemanticStyleGAN couldn’t be utilized to different domains, akin to landscapes, automobiles, church buildings, and all the opposite ‘default’ take a look at domains to which new architectures are routinely subjected early of their careers.
Nonetheless, the paper concedes that because the variety of courses rises for a website (akin to ‘automotive’, ‘street-lamp’, ‘pedestrian’, ‘constructing’, ‘automotive’ and so on.), this piecemeal method would possibly turn into unworkable in numerous methods, with out additional work on optimization. The CityScapes city dataset, as an example, has 30 courses throughout 8 classes.
It’s tough to say if present curiosity in conquering the latent area extra immediately is as doomed as alchemy; or whether or not latent codes will finally be decipherable and controllable – a growth that would render this extra ‘externally complicated’ kind of method redundant.
[ad_2]

