



[ad_1]
Transformer fashions persistently acquire state-of-the-art leads to pc imaginative and prescient duties, together with object detection and video classification. In distinction to straightforward convolutional approaches that course of photos pixel-by-pixel, the Imaginative and prescient Transformers (ViT) deal with a picture as a sequence of patch tokens (i.e., a smaller half, or “patch”, of a picture made up of a number of pixels). Because of this at each layer, a ViT mannequin recombines and processes patch tokens based mostly on relations between every pair of tokens, utilizing multi-head self-attention. In doing so, ViT fashions have the potential to assemble a worldwide illustration of your complete picture.
On the input-level, the tokens are fashioned by uniformly splitting the picture into a number of segments, e.g., splitting a picture that’s 512 by 512 pixels into patches which might be 16 by 16 pixels. On the intermediate ranges, the outputs from the earlier layer change into the tokens for the following layer. Within the case of movies, video ‘tubelets’ equivalent to 16x16x2 video segments (16×16 photos over 2 frames) change into tokens. The standard and amount of the visible tokens determine the general high quality of the Imaginative and prescient Transformer.
The principle problem in lots of Imaginative and prescient Transformer architectures is that they usually require too many tokens to acquire cheap outcomes. Even with 16×16 patch tokenization, as an example, a single 512×512 picture corresponds to 1024 tokens. For movies with a number of frames, that leads to tens of 1000’s of tokens needing to be processed at each layer. Contemplating that the Transformer computation will increase quadratically with the variety of tokens, this will usually make Transformers intractable for bigger photos and longer movies. This results in the query: is it actually essential to course of that many tokens at each layer?
In “TokenLearner: What Can 8 Discovered Tokens Do for Photos and Movies?”, an earlier model of which is introduced at NeurIPS 2021, we present that adaptively producing a smaller variety of tokens, quite than all the time counting on tokens fashioned by uniform splitting, allows Imaginative and prescient Transformers to run a lot sooner and carry out higher. TokenLearner is a learnable module that takes an image-like tensor (i.e., enter) and generates a small set of tokens. This module may very well be positioned at numerous totally different areas throughout the mannequin of curiosity, considerably lowering the variety of tokens to be dealt with in all subsequent layers. The experiments exhibit that having TokenLearner saves reminiscence and computation by half or extra with out damaging classification efficiency, and due to its potential to adapt to inputs, it even will increase the accuracy.
The TokenLearner
We implement TokenLearner utilizing a simple spatial consideration method. As a way to generate every discovered token, we compute a spatial consideration map highlighting regions-of-importance (utilizing convolutional layers or MLPs). Such a spatial consideration map is then utilized to the enter to weight every area in a different way (and discard pointless areas), and the result’s spatially pooled to generate the ultimate discovered tokens. That is repeated a number of instances in parallel, leading to a couple of (~10) tokens out of the unique enter. This can be considered as performing a soft-selection of the pixels based mostly on the load values, adopted by international common pooling. Word that the capabilities to compute the eye maps are ruled by totally different units of learnable parameters, and are educated in an end-to-end style. This permits the eye capabilities to be optimized in capturing totally different spatial info within the enter. The determine beneath illustrates the method.
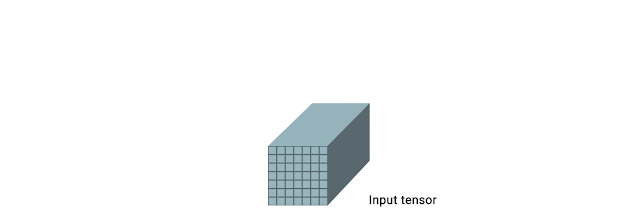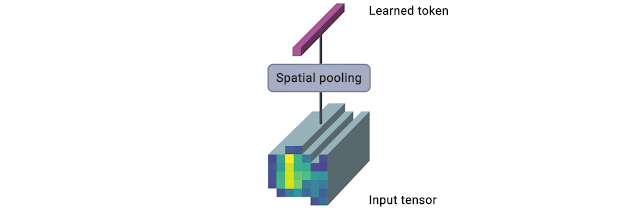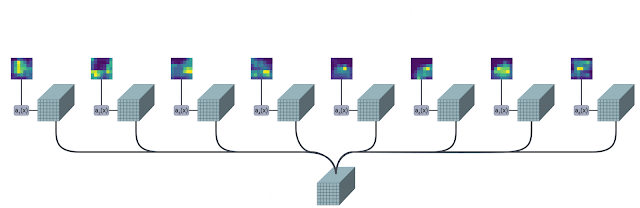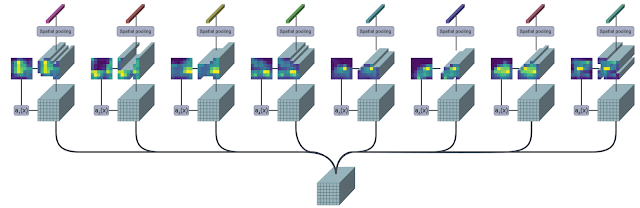 |
| The TokenLearner module learns to generate a spatial consideration map for every output token, and makes use of it to summary the enter to tokenize. In observe, a number of spatial consideration capabilities are discovered, are utilized to the enter, and generate totally different token vectors in parallel. |
Consequently, as a substitute of processing mounted, uniformly tokenized inputs, TokenLearner allows fashions to course of a smaller variety of tokens which might be related to the particular recognition process. That’s, (1) we allow adaptive tokenization in order that the tokens could be dynamically chosen conditioned on the enter, and (2) this successfully reduces the whole variety of tokens, tremendously lowering the computation carried out by the community. These dynamically and adaptively generated tokens can be utilized in customary transformer architectures equivalent to ViT for photos and ViViT for movies.
The place to Place TokenLearner
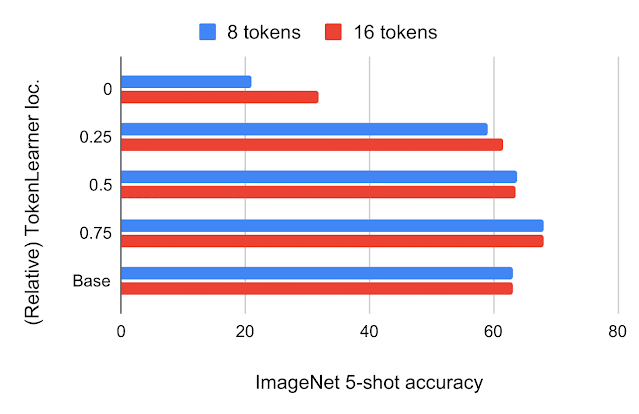
After constructing the TokenLearner module, we needed to decide the place to position it. We first tried inserting it at totally different areas inside the usual ViT structure with 224×224 photos. The variety of tokens TokenLearner generated was 8 and 16, a lot lower than 196 or 576 tokens the usual ViTs use. The beneath determine reveals ImageNet few-shot classification accuracies and FLOPS of the fashions with TokenLearner inserted at numerous relative areas inside ViT B/16, which is the bottom mannequin with 12 consideration layers working on 16×16 patch tokens.
 |
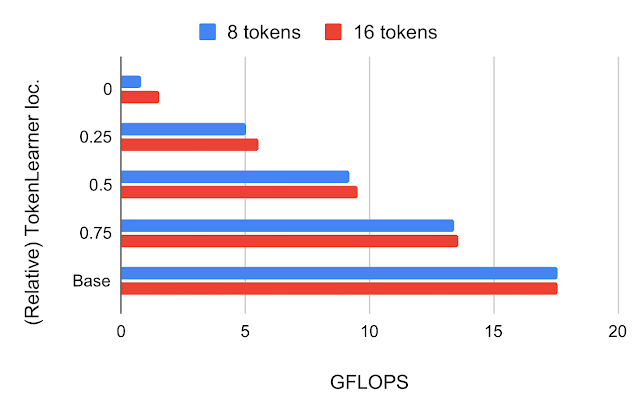 |
| High: ImageNet 5-shot switch accuracy with JFT 300M pre-training, with respect to the relative TokenLearner areas inside ViT B/16. Location 0 means TokenLearner is positioned earlier than any Transformer layer. Base is the unique ViT B/16. Backside: Computation, measured by way of billions of floating level operations (GFLOPS), per relative TokenLearner location. |
We discovered that inserting TokenLearner after the preliminary quarter of the community (at 1/4) achieves virtually similar accuracies because the baseline, whereas lowering the computation to lower than a 3rd of the baseline. As well as, inserting TokenLearner on the later layer (after 3/4 of the community) achieves even higher efficiency in comparison with not utilizing TokenLearner whereas performing sooner, because of its adaptiveness. Because of the massive distinction between the variety of tokens earlier than and after TokenLearner (e.g., 196 earlier than and eight after), the relative computation of the transformers after the TokenLearner module turns into virtually negligible.
Evaluating In opposition to ViTs
We in contrast the usual ViT fashions with TokenLearner towards these with out it whereas following the identical setting on ImageNet few-shot switch. TokenLearner was positioned in the course of every ViT mannequin at numerous areas equivalent to at 1/2 and at 3/4. The beneath determine reveals the efficiency/computation trade-off of the fashions with and with out TokenLearner.
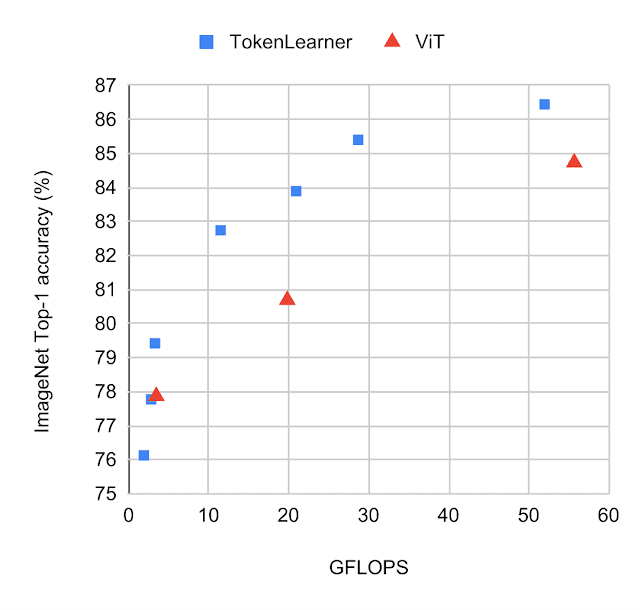 |
| Efficiency of varied variations of ViT fashions with and with out TokenLearner, on ImageNet classification. The fashions had been pre-trained with JFT 300M. The nearer a mannequin is to the top-left of every graph the higher, which means that it runs sooner and performs higher. Observe how TokenLearner fashions carry out higher than ViT by way of each accuracy and computation. |
We additionally inserted TokenLearner inside bigger ViT fashions, and in contrast them towards the enormous ViT G/14 mannequin. Right here, we utilized TokenLearner to ViT L/10 and L/8, that are the ViT fashions with 24 consideration layers taking 10×10 (or 8×8) patches as preliminary tokens. The beneath determine reveals that regardless of utilizing many fewer parameters and fewer computation, TokenLearner performs comparably to the enormous G/14 mannequin with 48 layers.
 |
 |
| Left: Classification accuracy of large-scale TokenLearner fashions in comparison with ViT G/14 on ImageNet datasets. Proper: Comparability of the variety of parameters and FLOPS. |
Excessive-Performing Video Fashions
Video understanding is likely one of the key challenges in pc imaginative and prescient, so we evaluated TokenLearner on a number of video classification datasets. This was accomplished by including TokenLearner into Video Imaginative and prescient Transformers (ViViT), which could be regarded as a spatio-temporal model of ViT. TokenLearner discovered 8 (or 16) tokens per timestep.
When mixed with ViViT, TokenLearner obtains state-of-the-art (SOTA) efficiency on a number of common video benchmarks, together with Kinetics-400, Kinetics-600, Charades, and AViD, outperforming the earlier Transformer fashions on Kinetics-400 and Kinetics-600 in addition to earlier CNN fashions on Charades and AViD.
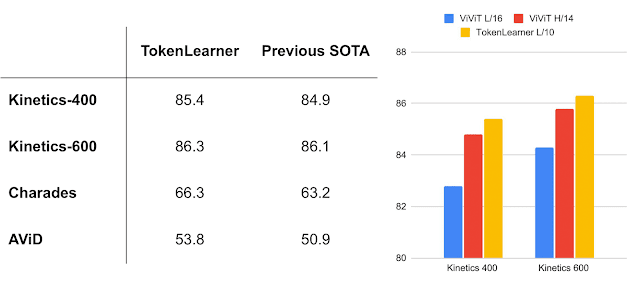 |
| Fashions with TokenLearner outperform state-of-the-art on common video benchmarks (captured from Nov. 2021). Left: common video classification duties. Proper: comparability to ViViT fashions. |
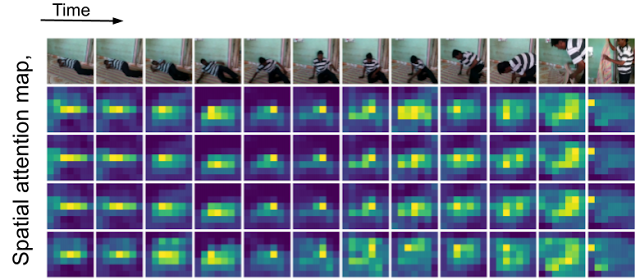 |
| Visualization of the spatial consideration maps in TokenLearner, over time. Because the particular person is shifting within the scene, TokenLearner pays consideration to totally different spatial areas to tokenize. |
Conclusion
Whereas Imaginative and prescient Transformers function highly effective fashions for pc imaginative and prescient, a lot of tokens and their related computation quantity have been a bottleneck for his or her software to bigger photos and longer movies. On this challenge, we illustrate that retaining such a lot of tokens and totally processing them over your complete set of layers shouldn’t be essential. Additional, we exhibit that by studying a module that extracts tokens adaptively based mostly on the enter picture permits attaining even higher efficiency whereas saving compute. The proposed TokenLearner was significantly efficient in video illustration studying duties, which we confirmed with a number of public datasets. A preprint of our work in addition to code are publicly accessible.
Acknowledgement
We thank our co-authors: AJ Piergiovanni, Mostafa Dehghani, and Anelia Angelova. We additionally thank the Robotics at Google staff members for the motivating discussions.
[ad_2]

