

[ad_1]
Getting the inner linking optimized is essential when you care about your website pages having sufficient authority to rank for his or her goal key phrases. By inner linking what we imply are pages in your web site receiving hyperlinks from different pages.
That is essential as a result of that is the premise by which Google and different searches compute the significance of the web page relative to different pages in your web site.
It additionally impacts how probably a consumer would uncover content material in your website. Content material discovery is the premise of the Google PageRank algorithm.
Immediately, we’re exploring a data-driven method to enhancing the inner linking of an internet site for the needs of simpler technical website search engine optimisation. That’s to make sure the distribution of inner area authority is optimized in keeping with the location construction.
Enhancing Inner Hyperlink Buildings With Information Science
Our data-driven method will deal with only one side of optimizing the inner hyperlink structure, which is to mannequin the distribution of inner hyperlinks by website depth after which goal the pages which are missing hyperlinks for his or her specific website depth.
Commercial
Proceed Studying Under
We begin by importing the libraries and information, cleansing up the column names earlier than previewing them:
import pandas as pd
import numpy as np
site_name="ON24"
site_filename="on24"
web site="www.on24.com"

# import Crawl Information
crawl_data = pd.read_csv('information/'+ site_filename + '_crawl.csv')
crawl_data.columns = crawl_data.columns.str.change(' ','_')
crawl_data.columns = crawl_data.columns.str.change('.','')
crawl_data.columns = crawl_data.columns.str.change('(','')
crawl_data.columns = crawl_data.columns.str.change(')','')
crawl_data.columns = map(str.decrease, crawl_data.columns)
print(crawl_data.form)
print(crawl_data.dtypes)
Crawl_data

(8611, 104)

url                          object
base_url                     object
crawl_depth                  object
crawl_status                 object
host                         object
                             ...
redirect_type                object
redirect_url                 object
redirect_url_status          object
redirect_url_status_code     object
unnamed:_103                float64
Size: 104, dtype: object
 Andreas Voniatis, November 2021
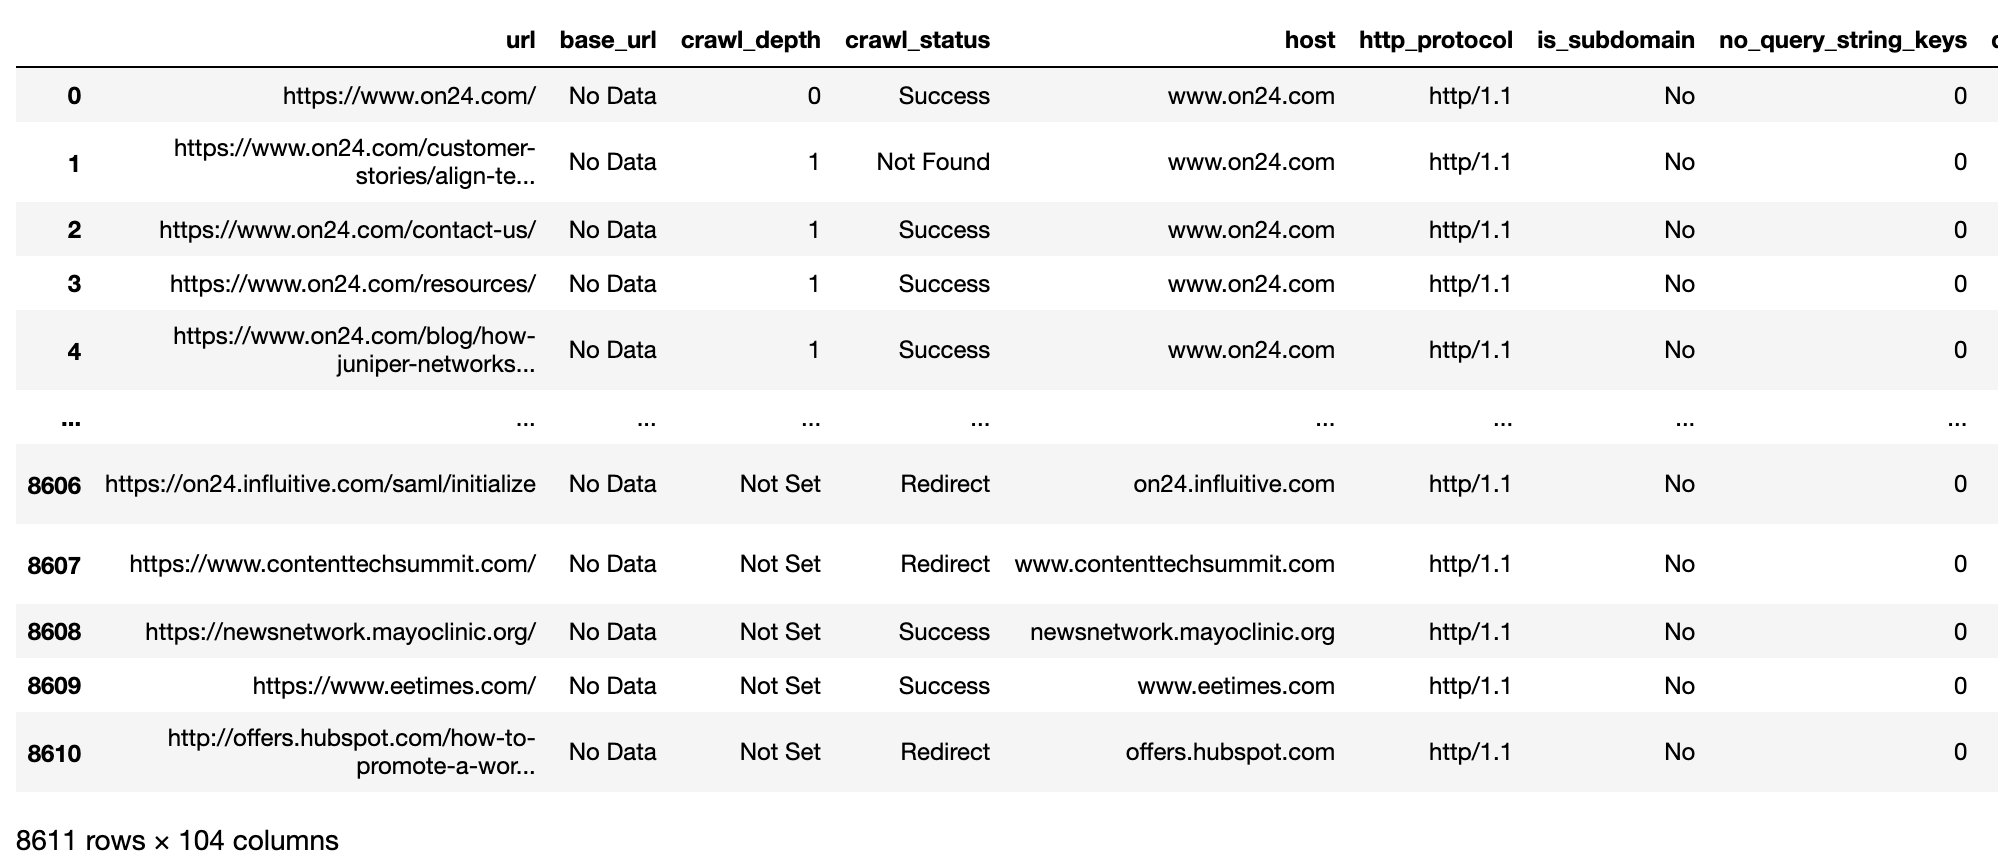
The above reveals a preview of the info imported from the Sitebulb desktop crawler software. There are over 8,000 rows and never all of them will likely be unique to the area, as it’ll additionally embody useful resource URLs and exterior outbound hyperlink URLs.
We even have over 100 columns which are superfluous to necessities, so some column choice will likely be required.
Commercial
Proceed Studying Under
Earlier than we get into that, nevertheless, we need to rapidly see what number of website ranges there are:
crawl_depth
0             1
1            70
10            5
11            1
12            1
13            2
14            1
2           303
3           378
4           347
5           253
6           194
7            96
8            33
9            19
Not Set    2351
dtype: int64
So from the above, we are able to see that there are 14 website ranges and most of those usually are not discovered within the website structure, however within the XML sitemap.
You could discover that Pandas (the Python bundle for dealing with information) orders the location ranges by digit.
That’s as a result of the location ranges are at this stage character strings versus numeric. This will likely be adjusted in later code, as it’ll have an effect on information visualization (‘viz’).
Now, we’ll filter rows and choose columns.
# Filter for redirected and reside hyperlinks
redir_live_urls = crawl_data[['url', 'crawl_depth', 'http_status_code', 'indexable_status', 'no_internal_links_to_url', 'host', 'title']]
redir_live_urls = redir_live_urls.loc[redir_live_urls.http_status_code.str.startswith(('2'), na=False)]
redir_live_urls['crawl_depth'] = redir_live_urls['crawl_depth'].astype('class')
redir_live_urls['crawl_depth'] = redir_live_urls['crawl_depth'].cat.reorder_categories(['0', '1', '2', '3', '4',
                                                                                 '5', '6', '7', '8', '9',
                                                                                        '10', '11', '12', '13', '14',
                                                                                        'Not Set',
                                                                                       ])
redir_live_urls = redir_live_urls.loc[redir_live_urls.host == website]
del redir_live_urls['host']
print(redir_live_urls.form)
Redir_live_urls

(4055, 6)
 Andreas Voniatis, November 2021
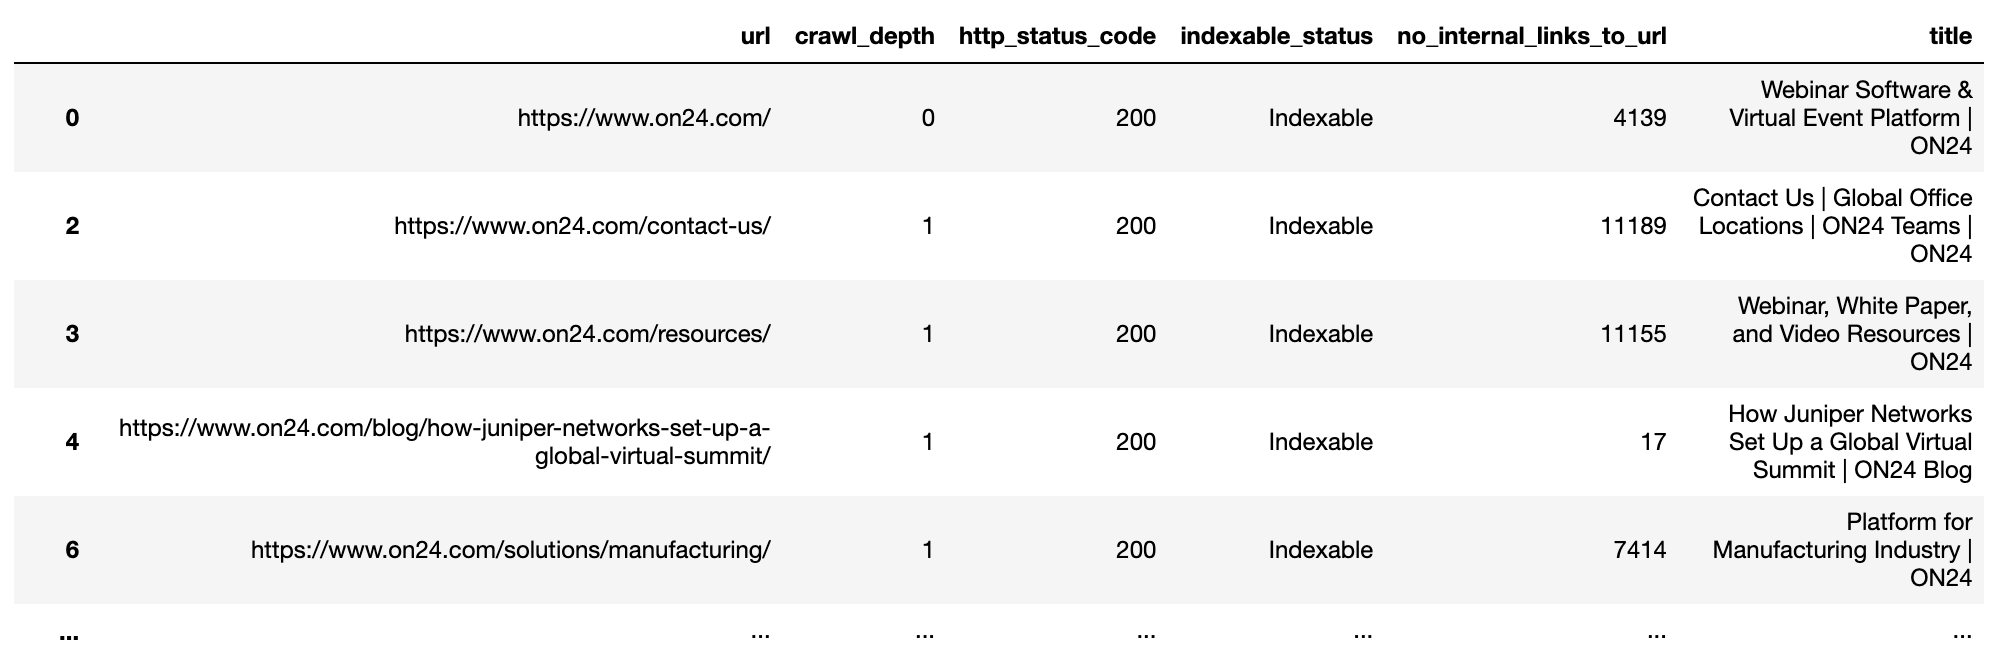
By filtering rows for indexable URLs and choosing the related columns we now have a extra streamlined information body (suppose Pandas model of a spreadsheet tab).
Exploring The Distribution Of Inner Hyperlinks
Now we’re able to information viz the info and get a really feel of how the inner hyperlinks are distributed general and by website depth.
from plotnine import *
import matplotlib.pyplot as plt
pd.set_option('show.max_colwidth', None)
%matplotlib inline

# Distribution of inner hyperlinks to URL by website stage
ove_intlink_dist_plt = (ggplot(redir_live_urls, aes(x = 'no_internal_links_to_url')) +
                    geom_histogram(fill="blue", alpha = 0.6, bins = 7) +
                    labs(y = '# Inner Hyperlinks to URL') +
                    theme_classic() +
                    theme(legend_position = 'none')
                   )

ove_intlink_dist_plt
 Andreas Voniatis, November 2021
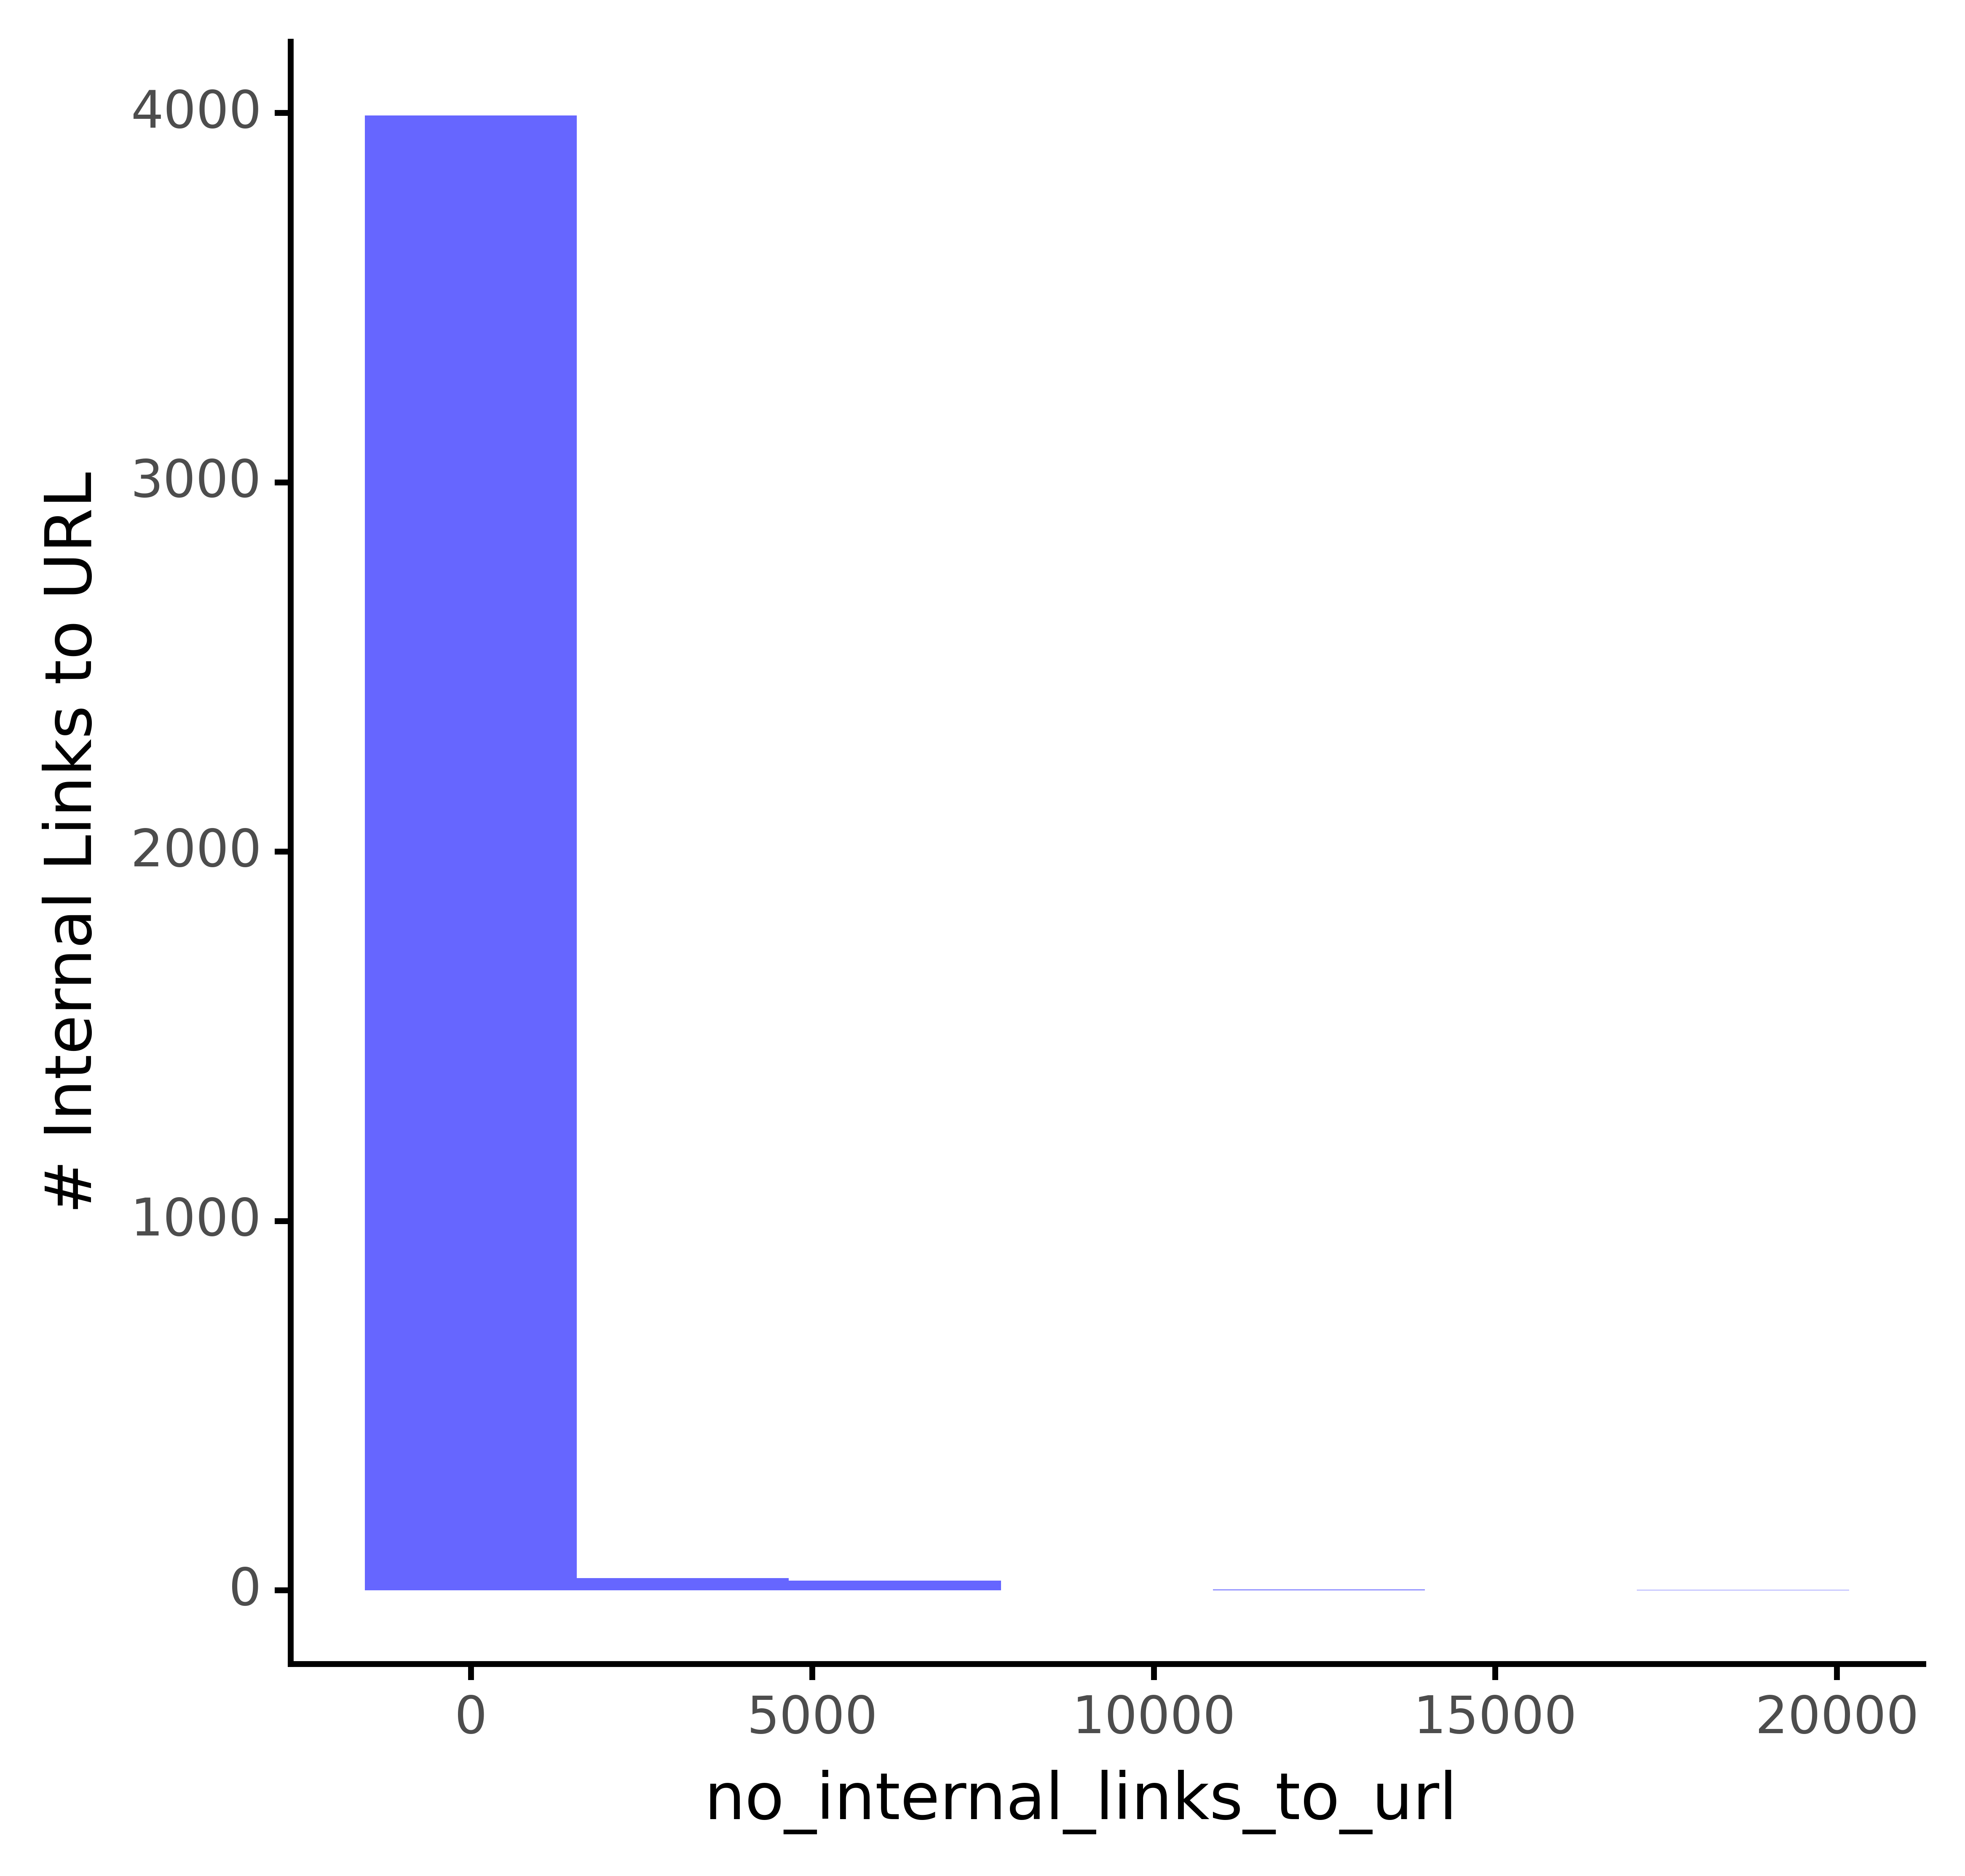
From the above we are able to see overwhelmingly that the majority pages haven’t any hyperlinks, so enhancing the inner linking could be a major alternative to enhance the search engine optimisation right here.
Let’s get some stats on the website stage.
Commercial
Proceed Studying Under
crawl_depth
0             1
1            70
10            5
11            1
12            1
13            2
14            1
2           303
3           378
4           347
5           253
6           194
7            96
8            33
9            19
Not Set    2351
dtype: int64
The desk above reveals the tough distribution of inner hyperlinks by website stage, together with the common (imply) and median (50% quantile).
That is together with the variation inside the website stage (std for normal deviation), which tells us how near the common the pages are inside the website stage; i.e., how constant the inner hyperlink distribution is with the common.
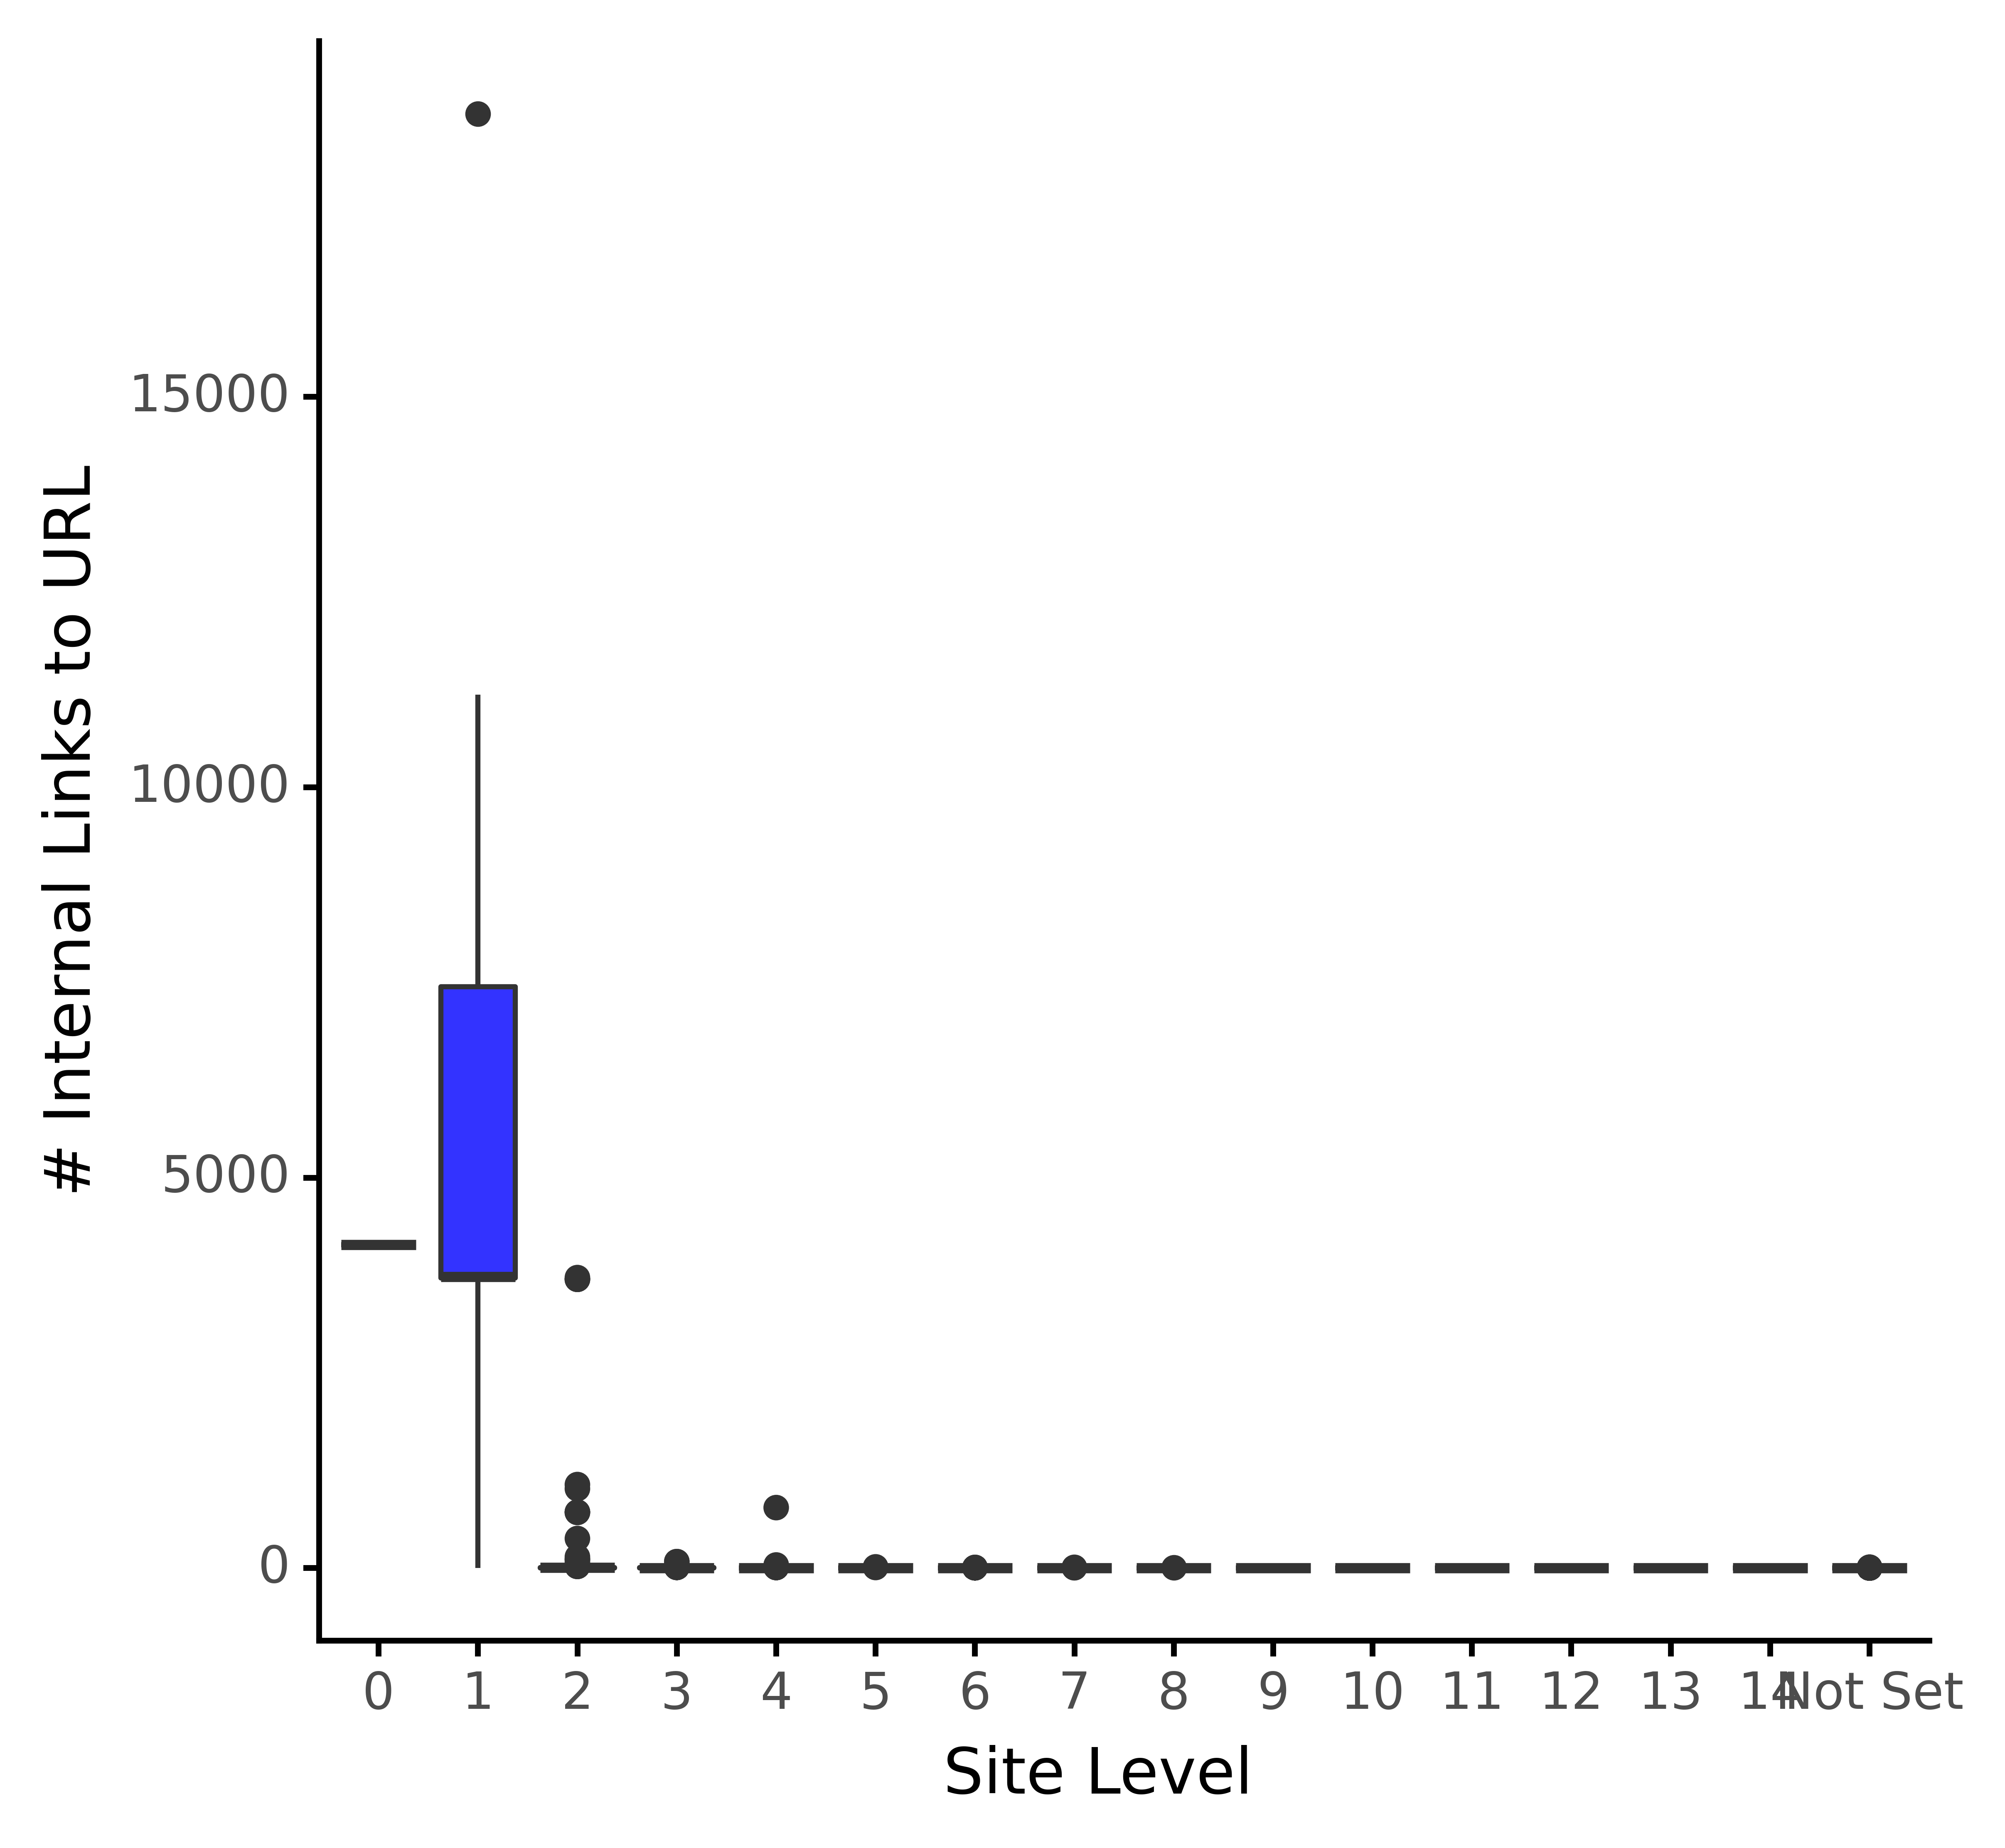
We are able to surmise from the above that the common by site-level, apart from the house web page (crawl depth 0) and the primary stage pages (crawl depth 1), ranges from 0 to 4 per URL.
For a extra visible method:
# Distribution of inner hyperlinks to URL by website stage
intlink_dist_plt = (ggplot(redir_live_urls, aes(x = 'crawl_depth', y = 'no_internal_links_to_url')) +
                    geom_boxplot(fill="blue", alpha = 0.8) +
                    labs(y = '# Inner Hyperlinks to URL', x = 'Web site Stage') +
                    theme_classic() +
                    theme(legend_position = 'none')
                   )

intlink_dist_plt.save(filename="photos/1_intlink_dist_plt.png", top=5, width=5, items="in", dpi=1000)
intlink_dist_plt
 Andreas Voniatis, November 2021
The above plot confirms our earlier feedback that the house web page and the pages instantly linked from it obtain the lion’s share of the hyperlinks.
Commercial
Proceed Studying Under
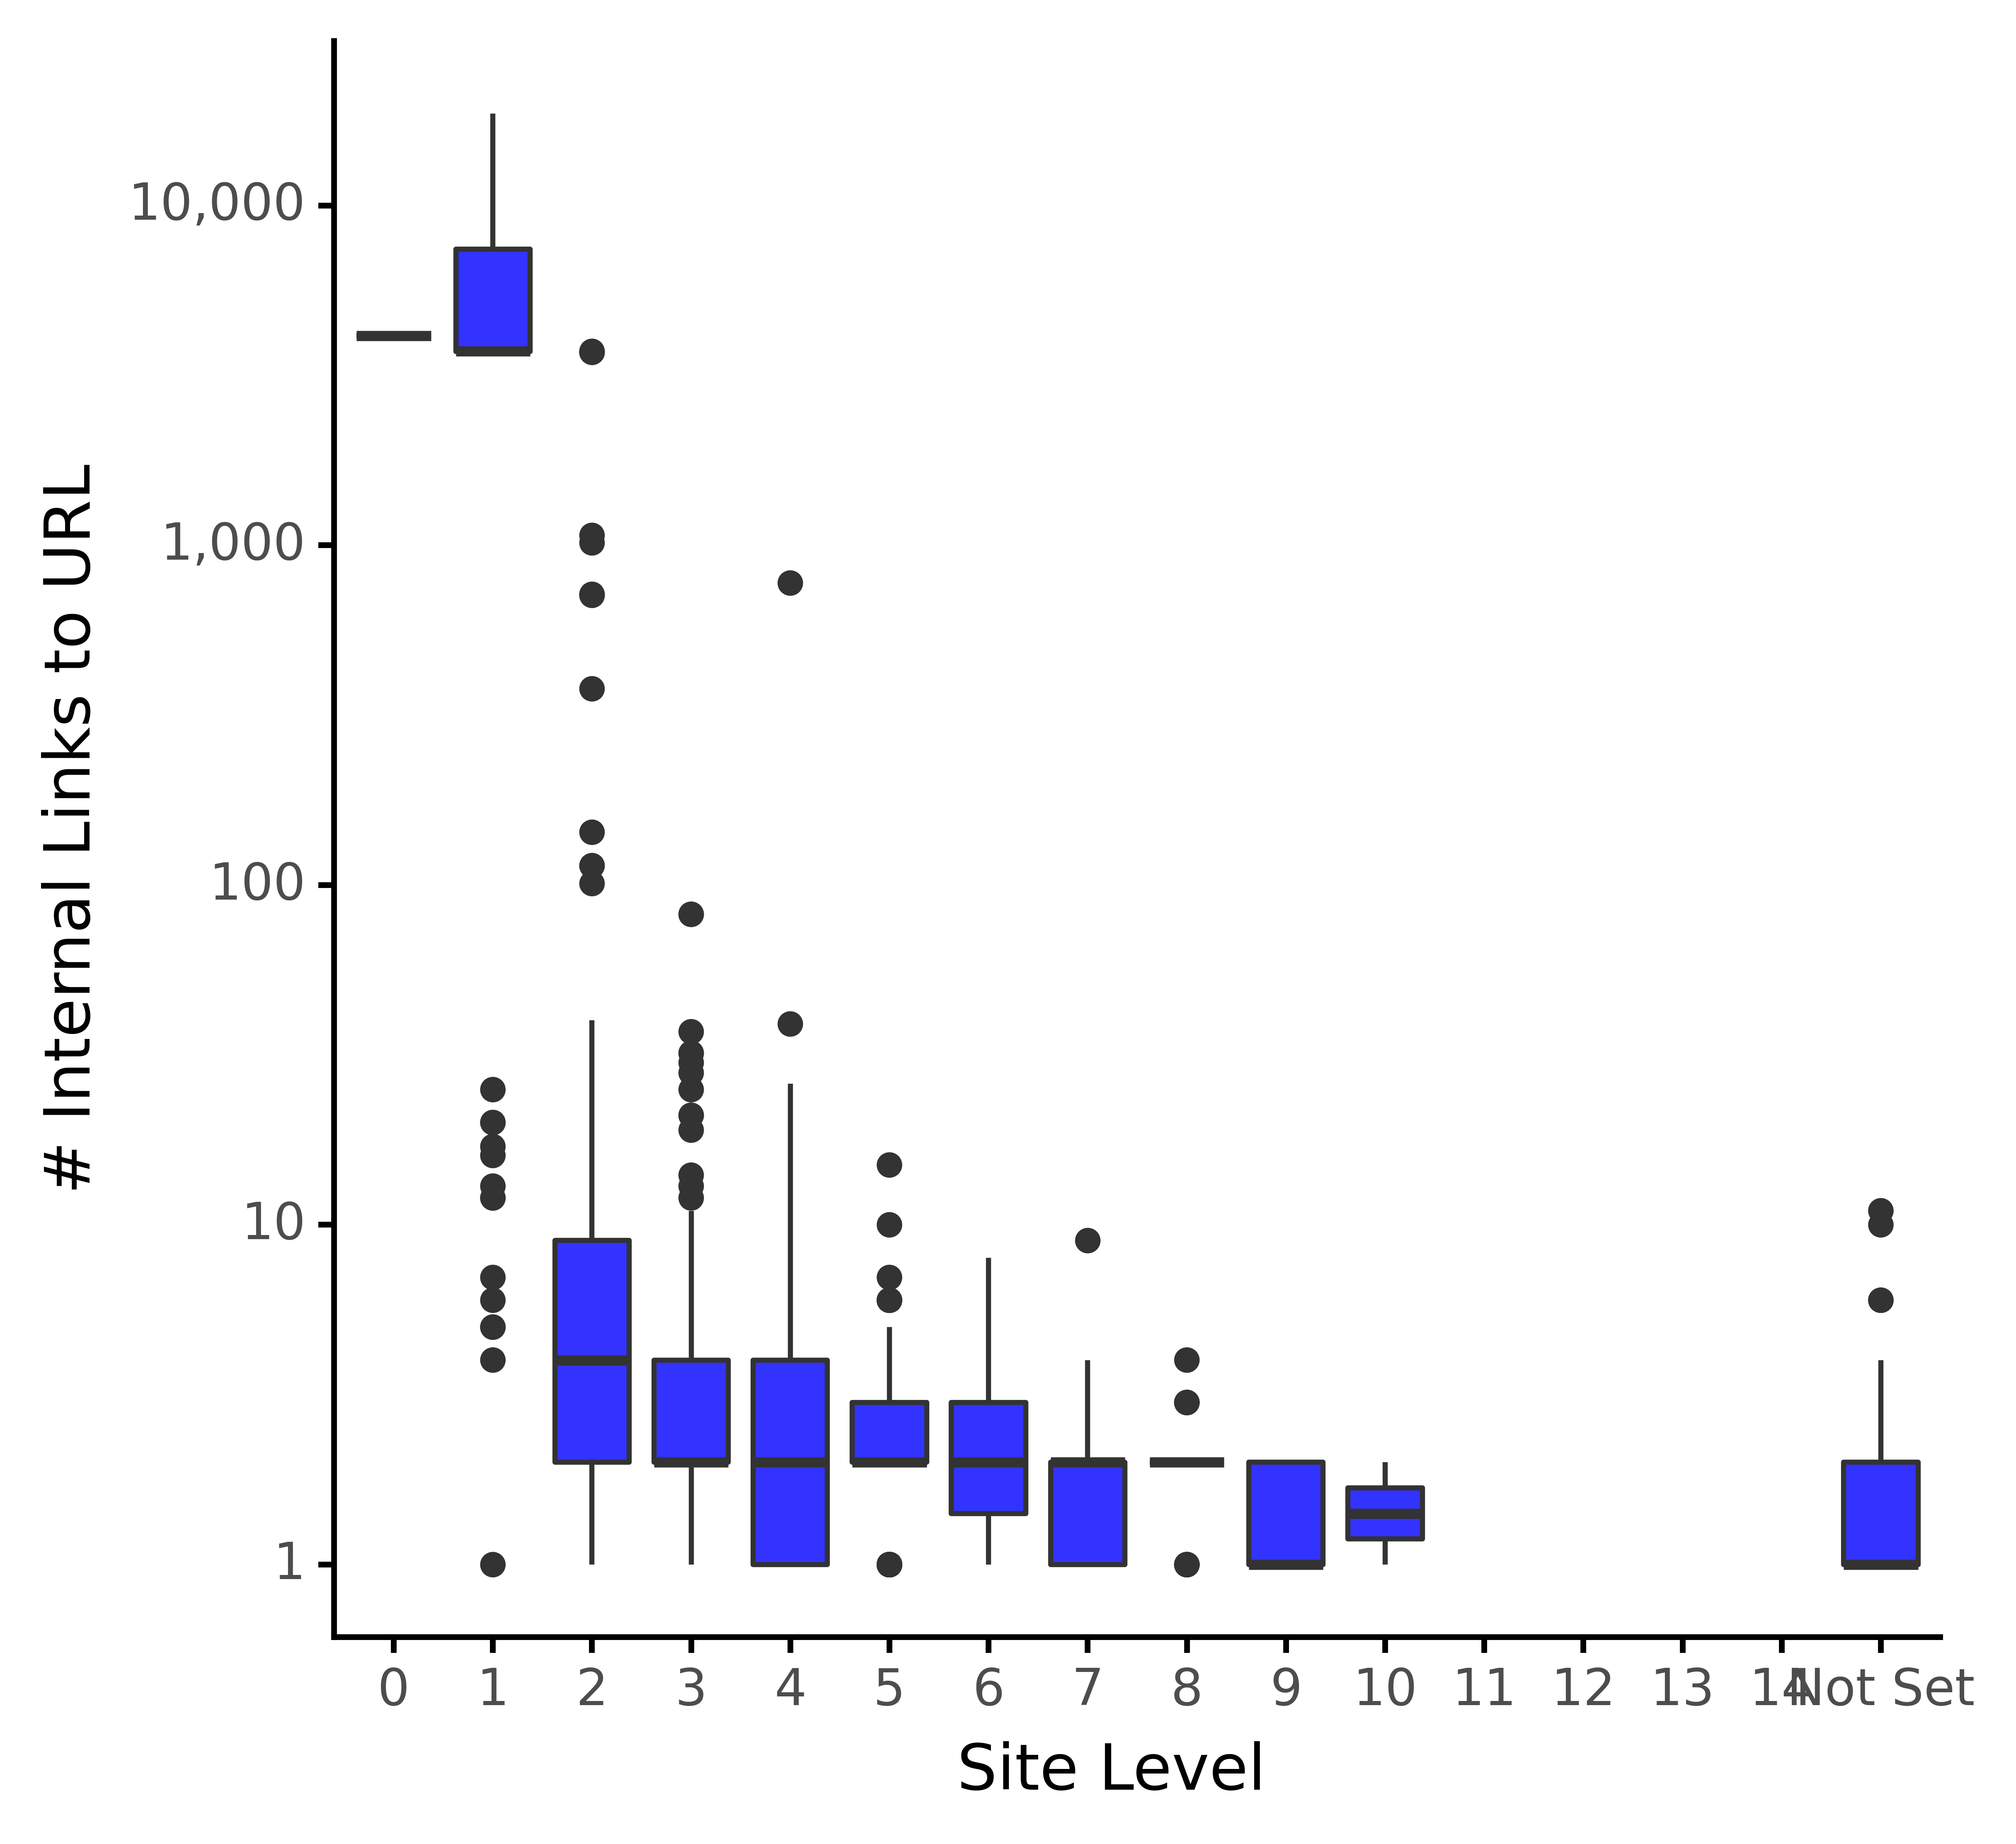
With the scales as they’re, we don’t have a lot of a view on the distribution of the decrease ranges. We’ll amend this by taking a logarithm of the y axis:
# Distribution of inner hyperlinks to URL by website stage
from mizani.formatters import comma_format

intlink_dist_plt = (ggplot(redir_live_urls, aes(x = 'crawl_depth', y = 'no_internal_links_to_url')) +
                    geom_boxplot(fill="blue", alpha = 0.8) +
                    labs(y = '# Inner Hyperlinks to URL', x = 'Web site Stage') +
                    scale_y_log10(labels = comma_format()) +
                    theme_classic() +
                    theme(legend_position = 'none')
                   )

intlink_dist_plt.save(filename="photos/1_log_intlink_dist_plt.png", top=5, width=5, items="in", dpi=1000)
intlink_dist_plt
 Andreas Voniatis, November 2021
The above reveals the identical distribution of the hyperlinks with the logarithmic view, which helps us affirm the distribution averages for the decrease ranges. That is a lot simpler to visualise.
Given the disparity between the primary two website ranges and the remaining website, that is indicative of a skewed distribution.
Commercial
Proceed Studying Under
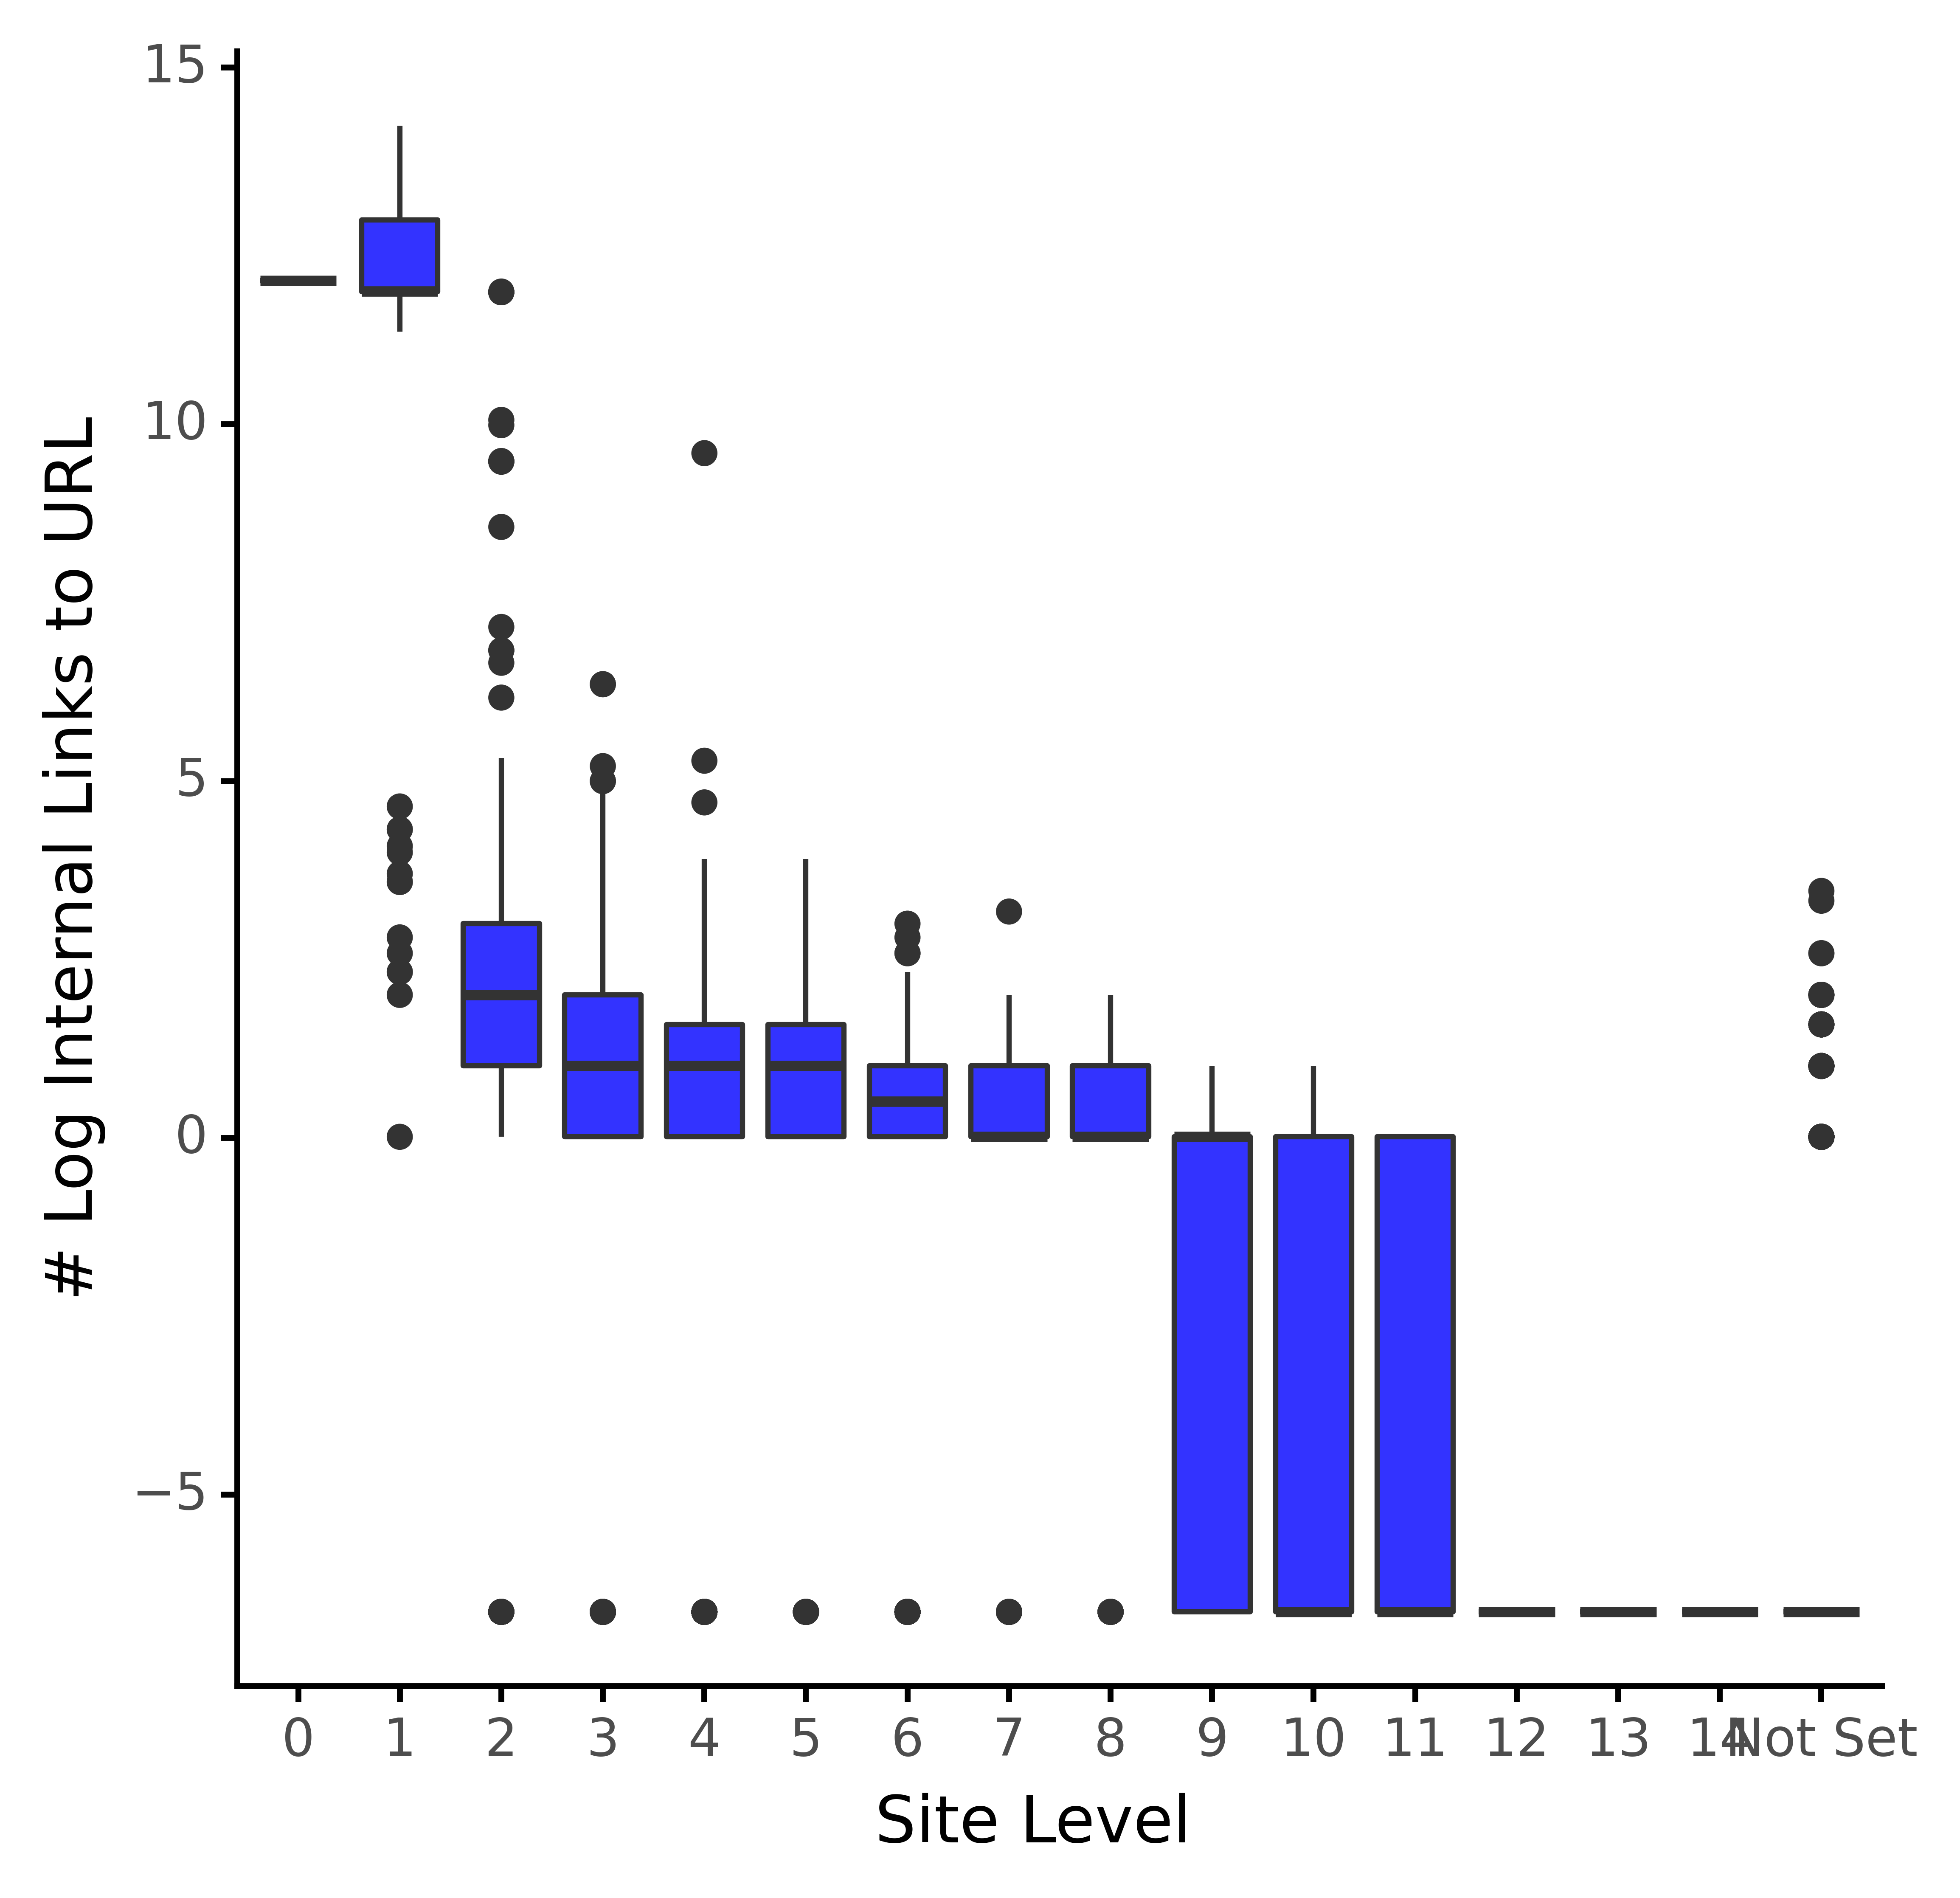
In consequence, I’ll take a logarithm of the inner hyperlinks, which can assist normalize the distribution.
Now we have now the normalized variety of hyperlinks, which we’ll visualize:
# Distribution of inner hyperlinks to URL by website stage
intlink_dist_plt = (ggplot(redir_live_urls, aes(x = 'crawl_depth', y = 'log_intlinks')) +
                    geom_boxplot(fill="blue", alpha = 0.8) +
                    labs(y = '# Log Inner Hyperlinks to URL', x = 'Web site Stage') +
                    #scale_y_log10(labels = comma_format()) +
                    theme_classic() +
                    theme(legend_position = 'none')
                   )

intlink_dist_plt
 Andreas Voniatis, November 2021
From the above, the distribution seems to be loads much less skewed, because the packing containers (interquartile ranges) have a extra gradual step change from website stage to the location stage.
This units us up properly for analyzing the info earlier than diagnosing which URLs are under-optimized from an inner hyperlink standpoint.
Commercial
Proceed Studying Under
Quantifying The Points
The code beneath will calculate the decrease thirty fifth quantile (information science time period for percentile) for every website depth.
# inner hyperlinks in beneath/over indexing at website stage
# depend of URLs beneath listed for inner hyperlink counts

quantiled_intlinks = redir_live_urls.groupby('crawl_depth').agg({'log_intlinks':
                                                                 [quantile_lower]}).reset_index()
quantiled_intlinks = quantiled_intlinks.rename(columns = {'crawl_depth_': 'crawl_depth',
                                                          'log_intlinks_quantile_lower': 'sd_intlink_lowqua'})
quantiled_intlinks
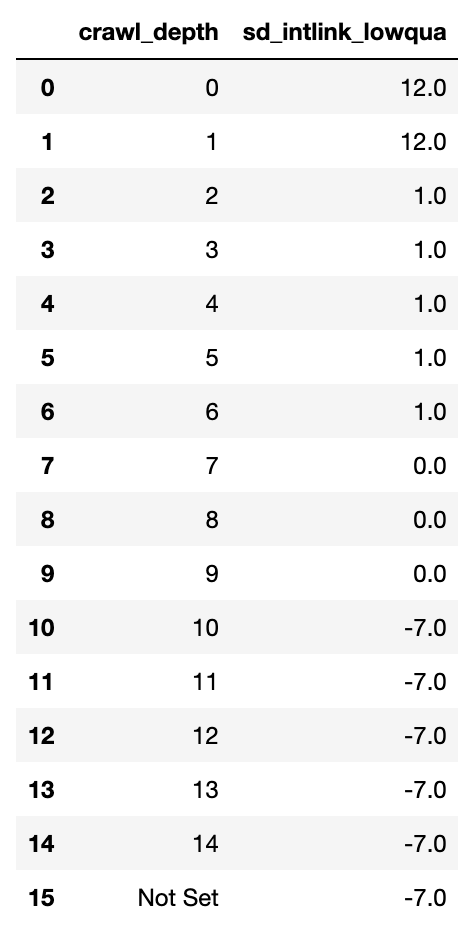 Andreas Voniatis, November 2021
The above reveals the calculations. The numbers are meaningless to an search engine optimisation practitioner at this stage, as they’re arbitrary and for the aim of offering a cut-off for under-linked URLs at every website stage.
Now that we have now the desk, we’ll merge these with the primary information set to work out whether or not the URL row by row is under-linked or not.
Commercial
Proceed Studying Under
# be a part of quantiles to fundamental df after which depend
redir_live_urls_underidx = redir_live_urls.merge(quantiled_intlinks, on = 'crawl_depth', how = 'left')

redir_live_urls_underidx['sd_int_uidx'] = redir_live_urls_underidx.apply(sd_intlinkscount_underover, axis=1)
redir_live_urls_underidx['sd_int_uidx'] = np.the place(redir_live_urls_underidx['crawl_depth'] == 'Not Set', 1,
                                                   redir_live_urls_underidx['sd_int_uidx'])

redir_live_urls_underidx
Now we have now a knowledge body with every URL marked as under-linked beneath the ‘’sd_int_uidx’ column as a 1.
This places us ready to sum the quantity of under-linked website pages by website depth:
# Summarise int_udx by website stage
intlinks_agged = redir_live_urls_underidx.groupby('crawl_depth').agg({'sd_int_uidx': ['sum', 'count']}).reset_index()
intlinks_agged = intlinks_agged.rename(columns = {'crawl_depth_': 'crawl_depth'})
intlinks_agged['sd_uidx_prop'] = intlinks_agged.sd_int_uidx_sum / intlinks_agged.sd_int_uidx_count * 100
print(intlinks_agged)
  crawl_depth  sd_int_uidx_sum  sd_int_uidx_count  sd_uidx_prop
0            0                0                  1      0.000000
1            1               41                 70     58.571429
2            2               66                303     21.782178
3            3              110                378     29.100529
4            4              109                347     31.412104
5            5               68                253     26.877470
6            6               63                194     32.474227
7            7                9                 96      9.375000
8            8                6                 33     18.181818
9            9                6                 19     31.578947
10          10                0                  5      0.000000
11          11                0                  1      0.000000
12          12                0                  1      0.000000
13          13                0                  2      0.000000
14          14                0                  1      0.000000
15     Not Set             2351               2351    100.000000
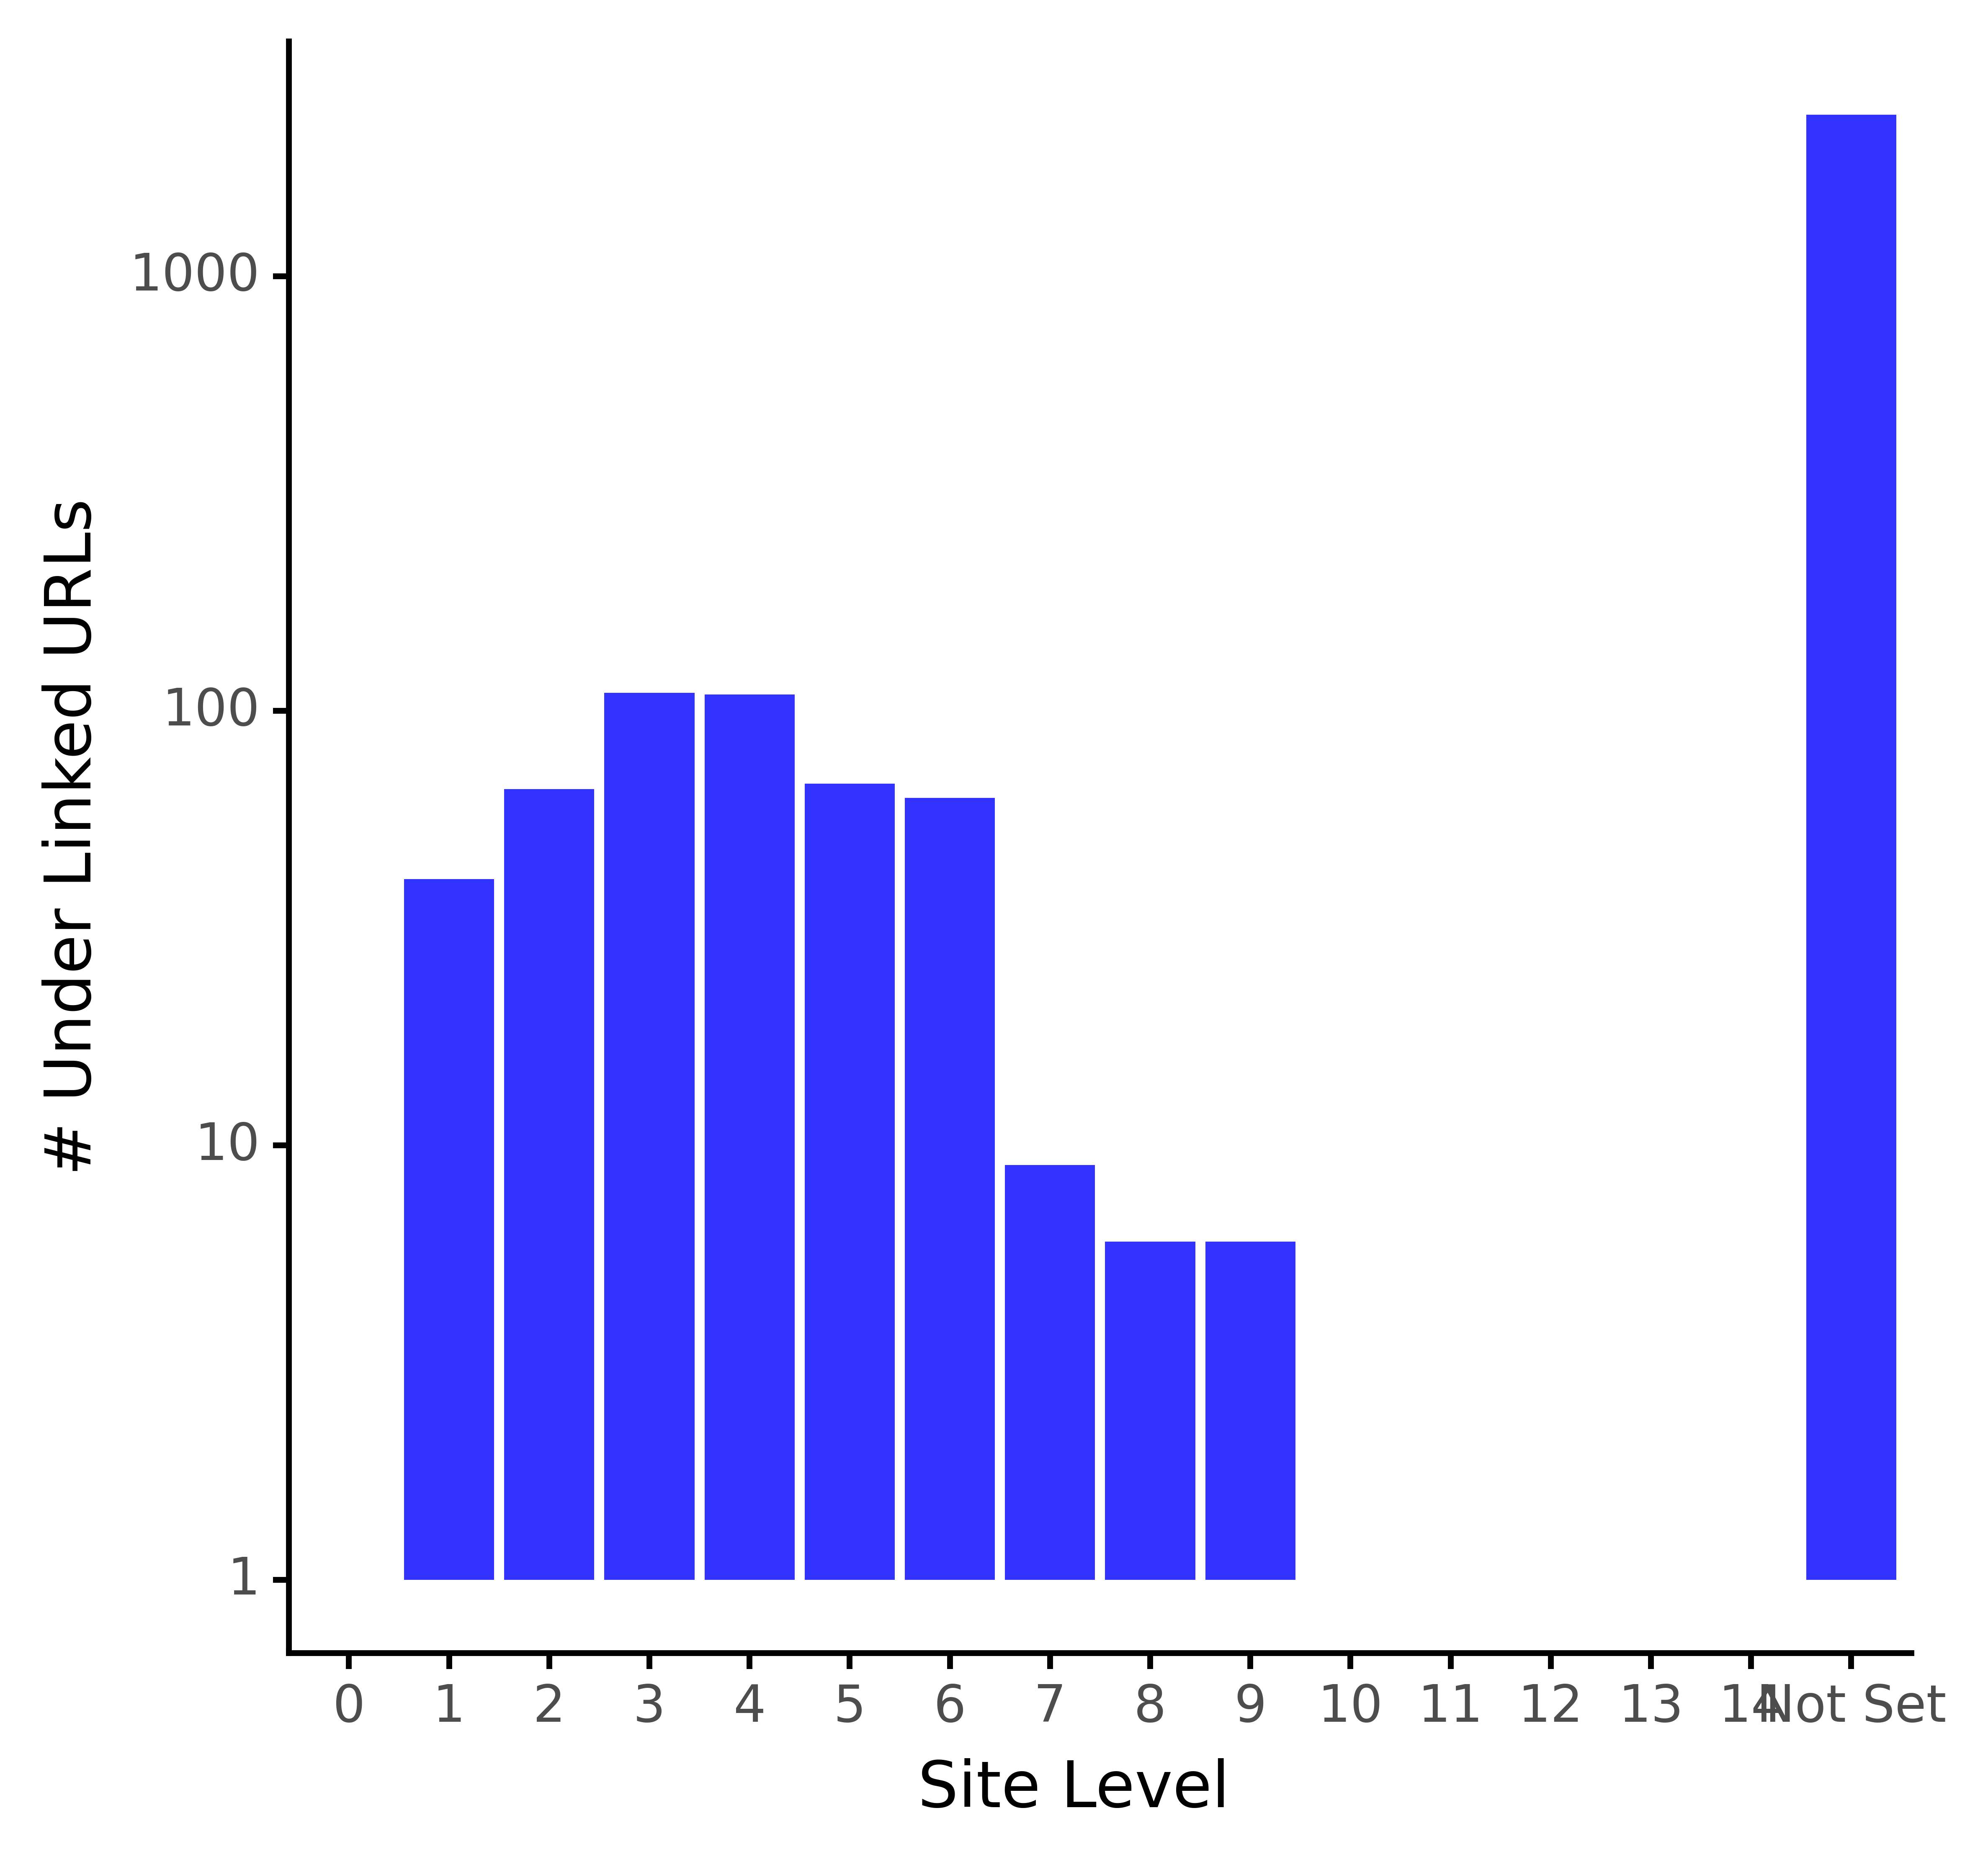
We now see that regardless of the location depth 1 web page having a better than common variety of hyperlinks per URL, there are nonetheless 41 pages which are under-linked.
To be extra visible:
# plot the desk
depth_uidx_plt = (ggplot(intlinks_agged, aes(x = 'crawl_depth', y = 'sd_int_uidx_sum')) +
                    geom_bar(stat="id", fill="blue", alpha = 0.8) +
                    labs(y = '# Underneath Linked URLs', x = 'Web site Stage') +
                    scale_y_log10() +
                    theme_classic() +
                    theme(legend_position = 'none')
                   )

depth_uidx_plt.save(filename="photos/1_depth_uidx_plt.png", top=5, width=5, items="in", dpi=1000)
depth_uidx_plt
 Andreas Voniatis, November 2021
Excluding the XML sitemap URLs, the distribution of under-linked URLs seems to be regular as indicated by the close to bell form. Many of the under-linked URLs are in website ranges 3 and 4.
Commercial
Proceed Studying Under
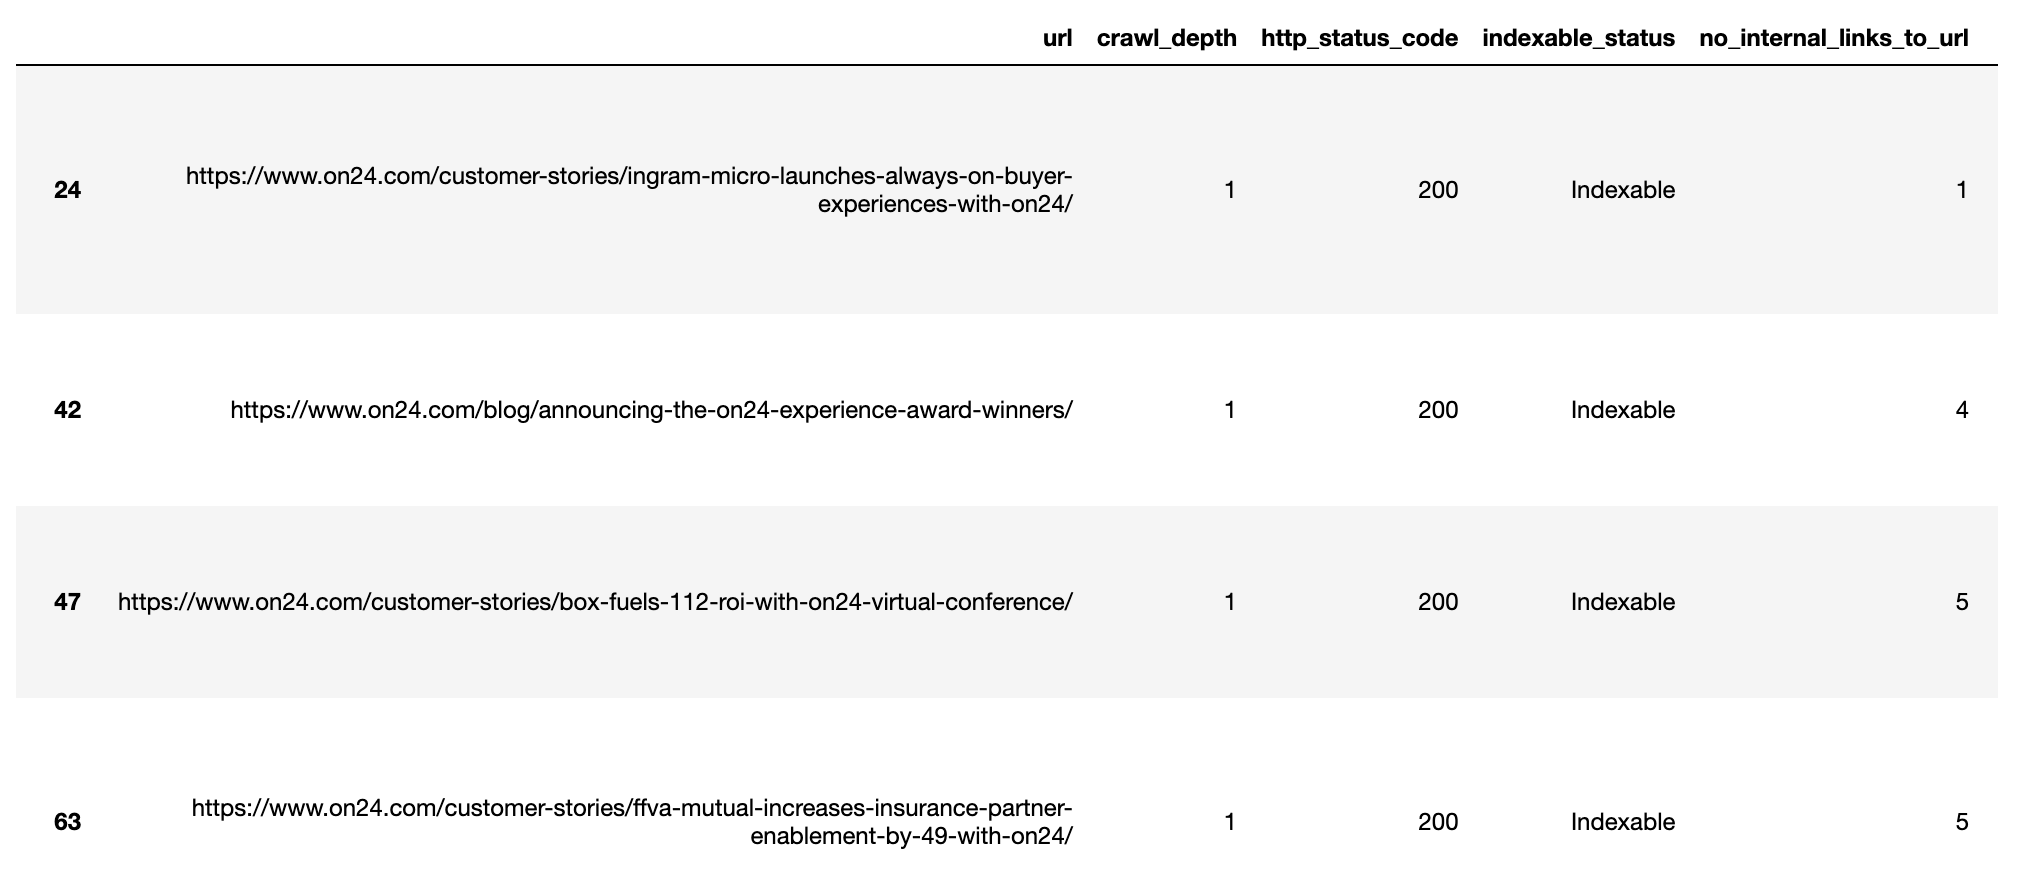
Exporting The Checklist Of Underneath-Linked URLs
Now that we have now a grip on the under-linked URLs by website stage, we are able to export the info and give you inventive options to bridge the gaps in website depth as proven beneath.
# information dump of beneath performing backlinks
underlinked_urls = redir_live_urls_underidx.loc[redir_live_urls_underidx.sd_int_uidx == 1]
underlinked_urls = underlinked_urls.sort_values(['crawl_depth', 'no_internal_links_to_url'])
underlinked_urls.to_csv('exports/underlinked_urls.csv')
underlinked_urls
 Andreas Voniatis, November 2021
Different Information Science Methods For Inner Linking
We briefly coated the motivation for enhancing a website’s inner hyperlinks earlier than exploring how inner hyperlinks are distributed throughout the location by website stage.
Commercial
Proceed Studying Under
Then we proceeded to quantify the extent of the under-linking concern each numerically and visually earlier than exporting the outcomes for suggestions.
Naturally, site-level is only one side of inner hyperlinks that may be explored and analyzed statistically.
Different elements that would apply information science strategies to inner hyperlinks embody and clearly usually are not restricted to:
- Offsite page-level authority.
- Anchor textual content relevance.
- Search intent.
- Search consumer journey.
What elements would you wish to see coated?
Please depart a remark beneath.
Extra assets:
Commercial
Proceed Studying Under
Featured picture: Shutterstock/Optimarc
[ad_2]

